2,067 posts tagged “generative-ai”
Machine learning systems that can generate new content: text, images, audio, video and more.
2026
During the time these agents converted 185,000 lines of C code into 340,000 lines of Rust code (I counted), we merged over 300 commits in the actual curl project. We actually improved curl during these a little more than three weeks. A little over 200 bugfixes actually. 200 bugfixes that none of those rust rewrites have. We also fixed a few vulnerabilities. In another month we have done another 200 and maybe fixed a few more vulnerabilities. Will these clones keep up?
— Daniel Stenberg, Actual curl rewrites in Rust
External sandboxes for coding agents. I've been exploring new ways to sandbox code that is executed by agents, with a focus on making it safer to try out local models without worrying that a mistake or prompt injection attack might cause them to take damaging actions on a machine.
I worked on this project with Prime Radiant, the AI research lab behind Superpowers and other projects.
My post on the Prime Radiant blog introduces the external sandbox pattern, where code executed by the agent runs inside a dedicated sandbox while the agent itself lives outside of that sandbox.
To demonstrate this pattern we've released three sandbox server implementations:
- external-sandbox-v86 runs a Node.js server which then uses v86 to run Alpine Linux inside WebAssembly.
- external-sandbox-container is a Python web server which runs the sandbox in Alpine Linux inside an Apple Containers instance.
- external-sandbox-quicksand is another Python web server, this time using Microsoft's Quicksand sandboxing library, which bundles QEMU and Alpine Linux in a Python package!
Each of these implementations offers the same localhost API. You can then configure Pi, Claude Code, or Codex to send API calls to that sandbox any time they want to execute code.
The sandboxes also include an optional HTTP/HTTPS allow-list proxy, so you can control exactly which hosts your agent's code is allowed to communicate with - plus a credential replacement mechanism to make authenticated API calls without sharing a secret with the agent. Here's the UI you can use to reconfigure that proxy while the sandbox is still running:

I continue to be fascinated by the challenge of safely running untrusted code. This external sandbox pattern provides a neat way to experiment with different approaches.
GPT‑6.2 Astra and GPT‑6.2 Sol. OpenAI:
We’re introducing GPT‑6.2 Astra, our new frontier model for your hardest projects, and GPT‑6.2 Sol, our efficient, versatile model for everyday work.
They're available in the API as gpt-6.2-astra and gpt-6.2-sol. I shipped LLM 0.38 with support for the new models.
6.2 Astra is 80% of the price of 6 Astra - $8/MTok input and $40/MTok output, the same price as Claude Fable 5.2 (which was also 80% of its predecessor). 6 Astra and Fable 5 were both $10/$50. The cached price is an even bigger discount - $0.40/million compared to $1/million for the older model. This is great news for longer running agentic sessions.
GPT-6.2 Sol is the same $2/$10 price as 6.1 Sol and 6 Sol - which are half the price of GPT-5.6 Sol ($4/$20).
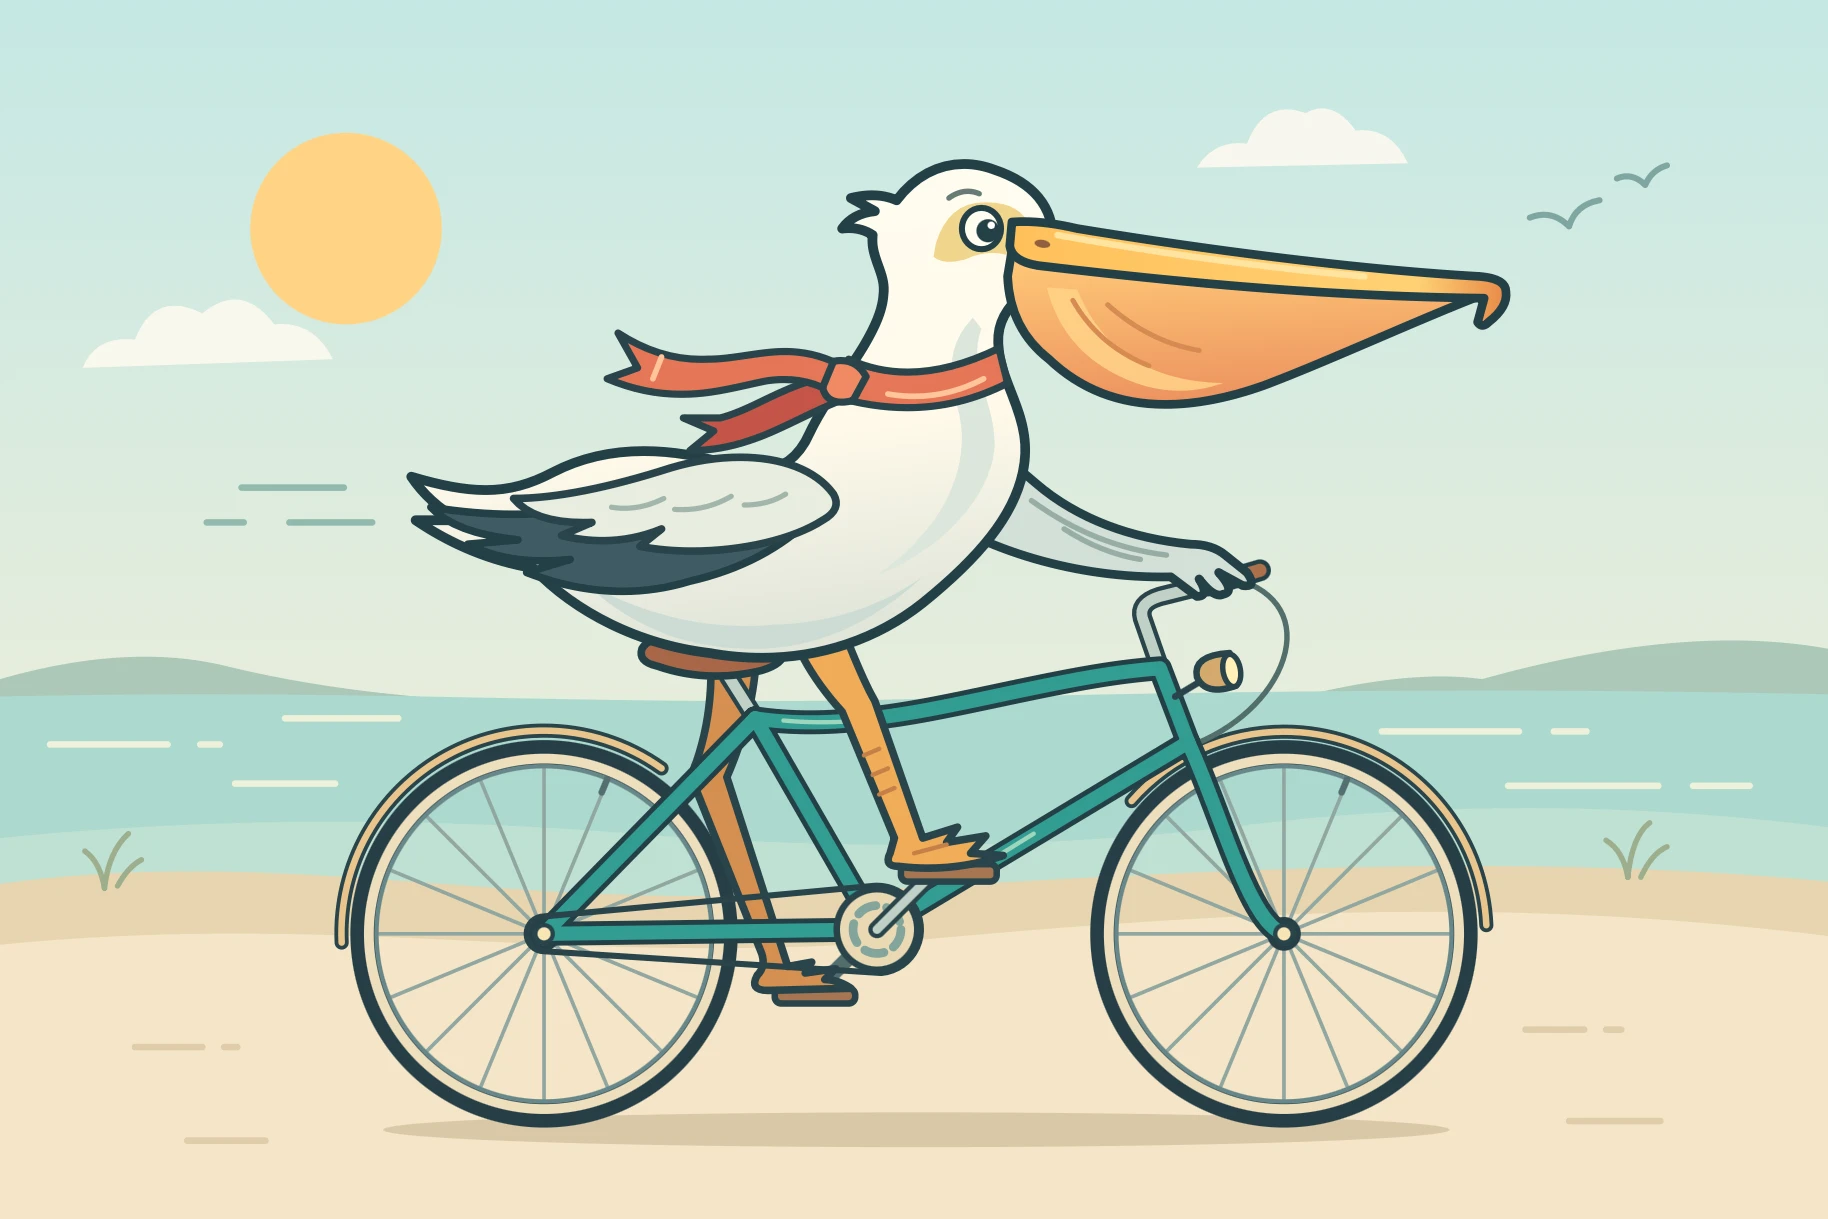
Here are the pelicans for GPT-6.2 Sol and for GPT-6.2 Astra. The 6.2 Astra max pelican looks like this:
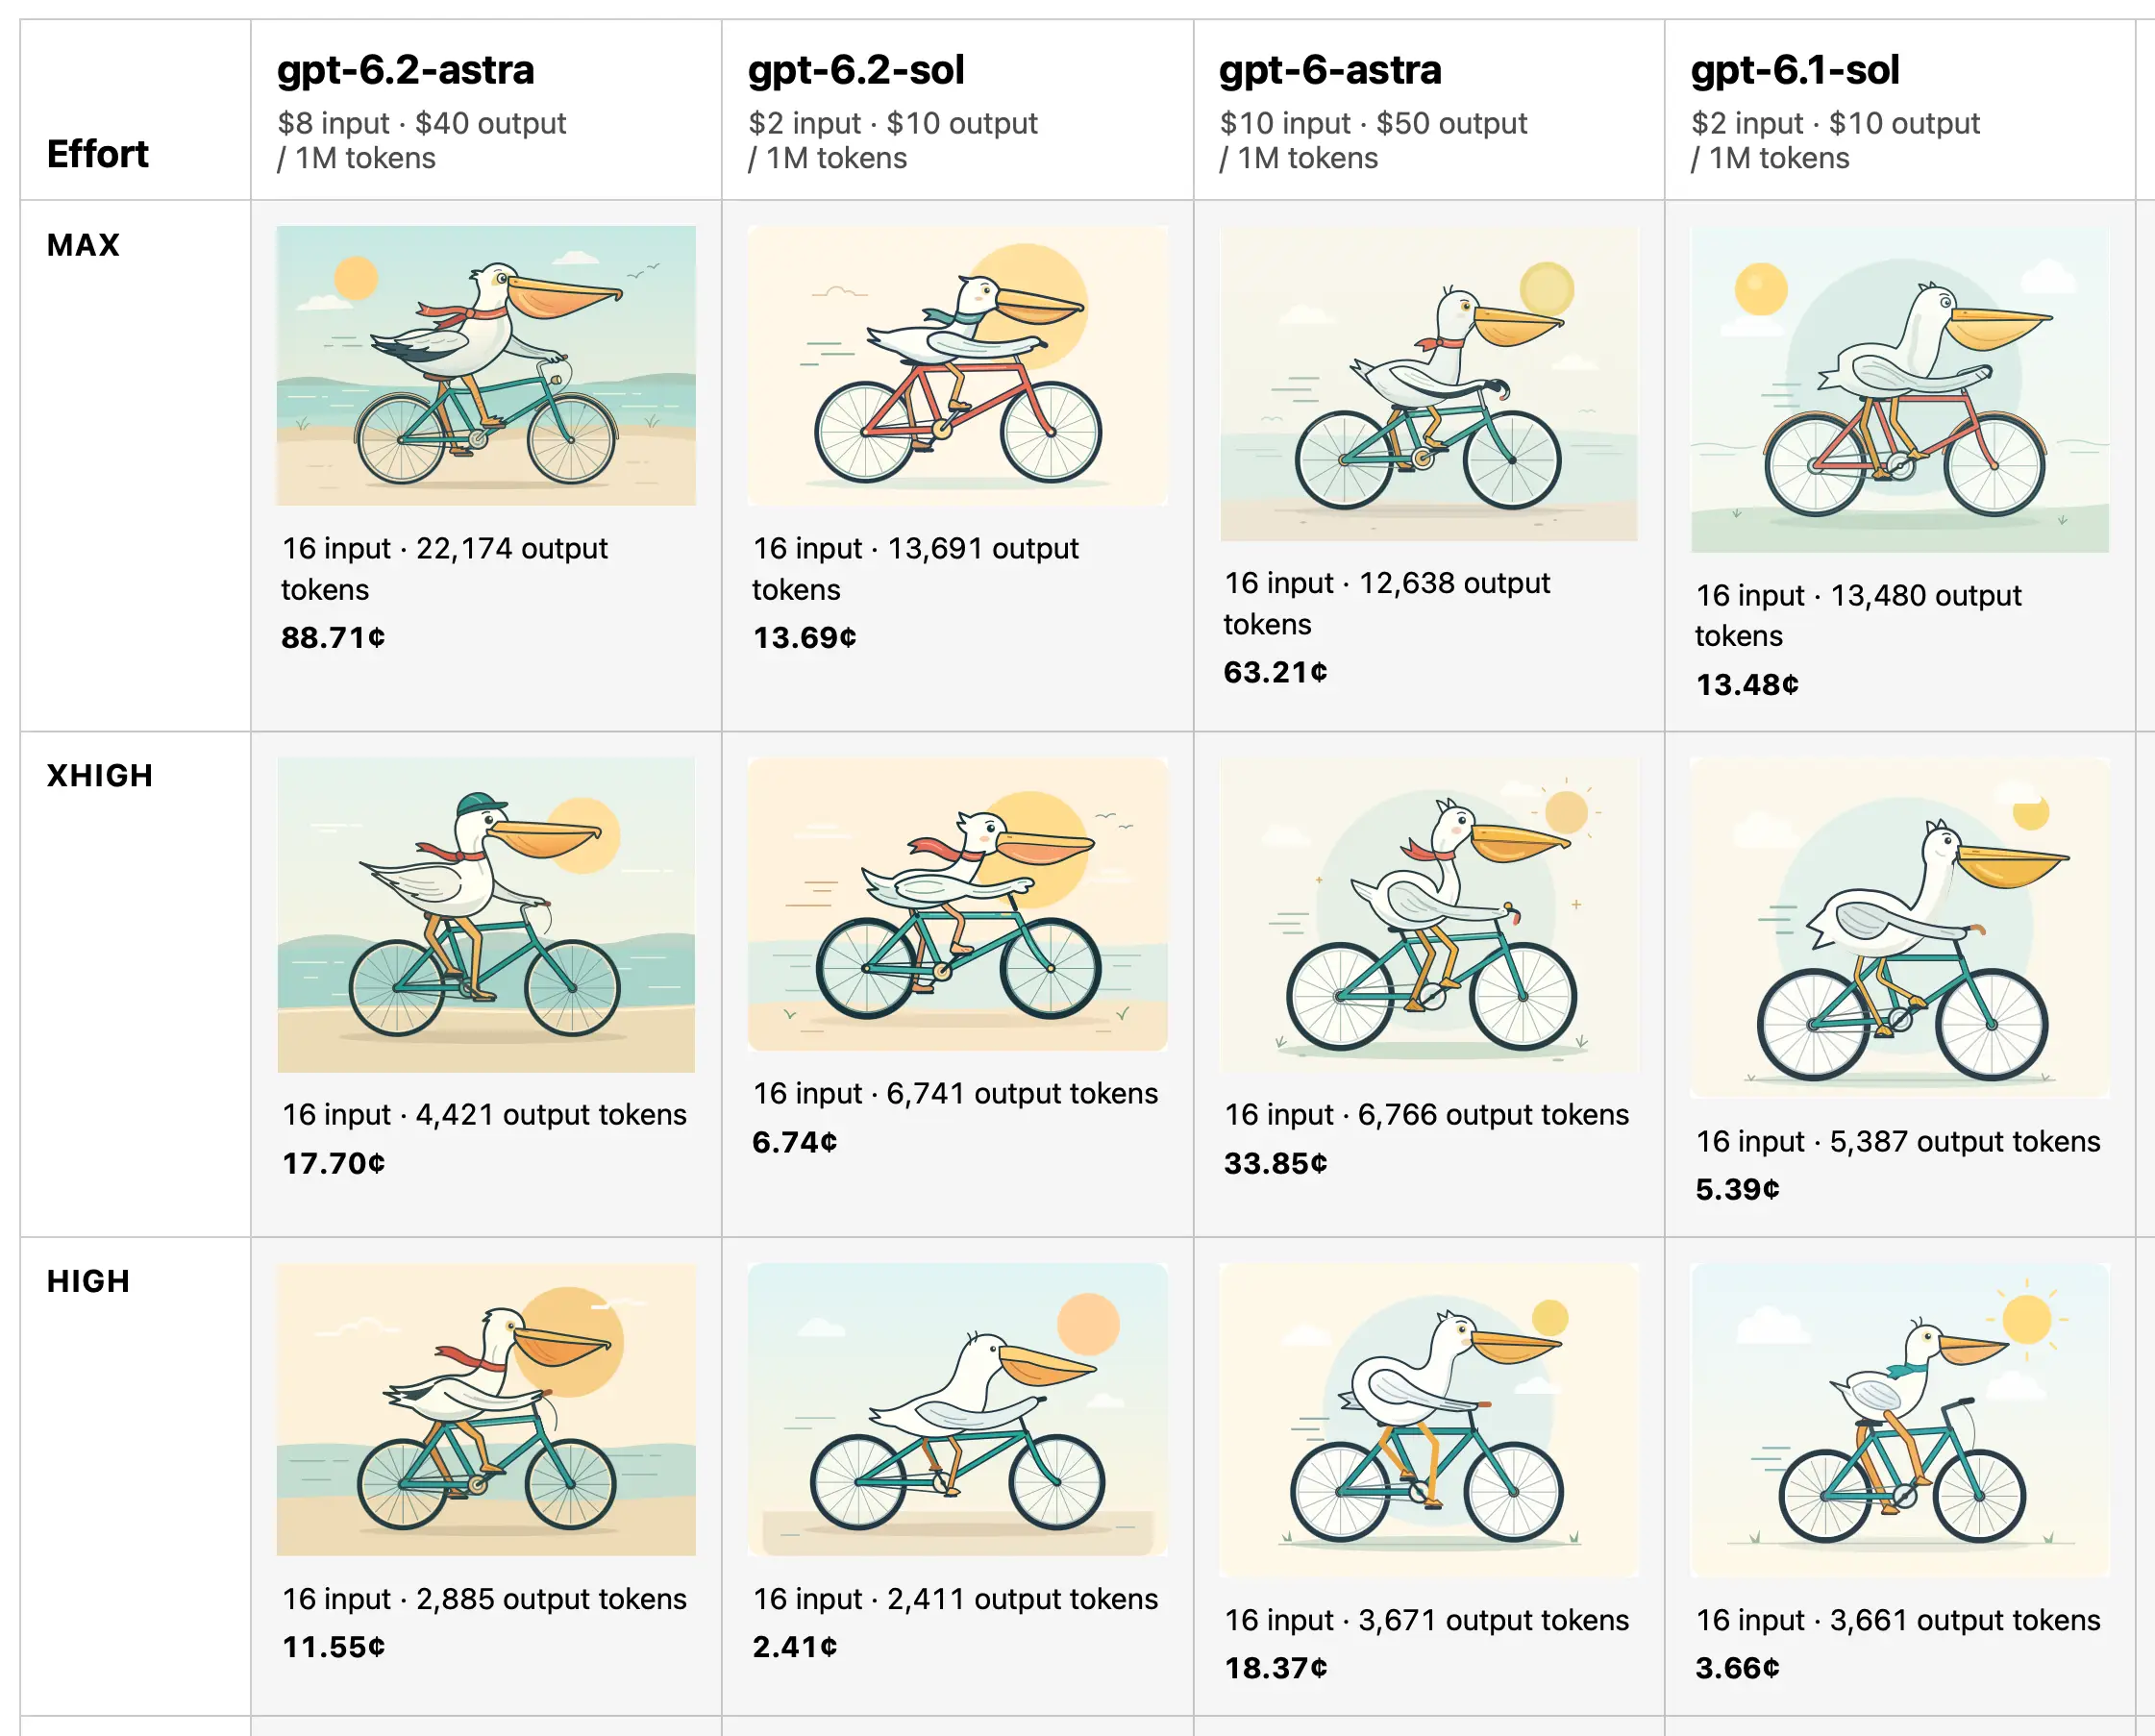
I have a full comparison grid here, but here's how the high/xhigh/max pelicans compare with the previous Sol and Astra releases:
I also ran my most recent benchmark prompt against the two models, using "Ultra' effort levels in the Codex CLI:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data
Here's Sol and here's Astra. Neither of them did a good enough job of morphing Yonkers into a big mech, at least in comparison to Claude Fable 5.2 and Gemini 4 Carbon.
This video showing the Astra and Sol animations playing out at the same time:
I created that video using GPT-6.2 Astra (Ultra) in the Codex desktop app by prompting:
https://static.simonwillison.net/static/2026/yonkers-gpt-6.2-astra-ultra/index.html and https://static.simonwillison.net/static/2026/yonkers-gpt-6.2-sol-ultra/index.html are two videos of the same thing by two different models
I need a video of the first 10 seconds where the top half of the video plays the first and the bottom half plays the second
I need an overlaid label of "GPT-6.2 Astra" on the top half and "GPT-6.2 Sol" on the bottom half. These labels should be tastefully positioned.
Make the video square and 2000x2000 pixels
Then later:
OK make it 20s
Here's the exported transcript.
The buzz around these new models is mixed at the moment. Astra 6.2 isn't scoring quite as high as Fable 5.2 on various benchmarks, and I've seen a few complaints that its communication style can be confusing. Theo Browne's review (in the form of a feedback letter he sent OpenAI during pre-release) has this useful example:
When this model is working on long tasks, it can pull in a lot of subagents and manage them pretty well. It will then proceed to randomly ask you some weird internal implementation detail bullshit that you could not under any earthly circumstance understand, much less have input on.
I sent "/goal make a new level for Outer Wilds". 2 hours in, it's "blocked" because it wanted to ask me "does r24's reviewer write it's clips to 24_g521.mp4 or 24_p11.mp4?"
A bug fix release for LLM, mainly to cover a problem with the most recent Homebrew package of the software.
Homebrew now ships the latest SQLite, 3.54.1, which includes a fix that broke LLM's logging code.
Short version: in SQLite 3.54.0 the following SQL:
select json_object('a', (select json_array(1)))
Returns this:
{"a":[1]}
But in 3.54.1 the same query returns this:
{"a":"[1]"}
According to D. Richard Hipp:
That was a bug fix. Per the documentation, (SELECT json_array(...)) returns SQL text, not JSON. Hence the 3.54.1 behavior is correct and 3.54.0 was a bug.
The workaround looks like this:
select json_object('a', json((select json_array(1))))
The first new Datasette geospatial plugin in quite a while! This one combines the excellent MapLibre GL library with OpenFreeMap, the free vector map server operated by Zsolt Ero (you should sponsor Zsolt on GitHub.)
I built most of this with a single prompt to Claude Fable 5.2:
Look at datasette-cluster-map and datasette-leaflet-geojson plugins, then look at ~/dev/tools/openfreemap-demo.html - then build a brand new Datasette plugin that uses maplibreGL and openfreemap and combines the features of those other two plugins - but be creative and think outside the box for other useful features the plugin might have
"Be creative and think outside the box" resulted in a few neat ideas - my favorite is that it displays SVG previews of GeoJSON shapes, then loads a WebGL preview only when they scroll into view.
I also had Claude build a comprehensive demo which works in the latest Datasette Lite, so you can visit this link to load the plugin and a demo database in your browser via Pyodide and WebAssembly.
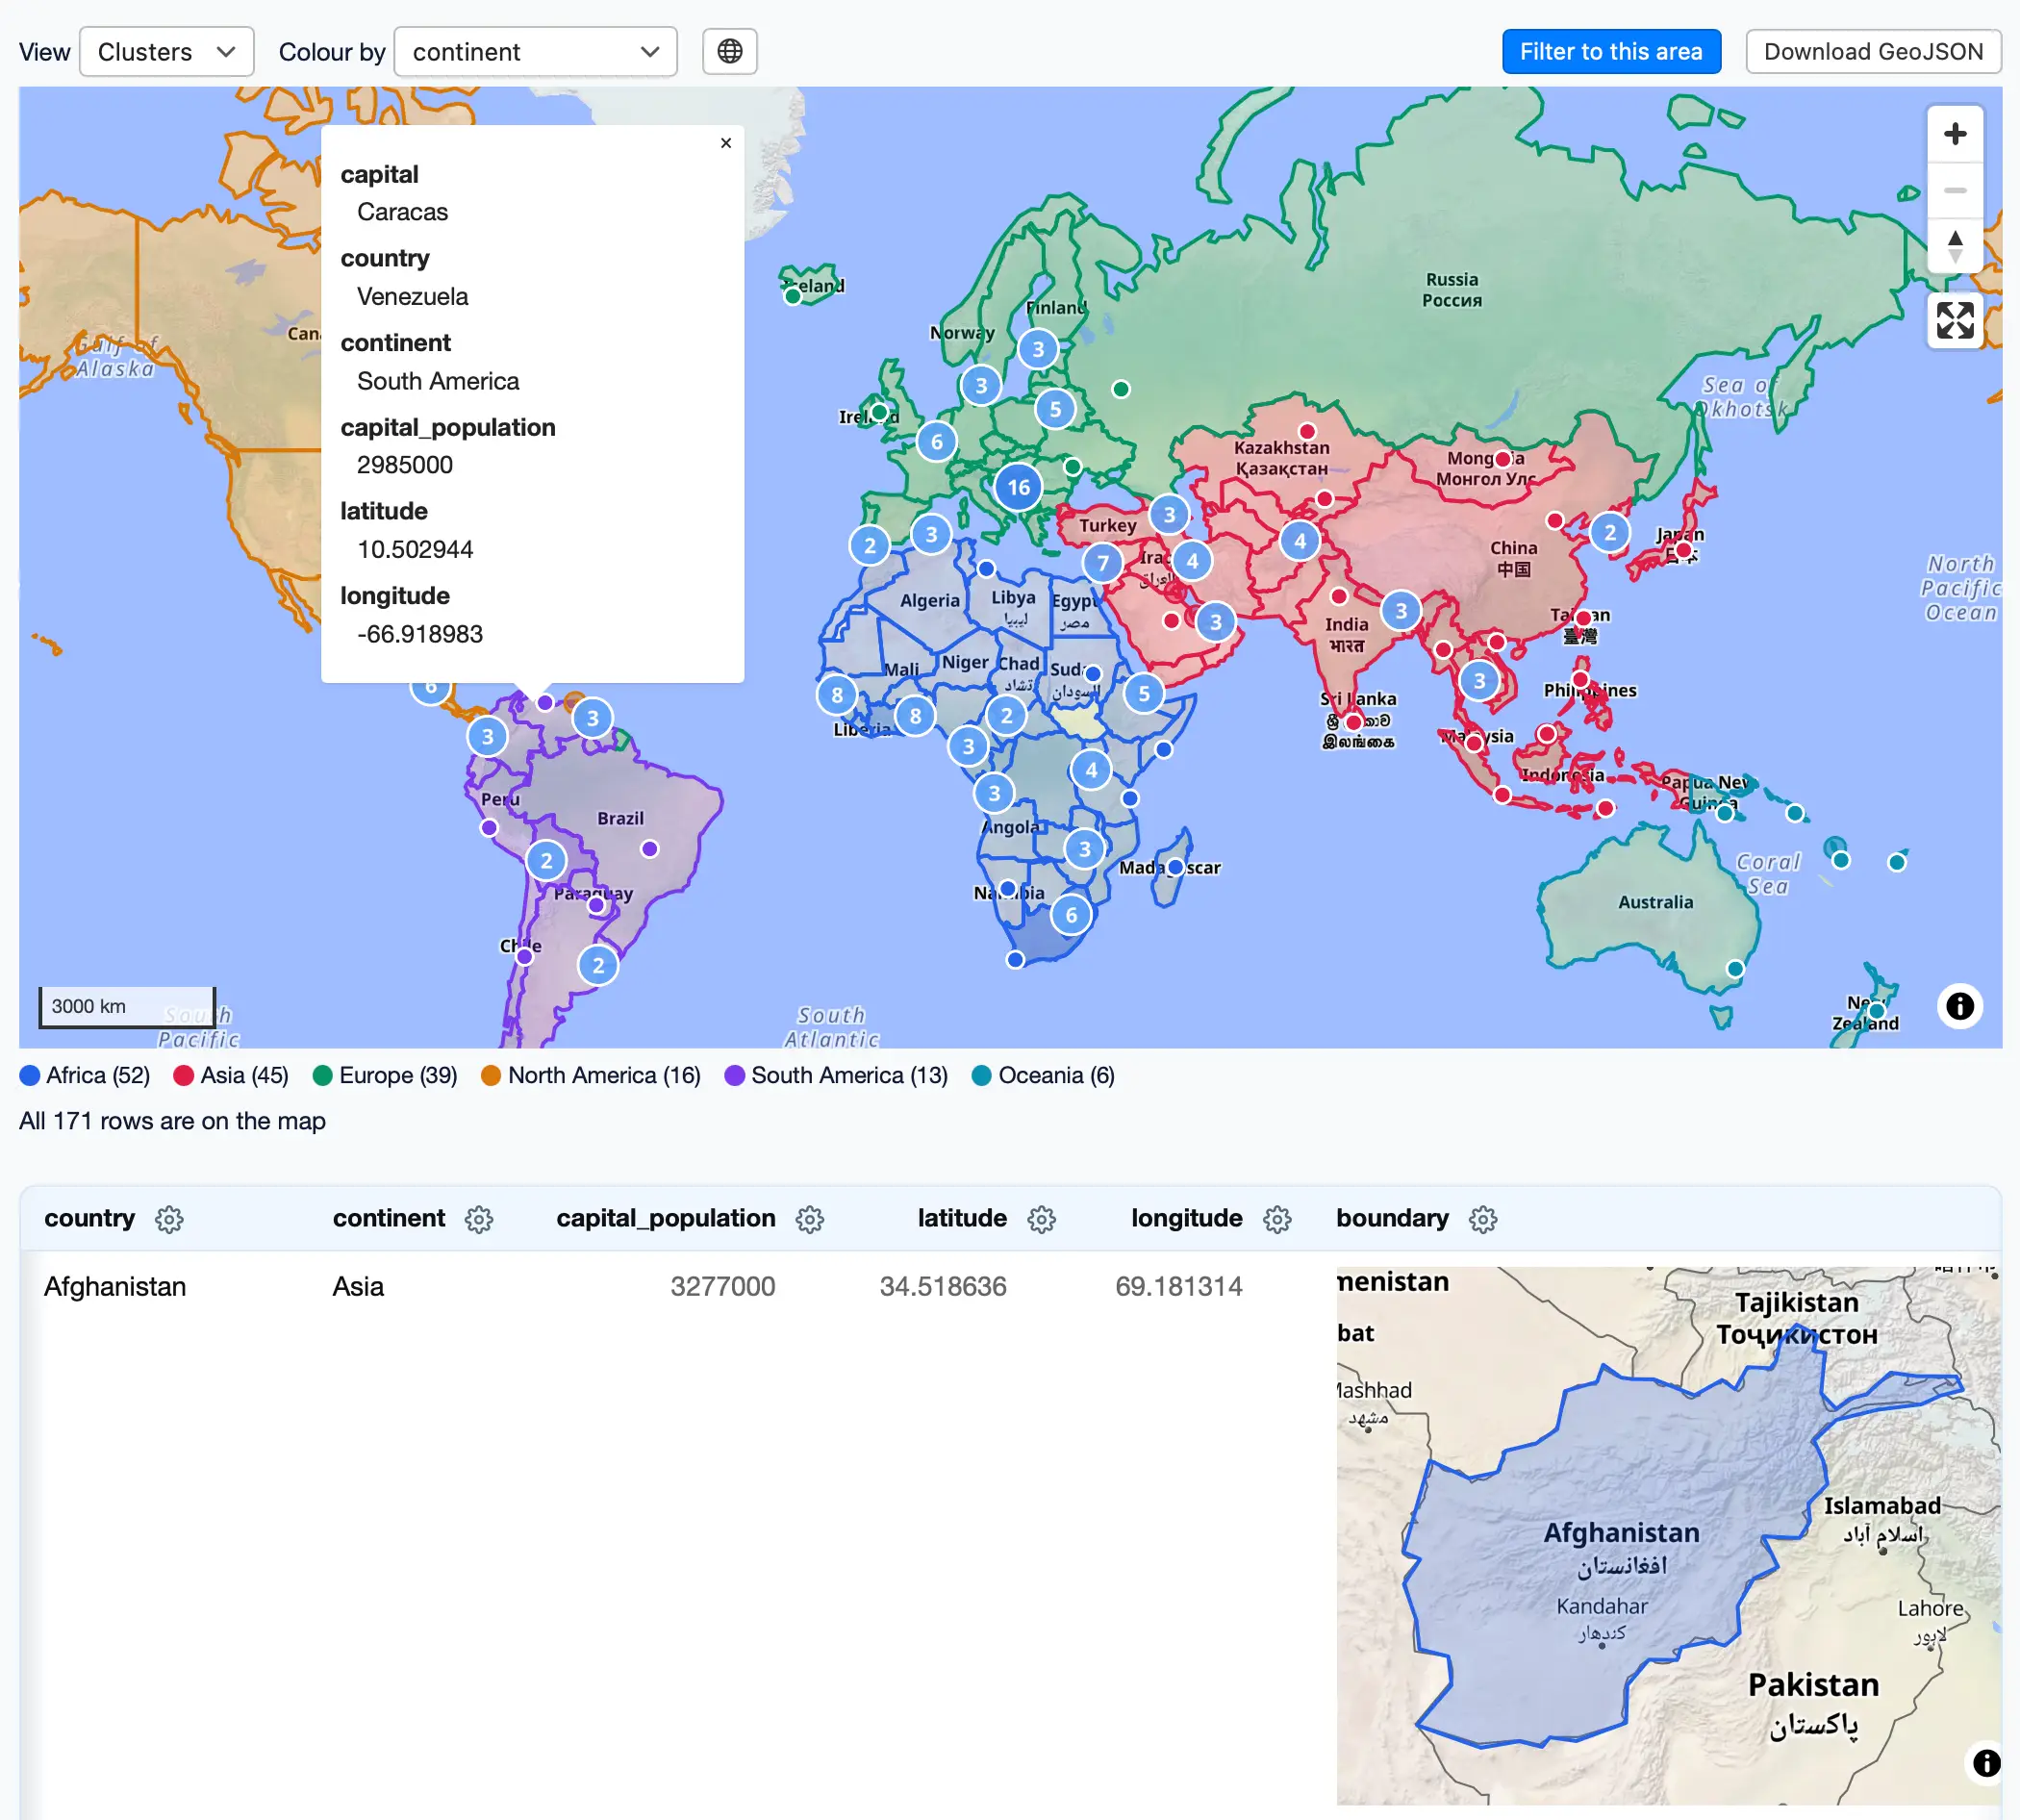
I like this demo page showing both GeoJSON shapes and lat/lon points on the same map:
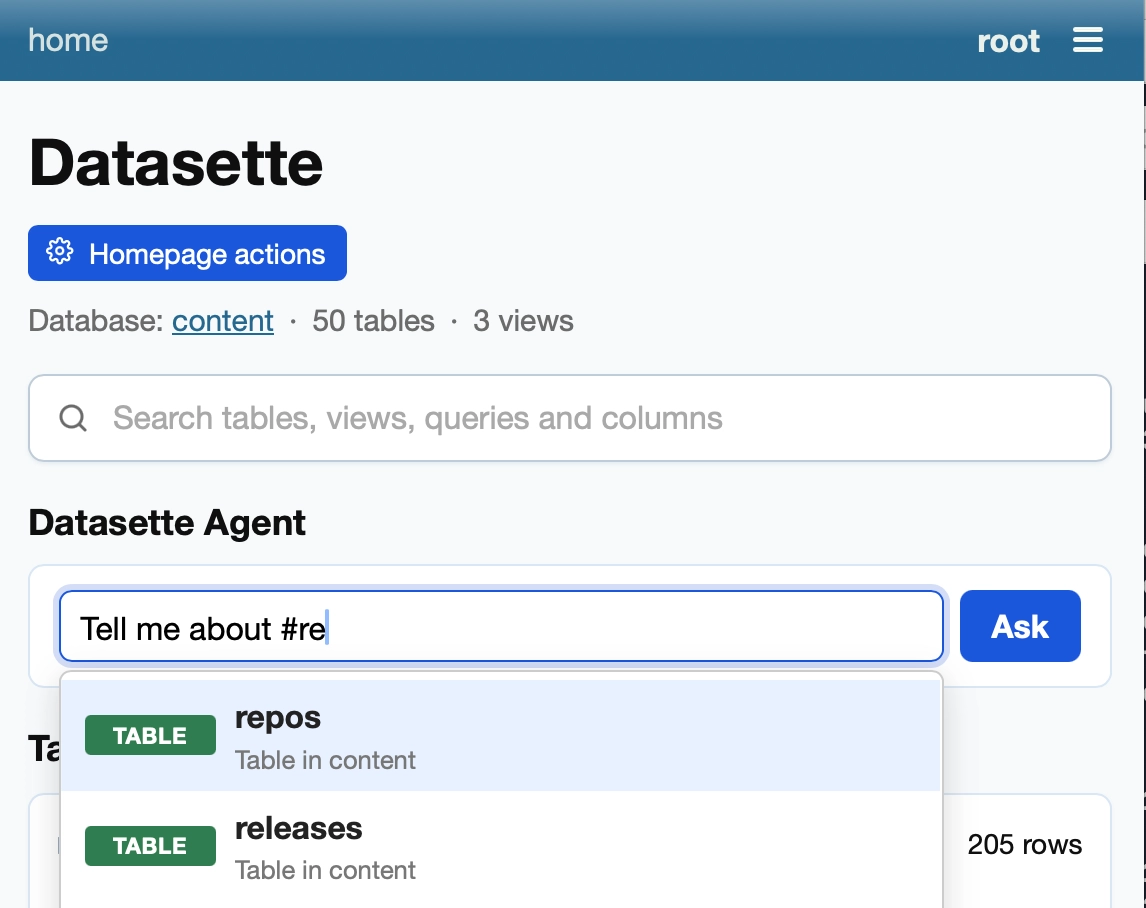
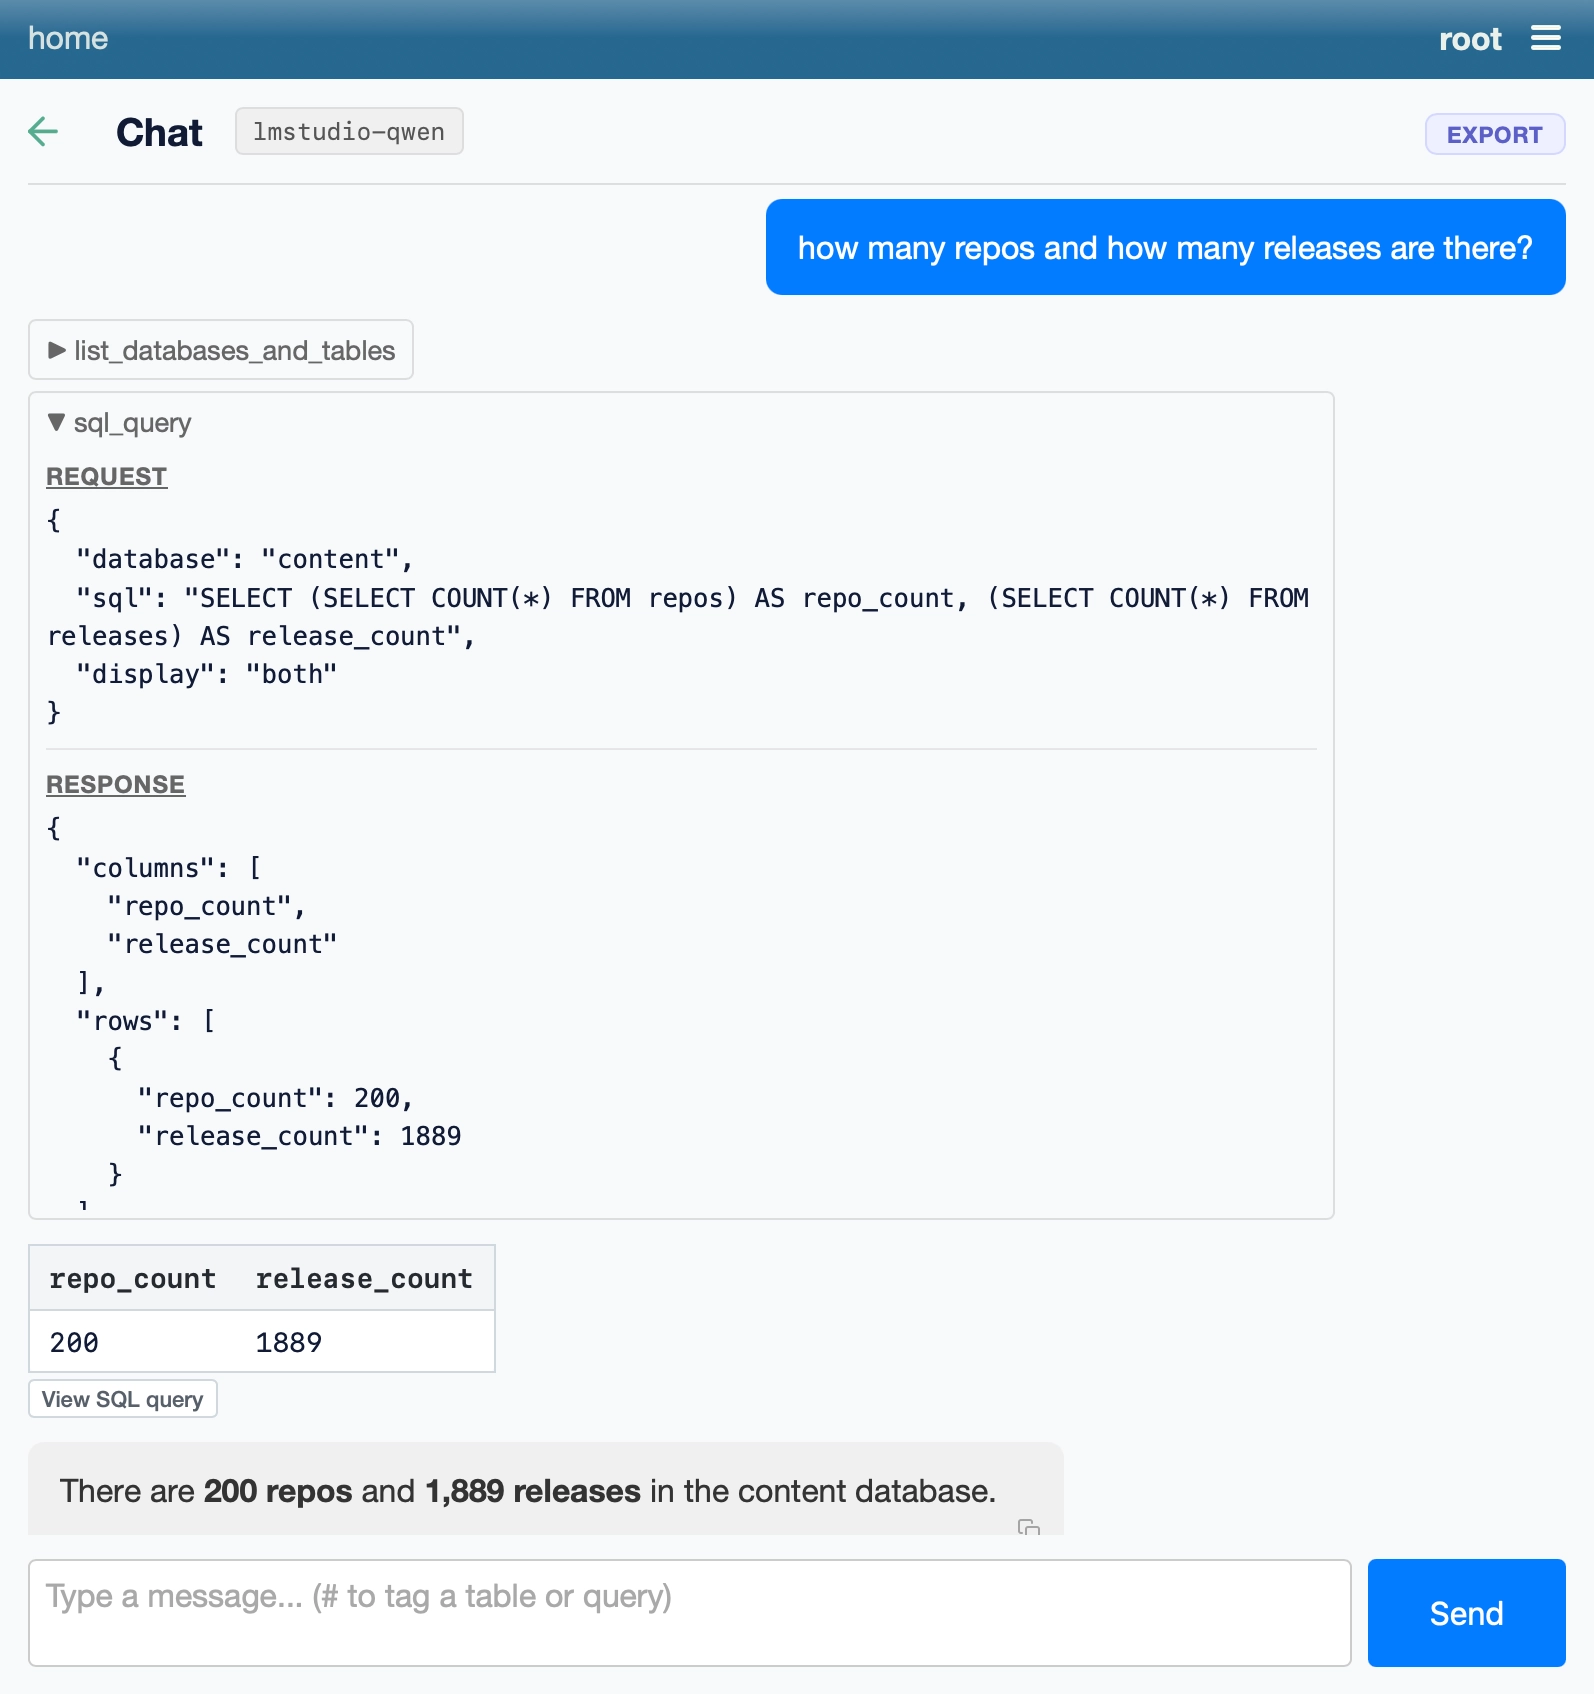
Accumulated small fixes for Datasette Agent, my agent plugin for Datasette that lets you ask questions about your data. Most notably, it now adds an agent prompt directly to the Datasette homepage, with support for hash-mentions of tables and queries:
datasette-llm is the intermediate plugin for Datasette that supports configuring LLMs for use with other Datasette plugins.
This release adds support for OpenAI-compatible endpoints, so you can configure Datasette to use an LLM hosted anywhere that talks the OpenAI pseudo-standard web protocol.
This means that if you're running local models with LM Studio or Ollama or llama.cpp (which just hit v1.0.0) you can run Datasette via uvx like this:
wget https://datasette.io/content.db

uvx --with datasette-agent datasette \
  --root --secret 1 \
  -s plugins.datasette-llm.default_model '{
    "model": "lmstudio-qwen",
    "model_name": "qwen/qwen3.8-27b",
    "api_base": "http://localhost:1234/v1"
  }' content.db
And you'll get a local server running a Datasette Agent instance powered by your local model!
Gemini Decisions API (via) Google join Jev and OpenAI in the decision model category with "Gemini Decision 1". This new model API is almost identical to Jev: it supports the same three types of questions (yes/no, choice, and rubric-scoring) and even reuses Jev's term "Noul" for a yes/no question.
It's priced the same as the GPT-6 Luna decision model: 10 cents per million input tokens, and output is free. Jev remains the cheapest of the three, at 4.2 cents per million.
Jev is text (and JSON) only. OpenAI can handle text and images. Gemini Decision 1 is fully multi-model: it covers text, images, audio, video, and PDFs.
I tested it against video by passing these questions to it along with my Yonkers stomping robot video file:
dragon: Does this video have a dragon in it?
robot: Does this video have a robot in it?
france: Is this video set in France?
usa: Is this video set in the USA?
Jev and OpenAI both return 1.0 or 0.0 for yes/no questions, but Gemini insists on being a little less confident than that:
{
  "dragon": {
    "type": "yes_no",
    "probability": 0.04976021841520312
  },
  "robot": {
    "type": "yes_no",
    "probability": 0.9234055387792485
  },
  "france": {
    "type": "yes_no",
    "probability": 0.08329171353166241
  },
  "usa": {
    "type": "yes_no",
    "probability": 0.9230459995157706
  }
}aws-emulator. Finally, an official emulator from AWS to run tests against a local clone of their many different services without having to provision a paid API key to do so.
It's written in Rust by a huge swarm of agents - 29,684 commits in the first three weeks of the project. Swaminathan (Swami) Sivasubramanian wrote about how it came to be in a guest post on Werner Vogels' blog.
It currently requires Docker to run on macOS or Windows. I'm hoping they fix that in the future - it would be great if you could download a single binary and use that as part of a standard test suite in other languages and on other platforms.
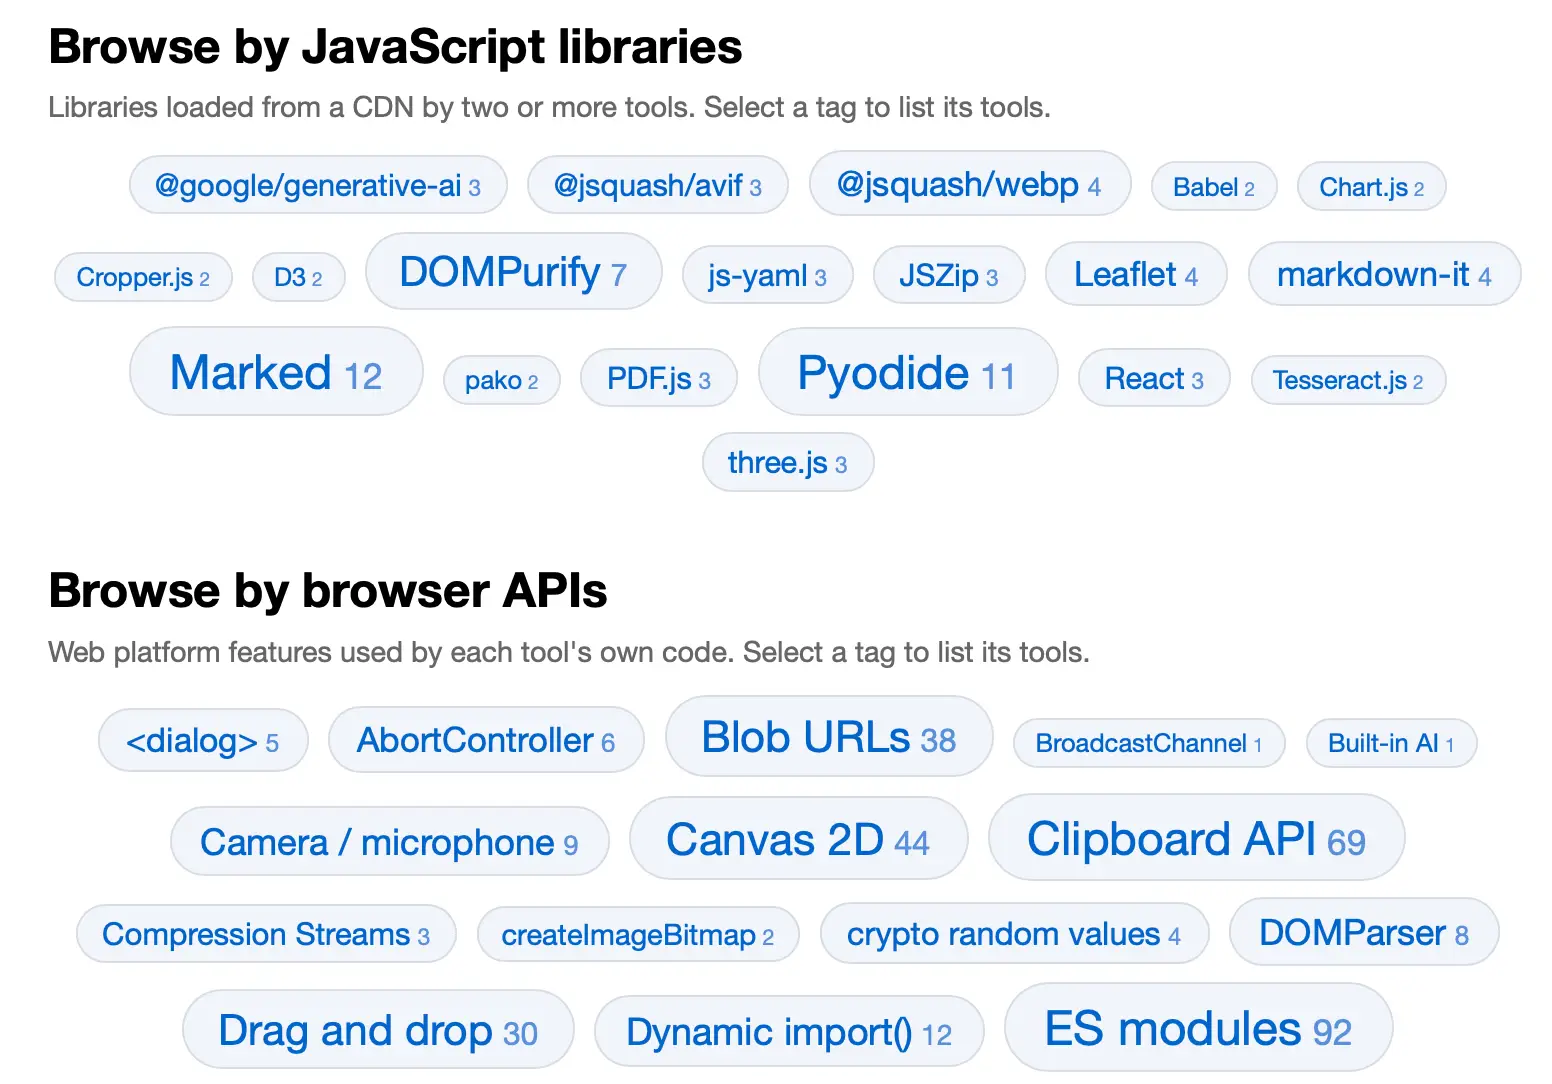
Browse tools.simonwillison.net by tag. I've been wanting a better way to browse my collection of vibe-coded tools (244 and counting) for a while. I had a few Fable 5.2 credits left over before my weekly reset so I set it to work using tree-sitter to analyze the code for JavaScript APIs, libraries, and web API hosts used by each tool.
The homepage now features tag clouds for browsing by each of those categories of tag:
Anthropic’s IPO roadshow video. Anthropic kicked off their IPO roadshow yesterday, and their roadshow video has some previously unreleased information about how their business works.
The section on "Approach to compute" with co-founder Tom Brown is particularly interesting, describing how Anthropic train and serve Claude across AWS Trainium, Google TPUs, NVIDIA GPUs, and AMD GPUs.
I'm not sure why there's no official video transcript, but here's one that I extracted using MacWhisper. Highlights below:
We train and serve Claude now across all four major chip families. That's only possible because early on we made an unconventional bet on a multi-chip strategy. At the time, many people thought that running AI models on different chips wasn't worth the effort. Each chip needs its own tailored software stack and inference stack, which is expensive and difficult to build. We've now been doing it for years, and we've gotten incredibly good at it. [...]
As an example, this year, we started working with AMD GPUs for the first time. In the past, bringing on a new chip platform took dozens of engineers months of work This time, we had Mythos try it out. It got Claude running on AMD in just three days, with basically no human intervention. Claude ported or wrote almost 100% of the kernels. [...]
The second driver of our compute advantage is our rate of discovery of compute multipliers. We focus on total effective compute, which is the multiplicative product of physical capacity times the compute multipliers that we discover. Each one we discover makes our pool of total effective compute bigger. For example, say you need 100 units of compute to train a model of a certain intelligence. A 4x compute multiplier means you can use 25 units of compute to train the exact same model. Or you can use those hundred physical units to train an even more intelligent model that would have previously required 400 units.
Compute multipliers create a competitive advantage for us that's hard to replicate. They build on each other. Each new multiplier we discover has a positive effect on the multipliers before it. They stack. We believe that this can accelerate even further as we approach recursive self-improvement. Claude will be able to discover compute multipliers entirely by itself, allowing the number of compute multipliers to grow faster and faster.
We got a hint at Anthropic's multi-chip strategy last September in their postmortem of three recent issues, where they described bugs that affected just their TPU deployments.
Gemini 4 Carbon was announced two weeks ago for "a subset of cyber defenders", but today it's available to everyone else.
This is Google's best ever Gemini, priced at $2/million input and $10/million output at launch (that's GPT-6.1 Sol / Claude Sonnet 5.5 prices) but scheduled to double in price to $4/$20 on December 1st (same as Opus 5.5).
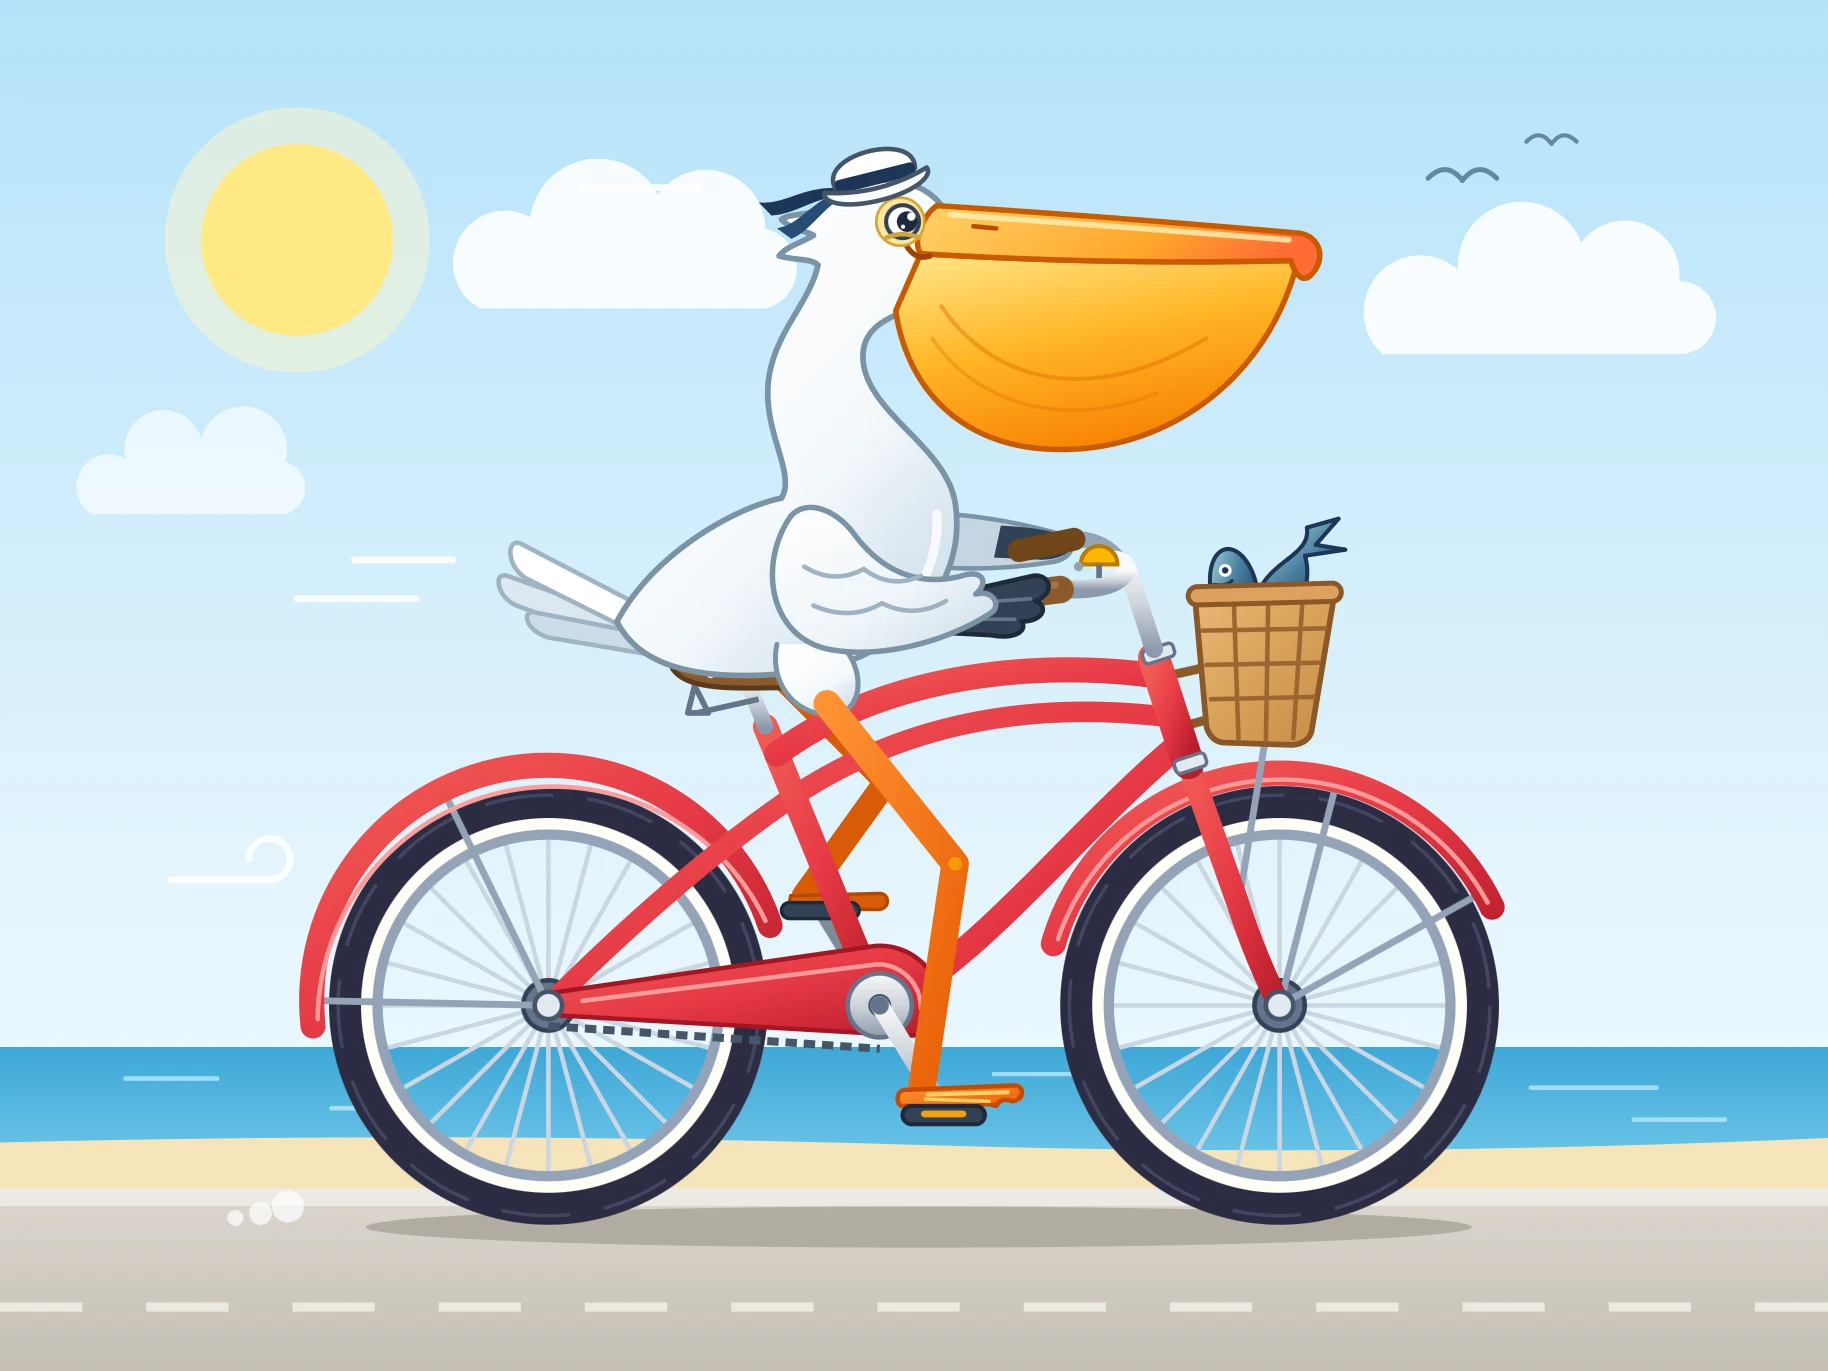
Here are three pelicans for the low, medium and high thinking efforts (it defaults to medium). This is the pelican I got for high:
Gemini pelicans have all been great for a while now, so I also tested it out using Google's Antigravity IDE with a prompt I first tried with Claude Fable 5.2 yesterday:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data
Here's the HTML result (I had to prompt "build that into a standalone HTML file" to get a version with no external dependencies). I then screen-captured that as a video:
Update: Huh, just saw this on YouTube (and tweeted by Google CEO Sundar Pichai):
Using Google Antigravity’s /swarm feature, Carbon built an open-world 3D game where you explore Google’s Mountain View campus as a pelican riding a GBike — coordinating subagents to model 3D assets in Blender from Omni and Nano Banana references, build the browser game in Three.js with WebGL shaders, and pair procedural Web Audio sound effects with Lyria music.
Here's the playable version in AI Studio.
Introducing Our Smallest, Most Efficient Model: Muse Ember. Meta AI just launched their entry in the Claude Haiku/GPT Luna category: Muse Ember, which they describe as:
[...] our smallest and most efficient model designed for complex reasoning execution and the work agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing.
For shorter prompts it's priced the same as GPT-6 Luna and Claude Haiku 5.5 - both are $0.10/million input tokens and $0.50/million output. Today's other big model release, Claude Fable 5.2, is 80x that price at $8/$40.
The pricing is a little less straightforward as prompts get longer, though. Luna, Ember, and Haiku all support up to a million input tokens, but they also all have a threshold after which the price goes up. Taking that threshold into account Ember is priced between the two others:
| Model | Prompt size | Input ($/M) | Cached input | Output |
|---|---|---|---|---|
| GPT-6 Luna | ≤272k | $0.10 | $0.01 | $0.50 |
| >272k | $0.20 | $0.02 | $0.75 | |
| Muse Ember 1.0 | ≤200k | $0.10 | $0.004 | $0.50 |
| >200k | $0.30 | $0.012 | $1.50 | |
| Claude Haiku 5.5 | ≤100k | $0.10 | $0.01 | $0.50 |
| >100k | $0.50 | $0.05 | $2.50 |
But comparing price-per-token doesn't really make sense these days, when reasoning tokens mean that different models might use dramatically different numbers of tokens to solve the same problem.
For that, one measure that's useful is the Artificial Analysis.
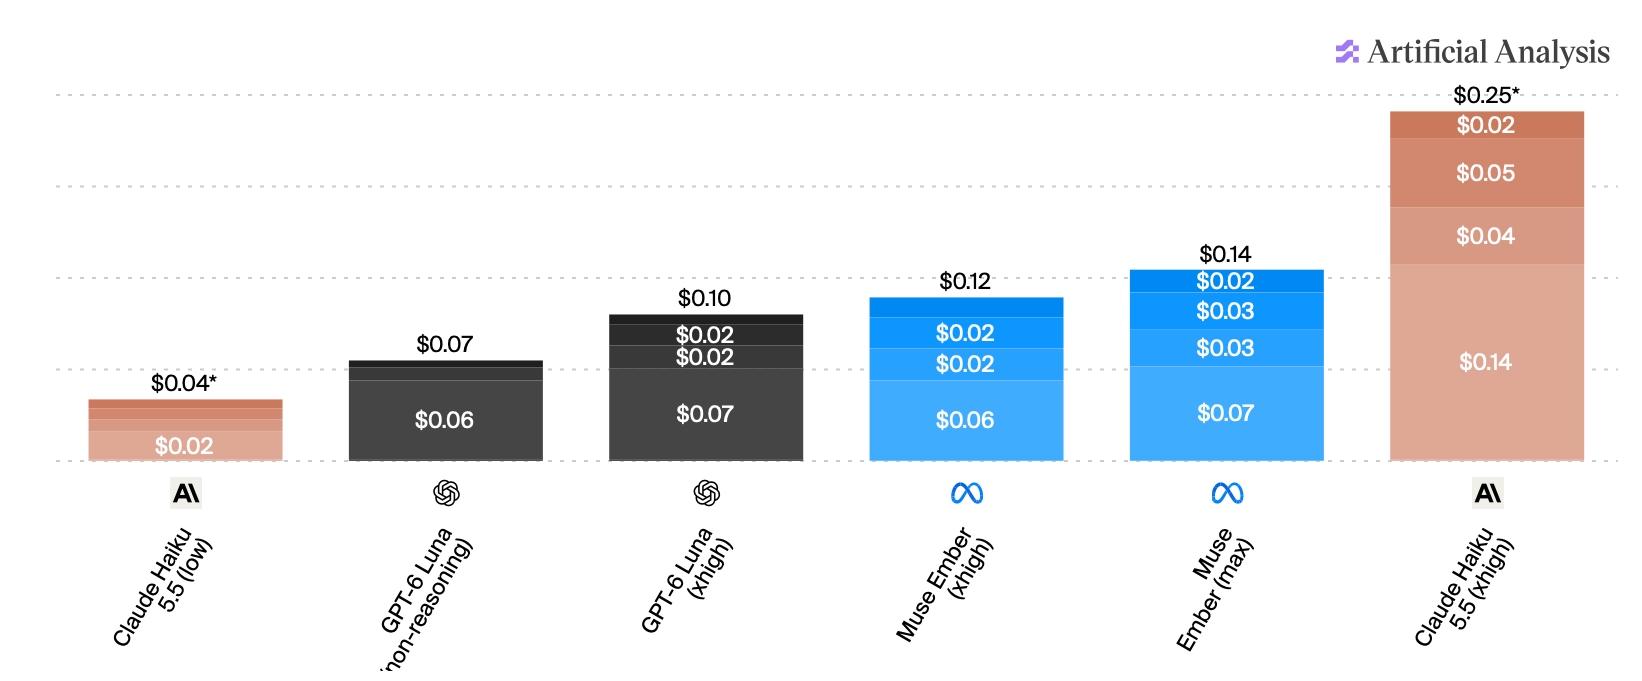
And even more useful than that is their Intelligence Index vs. Cost per Task chart, which shows the following for those three models:
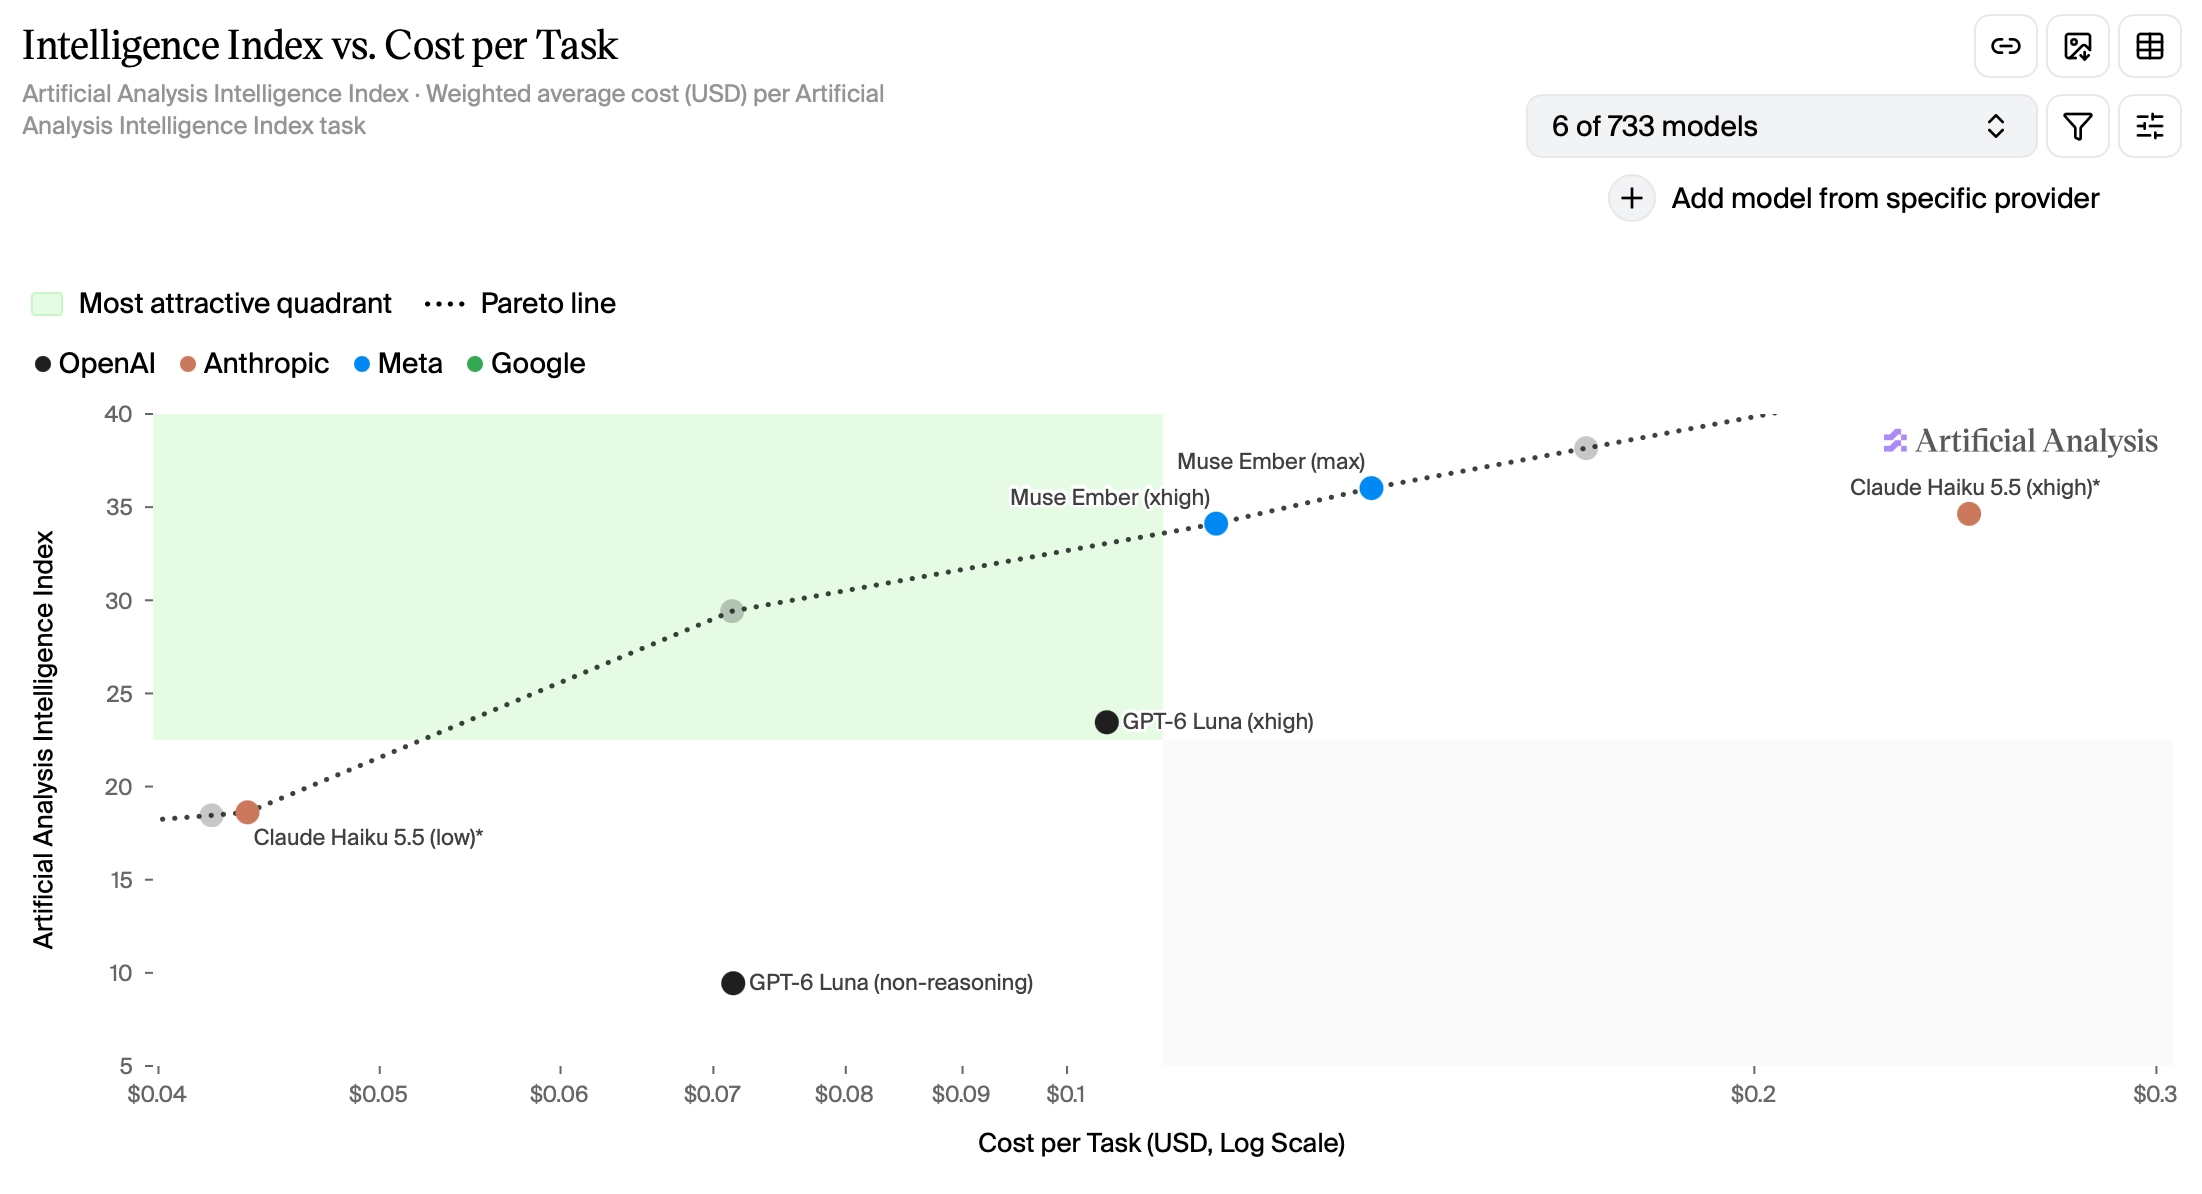
The Muse Ember models sit right on that Pareto line - the line at which you can only improve one dimension by giving up another. Meta call this out in their announcement:
It also sits on the efficiency frontier of the full Artificial Analysis leaderboard: no model scores higher for less per task.
(That grey dot on the Pareto line in the middle of the green area is GPT-6.1 Terra (low) - clearly I should be paying more attention to the Terra family!)
Muse Ember has six reasoning levels - minimal, low, medium, high, xhigh, and max - so I rendered six pelicans riding bicycles. The "high" reasoning level failed to return a full SVG, and the other SVGs were surprising in that the reasoning level didn't cleanly map to the visual quality of the response.
Here's the "max" one, but the others are worth a look too:
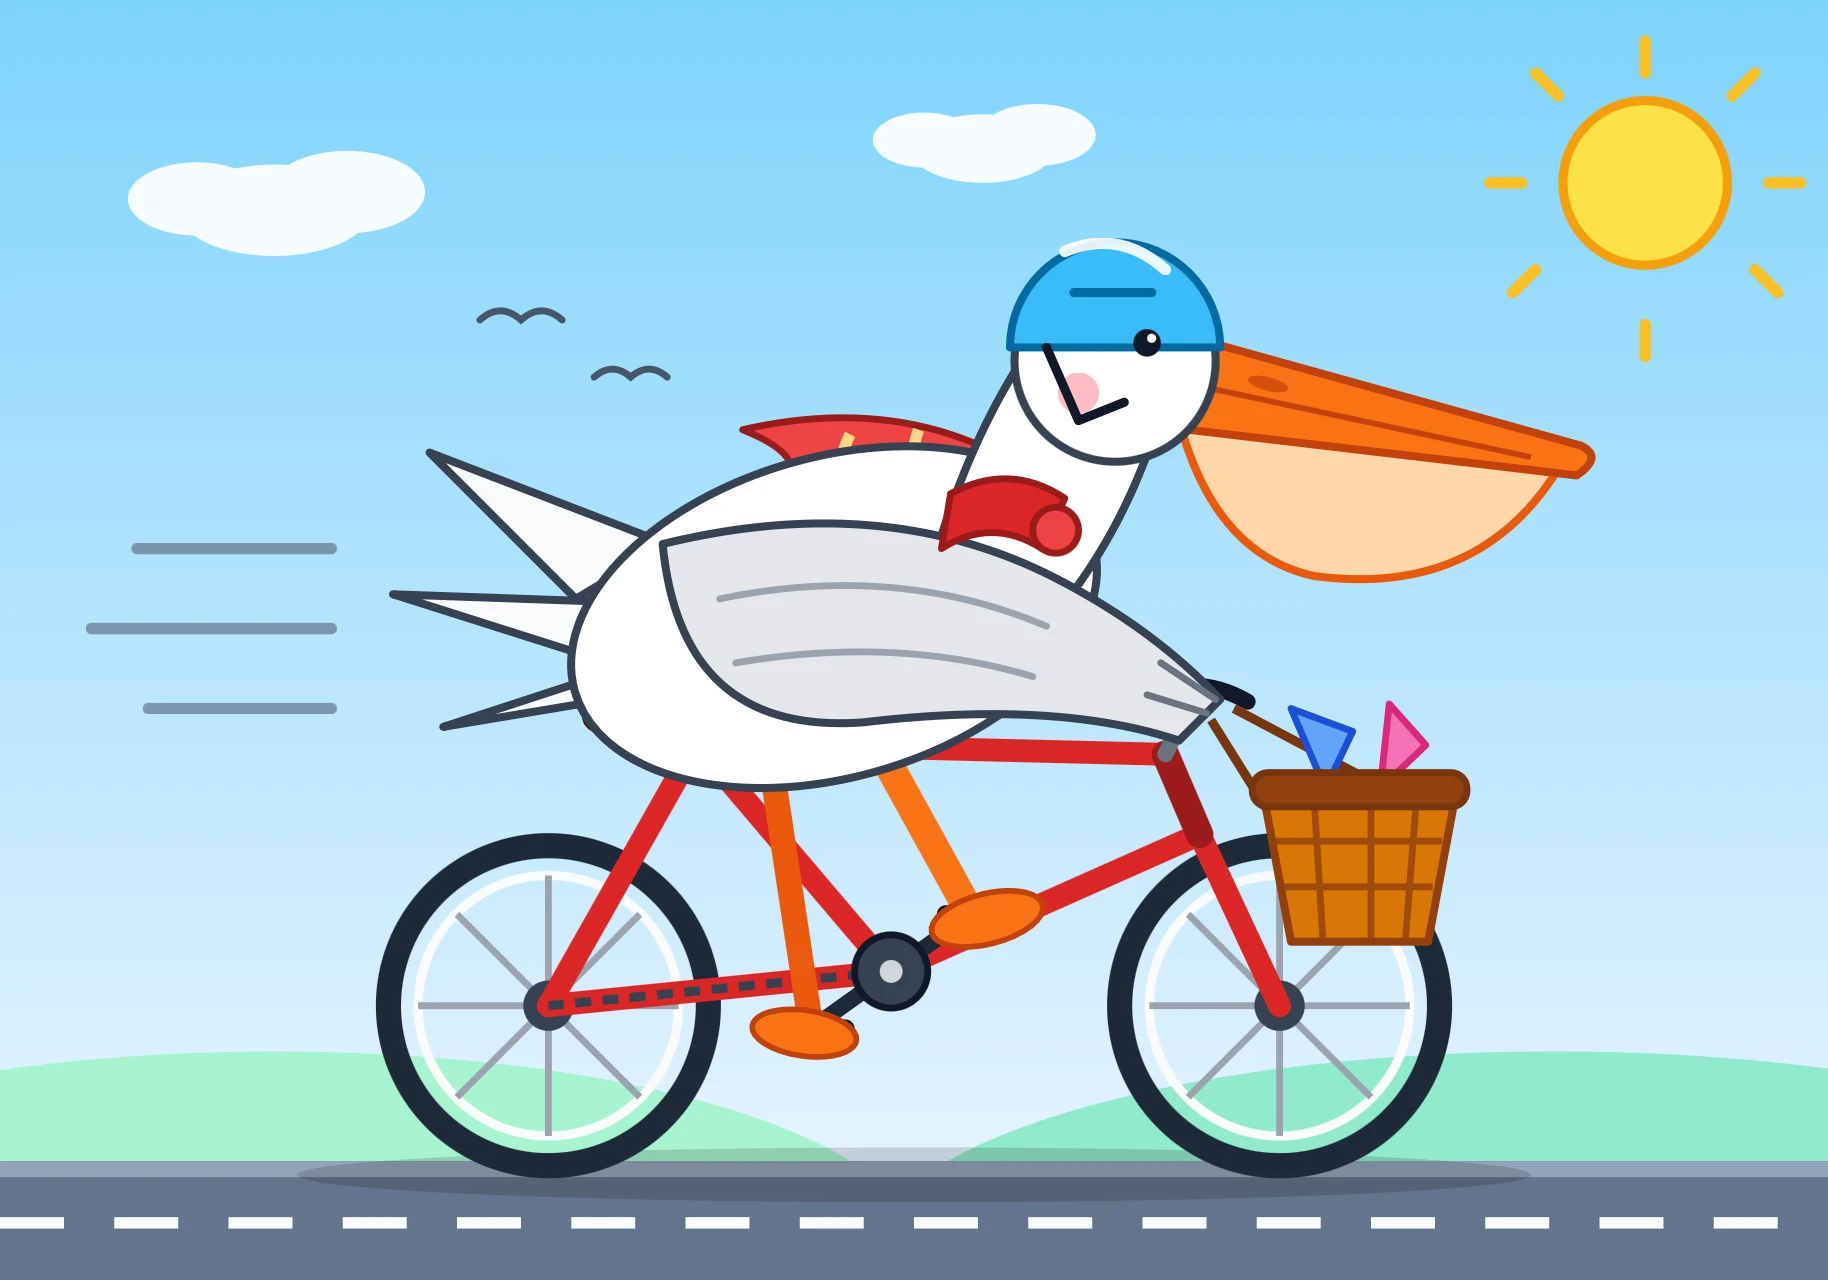
The Ember pelicans are comparable in quality to those I got from Muse Wonder, which is 40x the price of Muse Ember.
Claude Fable 5.2 pays close attention to who owns the code it works on. In Anthropic’s testing on small coding tasks, the model tended to add to the existing structure when the prompt said nothing about ownership or presented the code base as someone else’s, even when that duplicated existing code. When the prompt said the code base was the model’s own, it often consolidated duplicated code and sometimes made related fixes without being asked.
If you want the model to improve the structure as it works, say that the code is its own:
You are the owner and long-term maintainer of this codebase, and its design is up to you.The ownership sentence makes the model much more likely to consolidate duplicated code into one shared function. In Anthropic’s testing on small coding tasks, the model consolidated duplicated code in under 10 percent of runs without the sentence and in about 75 percent of runs with it.
— Prompting Claude Fable 5.2, Anthropic documentation
I realized I didn't know where Yonkers was, so I looked it up on Google Maps and then, to help embed its location and shape in my head (and to try out Claude Fable 5.2's 3D modeling and animation skills), I prompted Fable 5.2 Medium to:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and átomos around manhattan and queens and Brooklyn, use openstreetmap mapping data
It correctly deduced that "átomos" was a mobile keyboard typo for "stomps":
Anthropic released Fable 5.2 and Mythos 5.2 today. Fable 5.2 is currently ranked first on Artificial Analysis. Anthropic say it "solved two open problems in the physics of black holes", so clearly their internal benchmarks have become more ambitious!
I've added the new models to llm-anthropic, so you can now run prompts through Fable 5.2 like this:
uv tool install llm
llm install llm-anthropic
llm keys set anthropic
# paste key here
llm -m claude-fable-5.2 "Generate an SVG of a pelican riding a bicycle"
I ran pelicans at all five reasoning levels - low, medium, high, xhigh, and max. You can see them all here - here's the best result I got, from xhigh:
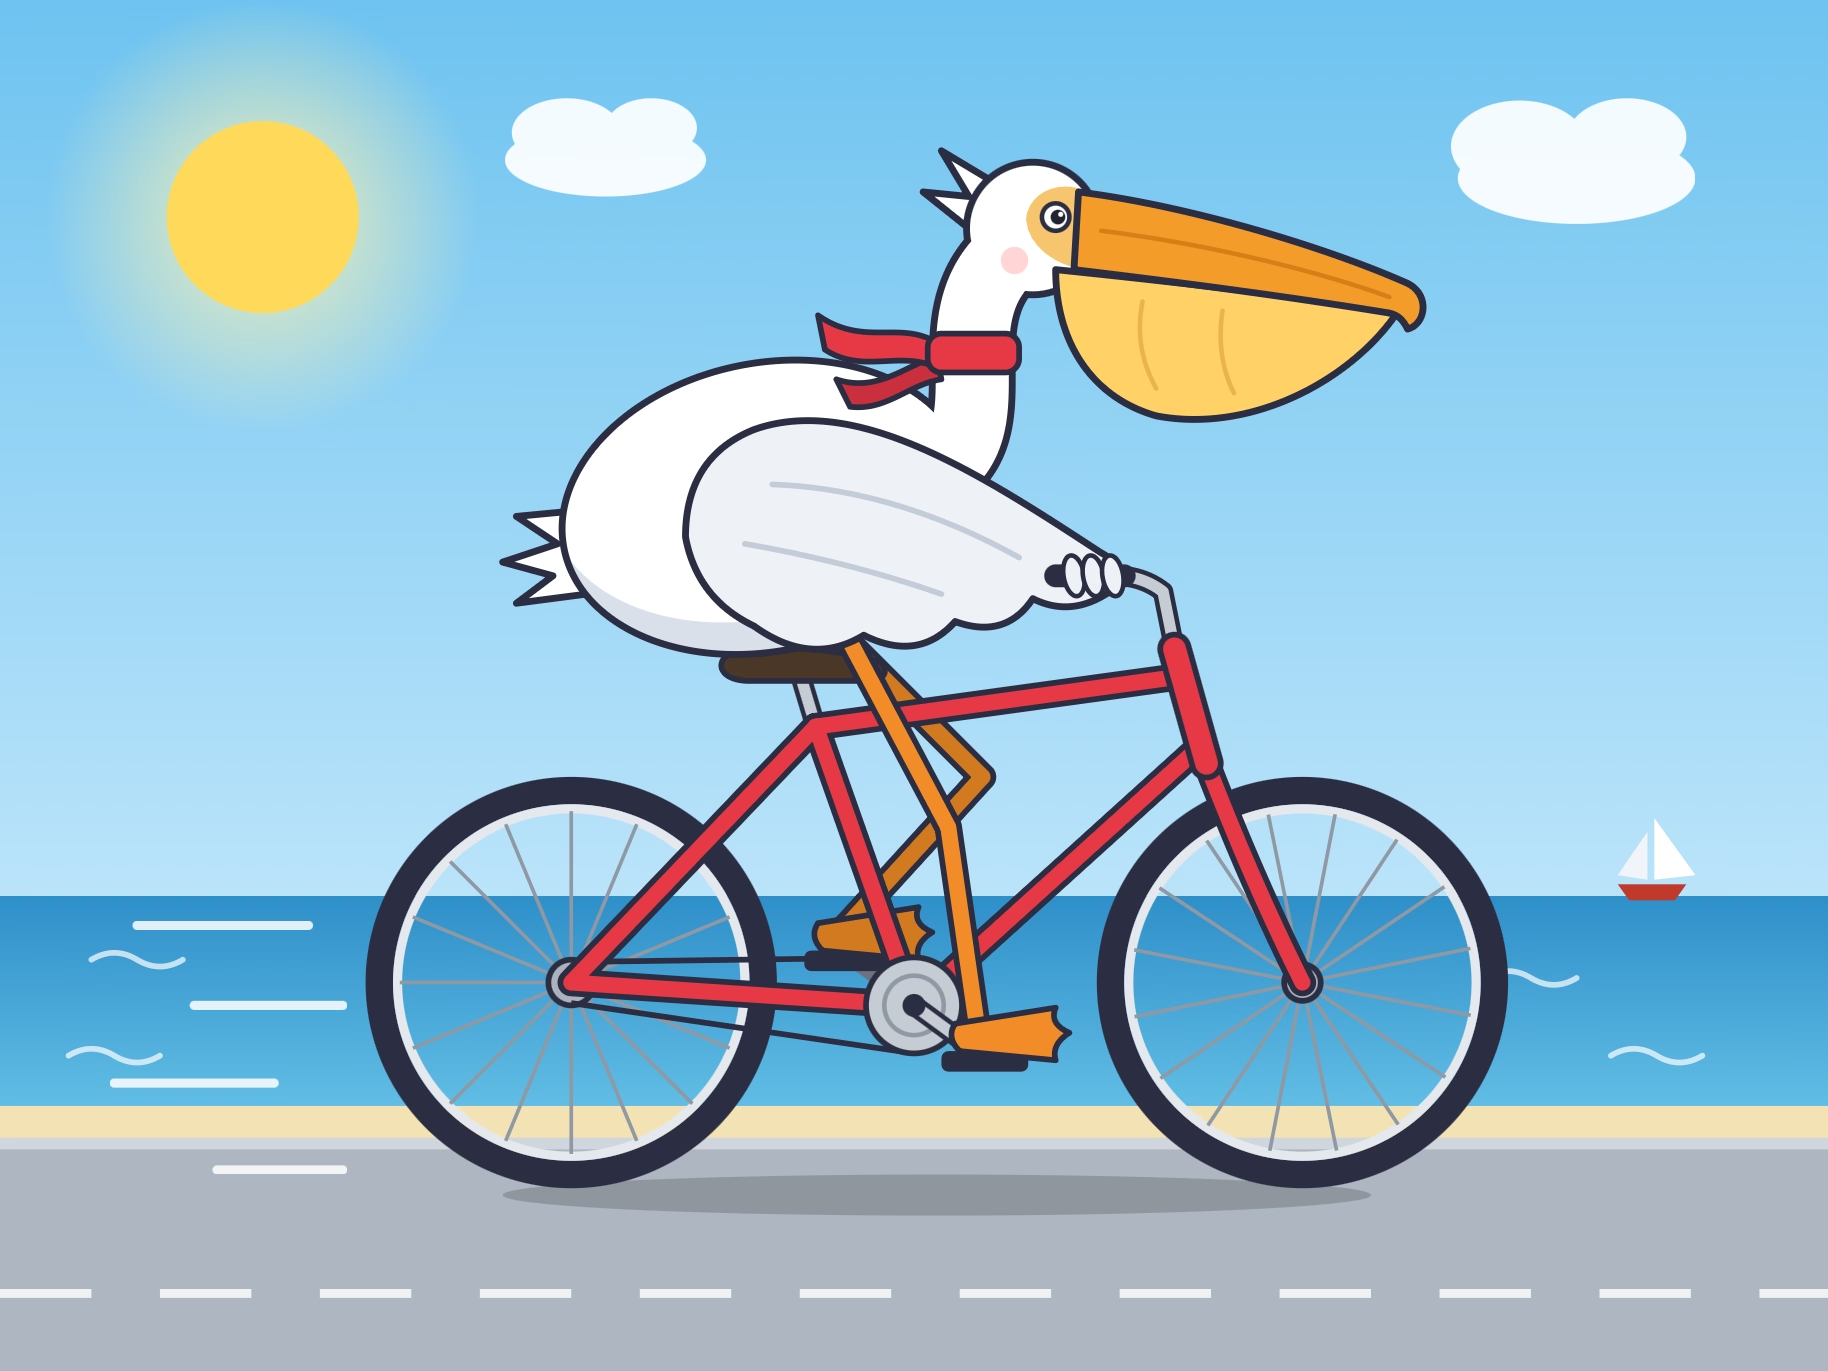
max failed to return an image at all, running out of tokens after spending 128,000 thinking about them. That's the same bug that I saw with Opus 5.5 - but it's new for the Fable series, both Fable 5 and Fable 5.1 returned max effort pelicans just fine.
It's priced at $8/million input and $40/million output, which is a 20% discount on the previous Fable 5.1 ($10/$50).
I also used Fable 5.2 to help identify the source of a mysterious beep.
Locating the source of a mysterious beep with Claude
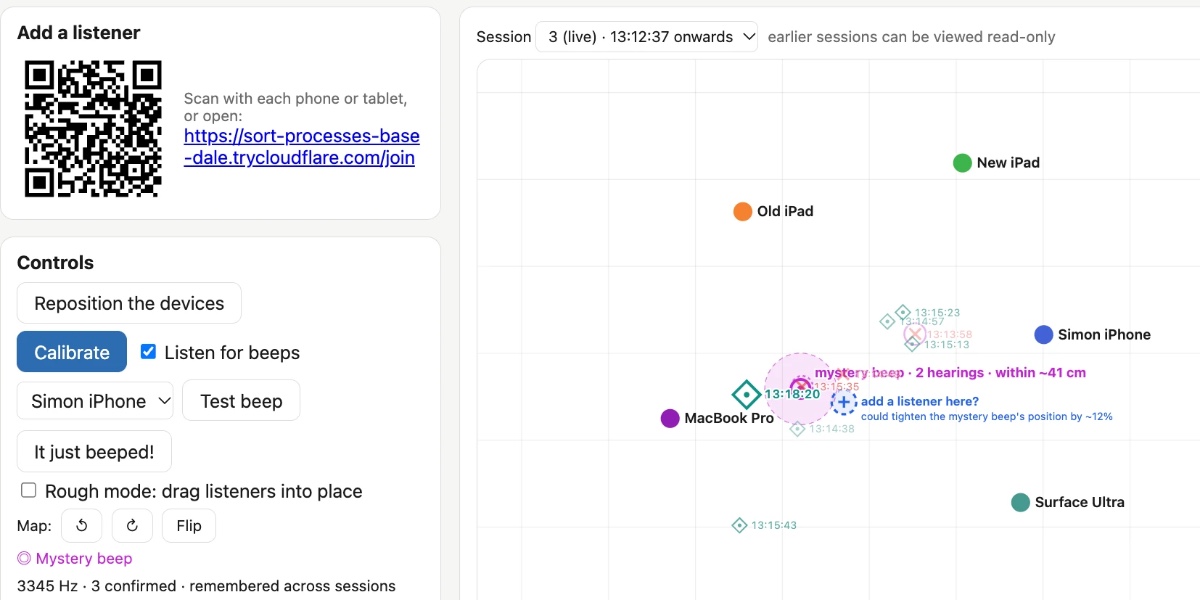
Our house has a box room, full of boxes that we still haven’t unpacked from our last move. A couple of weeks ago something in that room started intermittently beeping. The beeps were far enough apart that standing in the room and trying to determine the source of the noise was frustrating, and I really didn’t want to dig through every one of those boxes. So I had Claude Code build Beep Locator, a software system for triangulating the source of a mysterious beep using multiple devices scattered around the room.
[... 2,039 words]Hide your slop PR descriptions behind <details><summary>
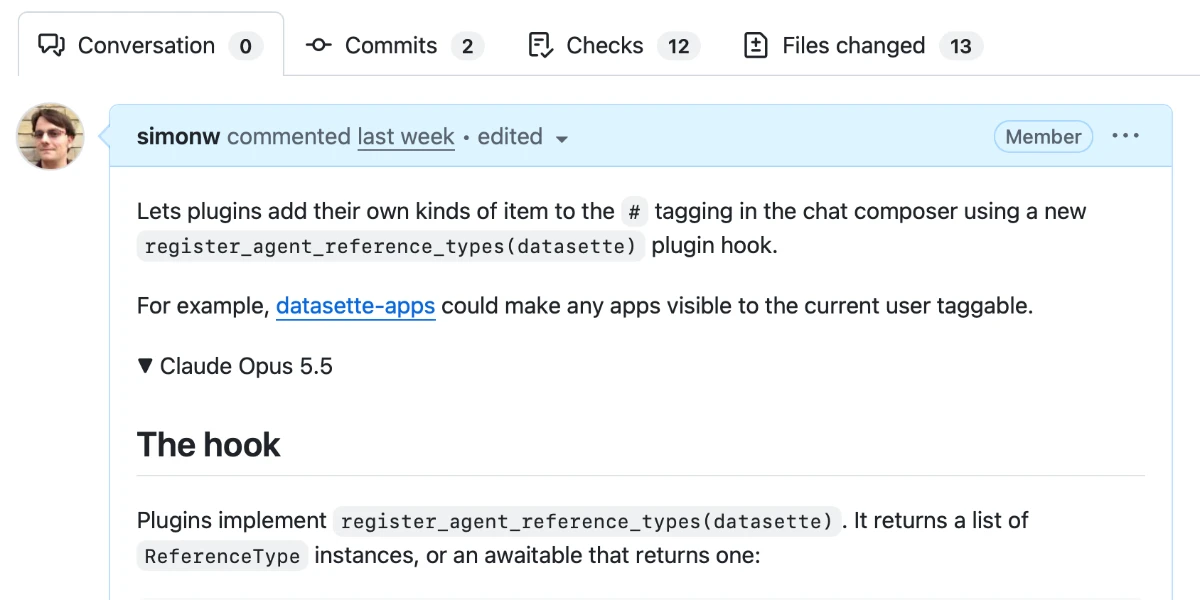
Most of the changes I make to my projects these days come in the form of PRs opened for me by Claude Code or Codex. The PR is my unit of work—I use them to bundle commits together, iterating on them until a feature is complete, document decisions and then merge the finished result. Today’s coding agents are great at writing PR descriptions.
[... 987 words]The products aren't good enough to sell people on the costs.
You cannot tell people that you have to listen to the whine of a data center in their backyard for AI overviews and some of the most hilarious deep fake slop in history.
It's not worth it. It just isn't worth it to anyone. And agents aren't real and they might not be being used the way that anyone wants them to yet. All these companies are spending more than they're making on these products. Refrigerators holding blood storage in Europe are being hacked.
The costs are too high. The benefits are not real. And if you connect that to corruption, you're like, in order to impose these costs on me, these CEOs are in the White House shaking Trump's hand, renaming it to the Gulf of America, paying for this ballroom that we don't want. It's obvious crypto-corruption, and it's still slop.
The AI industry will not get out of it until they make better products. Until everyone can see without needing to be convinced, without needing an ad campaign, without any of this stuff that just using these products makes your life better.
— Nilay Patel, The Vergecast: Big Tech lost big in the 2026 election
Qwen 3.8 27B on my laptop can interpret model weights, too
Yesterday’s hot paper was Sparks of Weight-Space Programming: LLMs can natively read & write neural network weights by Rikiya Takehi, Jayden Teoh, Alex Zhang, and Omar Khattab. The paper (OK, the authors classify is as a “blog post”, but it’s paper-shaped) found that frontier models, in particular GPT-6 Astra, can both interpret and modify the raw weights of a machine learning model—literally a text description of the model containing a bunch of floating point numbers. I’ve been playing with one of the examples from the paper and I’m delighted to share that Qwen 3.8 27B running on my laptop can do this as well!
[... 1,211 words]There's a lot of stuff in this new release of my LLM CLI tool and Python library, representing around two months of accumulated features and fixes.
I added gpt-6.1-sol and gpt-6.1-terra, plus a new llm openai endpoint add command to make it easier to configure additional models that use OpenAI-compatible endpoints.
I switched the default model (if you have not set your own default) to gpt-6-luna - half the price of the previous default, gpt-5.6-luna.
LLM's support for embeddings now accepts that different binary content may have different content-type - necessary for models like Gemini Embedding 2, which can embed text, audio, images, and video.
A lot of open source maintainers complain about a flood of AI-assisted PRs. LLM is my project that has been most affected by this and, to be honest, I'm not finding it to be a problem. That's mainly because I have Opus 5.5 or GPT-6 Astra help me with triage to spot the most useful fixes!
This release includes fixes from 12 authors - almost all AI-assisted - and the burden of reviewing them wasn't nearly as great as I expected. I really see them as bug reports with attached examples - sometimes I land them, sometimes I implement my own fix.
So thanks to 0d00ciallo0721, ac1982, Allen Flux, Bian Yuhan, Bishop Kammeraad, Chen Yufeiyang, Christopher Krah, Ethan Stoner, Jiachen Xie, Olamide Faniyan, Sharat Chandra Sai Boddu, nosmile99 for helping out with (or spending tokens on) this release!
The U.S. Census Bureau and “Super Intelligence”
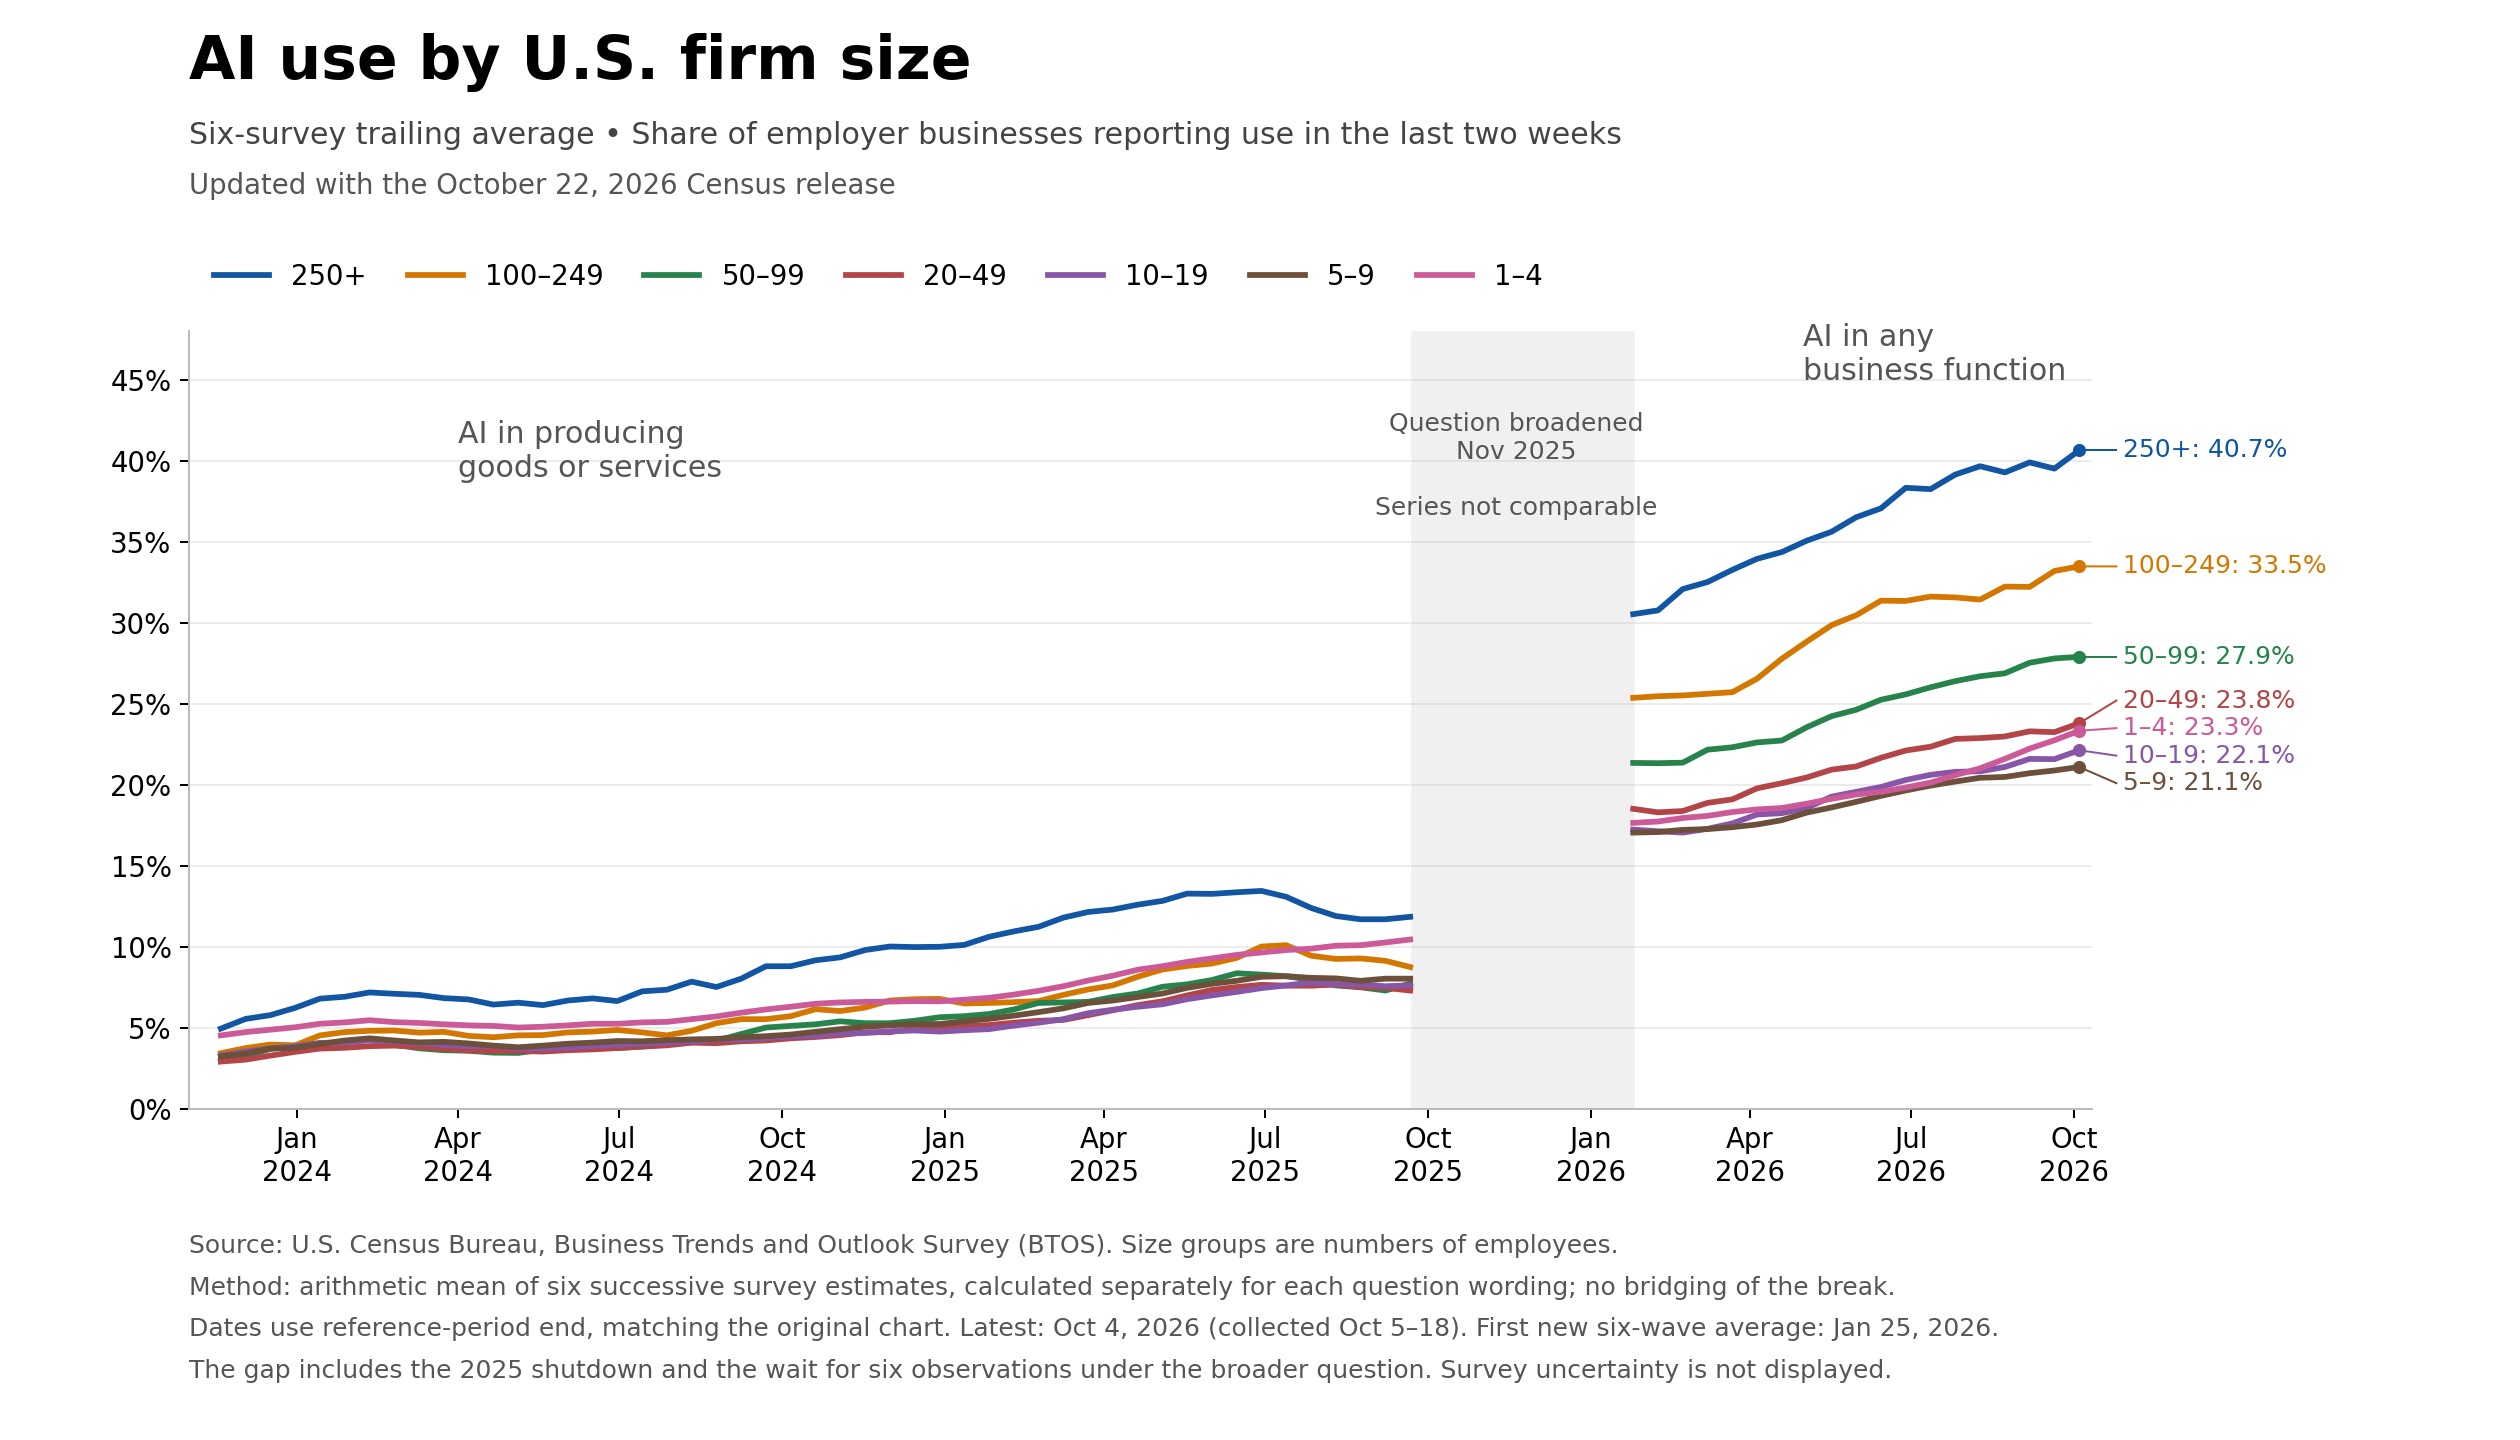
I was reminded today of AI Adoption Rate Trending Down for Large Companies, a chart produced by Apollo Global Management in September 2025, which appeared to show a slowdown in U.S. corporate AI adoption based on numbers collected by the U.S. Census Bureau. At the time I used that chart to demonstrate GPT-5 data analysis, and then to experiment with Claude’s new Code Interpreter. I decided to try running those numbers again to see what had changed over the past year, and in doing so learned that the Bureau has fallen foul of Executive Order 14434, aka the asinine Super Intelligence one.
[... 1,068 words]More broadly, the use of LLMs erodes trust in documentation, in software, and in the organizations which produce them. Perhaps engineers will begin to treat any new software project with suspicion—the signals we used to rely on as markers of a mature system are now easier to counterfeit. [...]
In the age of LLMs, what can maintainers do to ensure correct software and accurate documentation? Having done that work, how can they demonstrate its quality to users?
— Kyle Kingsbury, Jepsen results for ParticleDB 1.1.4
dbreunig/nesformer (via) Inspired by qwenputer by Divyansh Agrawal, Drew Breunig baked a working emulator for a Nintendo Entertainment System 6502 CPU into the weights of Qwen3.5-4B. You can now play NES ROMs such as Super Mario Bros (very slowly) running inside Qwen!
In a comment on Hacker News Drew reveals the Opus 5.5 prompts he used to build this system:
Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed.
Followed by:
I think we should build it! Just for fun. It's okay if it's not fast. We want to be able to have the weights, and a cli to run them that we can point at a ROM.
Apparently Opus found and then used this collection of conformance tests for the NES CPU released 15 years ago by Christopher Pow.
API credits benefit for eligible ChatGPT subscriptions. Earlier this month Anthropic announced a generous new benefit for their Max and Team subscriptions: $100, $200, and $500 per month subscribers would get the equivalent quantity of (expiring) credits to use with the Anthropic API.
OpenAI have now launched pretty much exactly the same deal: if you have a $100, $200, or $500 subscription plan with them you now get that same quantity of credits to apply to one of your API organizations.
I maintain subscriptions with both companies, so this is great news for me! I may even ship some public-facing demos now that the credits are already covered by my existing subscriptions.
How I Built the Most AI-Pilled Company in the World. Don't be put off by the clickbait headline, this piece by Jacob Sansbury describing how they are building Spawn is a fascinating exploration of the bleeding edge of what's possible with agentic engineering against frontier models.
Spawn is a massively multiplayer gaming environment where players can use prompts (to the in-game agent, Savi) to modify the game world.
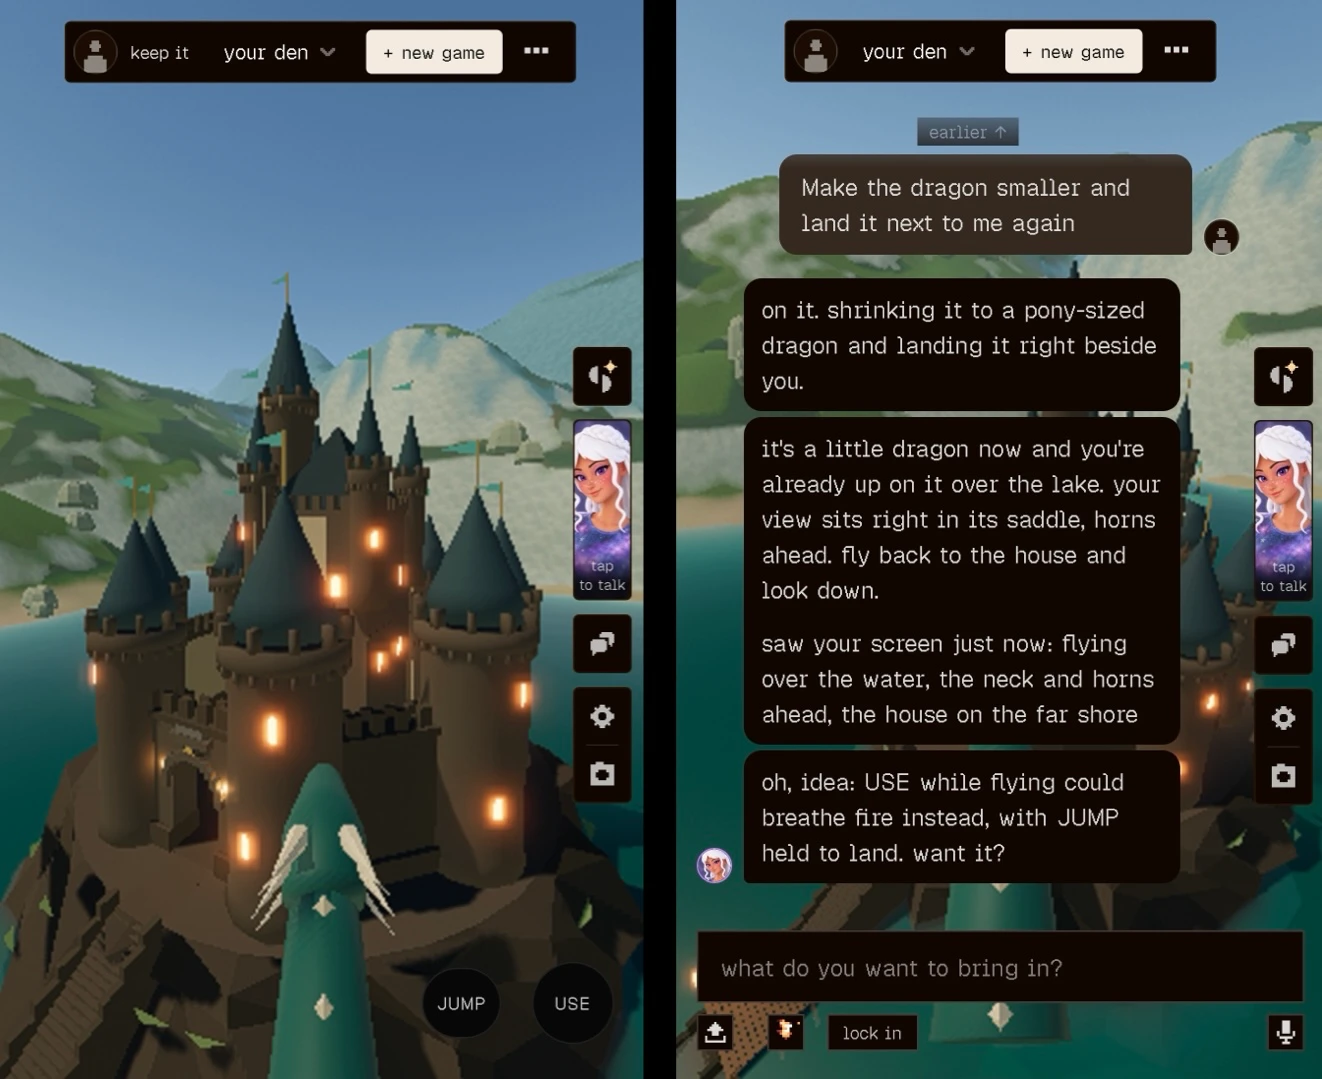
I fired it up on my phone for a few minutes and was able to prompt a castle into existence, then a dragon, then ride the dragon to fly around that castle.
By Jacob's telling, Spawn is now being developed autonomously by a swarm of Fable-powered agents costing over $3 million in tokens per month ("we spend 30x payroll on AI tokens").
Our agents change the live code directly and ship to production hourly, so they read every error, bug report and metric themselves. About 60% of our work starts from a production error, a Savi bug report (Savi is the AI you build games with in Spawn), something odd in our logs, or a feature request.
Savi files bugs herself. When a user hits one, or Savi hits one in the product, she files it. It goes straight to an agent that decides whether it's a real bug to fix, something we won't fix, or intentional design that needs a decision. Usually it becomes a change, delivered to that user within an hour, with a message in the same chat.
This is continuous deployment turned up to 11:
A loop this tight only works if it never stops, so we treat an hour without a ship as a SEV-0, our most severe kind of incident. Unshipped changes pile up, and every problem already in production lasts longer. The feedback slows down too. An agent can only keep a few hours of work in its head, so shipping faster than that actually helps it stay coherent. [...]
We can roll back a broken change in 30 seconds, exactly where it's broken and nowhere else. When a monitor or a log alert fires, it starts or wakes an agent that owns the incident, and we break things on purpose to test that those recovery paths work.
My eyebrows raised at least a dozen times reading this. I have trouble imagining this style of development working on software with higher stakes for when something goes wrong, but for a game this appears to be working surprisingly well.
Jacob says that Fable 5 (and then 5.1) was the model that made this level of autonomy possible. Opus 5.5 doesn't quite hack it for them, and when they tried GPT-6 Astra to apply fixes from a security review everything stopped working:
Every feature had been disabled and marked to be turned on again once the security fixes were done. Astra had gone through our whole product and made the insecure things secure by turning them off.
These kinds of extreme experiments are why I'm excited about game development as a substrate for exploring the edges of what today's coding agents can do.
In general, LLM performance is incredibly multidimensional. There's no guarantee of a fixed ordering where the model that is best at math is also the model that's best at jokes. Despite that complexity, much of the variation in performance is explained by just a single variable: model size. In general, models that are bigger will (a) be more performant / reliable, (b) cost more per token, and (c) have better recall of esoteric facts. As you note, our models are ordered:
Luna < Terra < Sol < Astra
[...] These days, version number signifies a few things at once: the order of release, the relationship to other releases, and the magnitude of improvement. So something like 6.1 would indicate it was launched after 5.6, may share some similarities to other 6.1 models in terms of training data / personality (which is why it's not 5.7), and isn't a giant enough leap to merit the headlines and expectations that would come with a 7.
— Ted Sanders, explaining OpenAI's model naming conventions
GitHub Octoverse 2026. I'm at GitHub Universe today (GitHub gave me a free ticket through their "GitHub Stars" program). EVP Jay Parikh just announced this year's Octoverse report, and highlighted these numbers in particular:
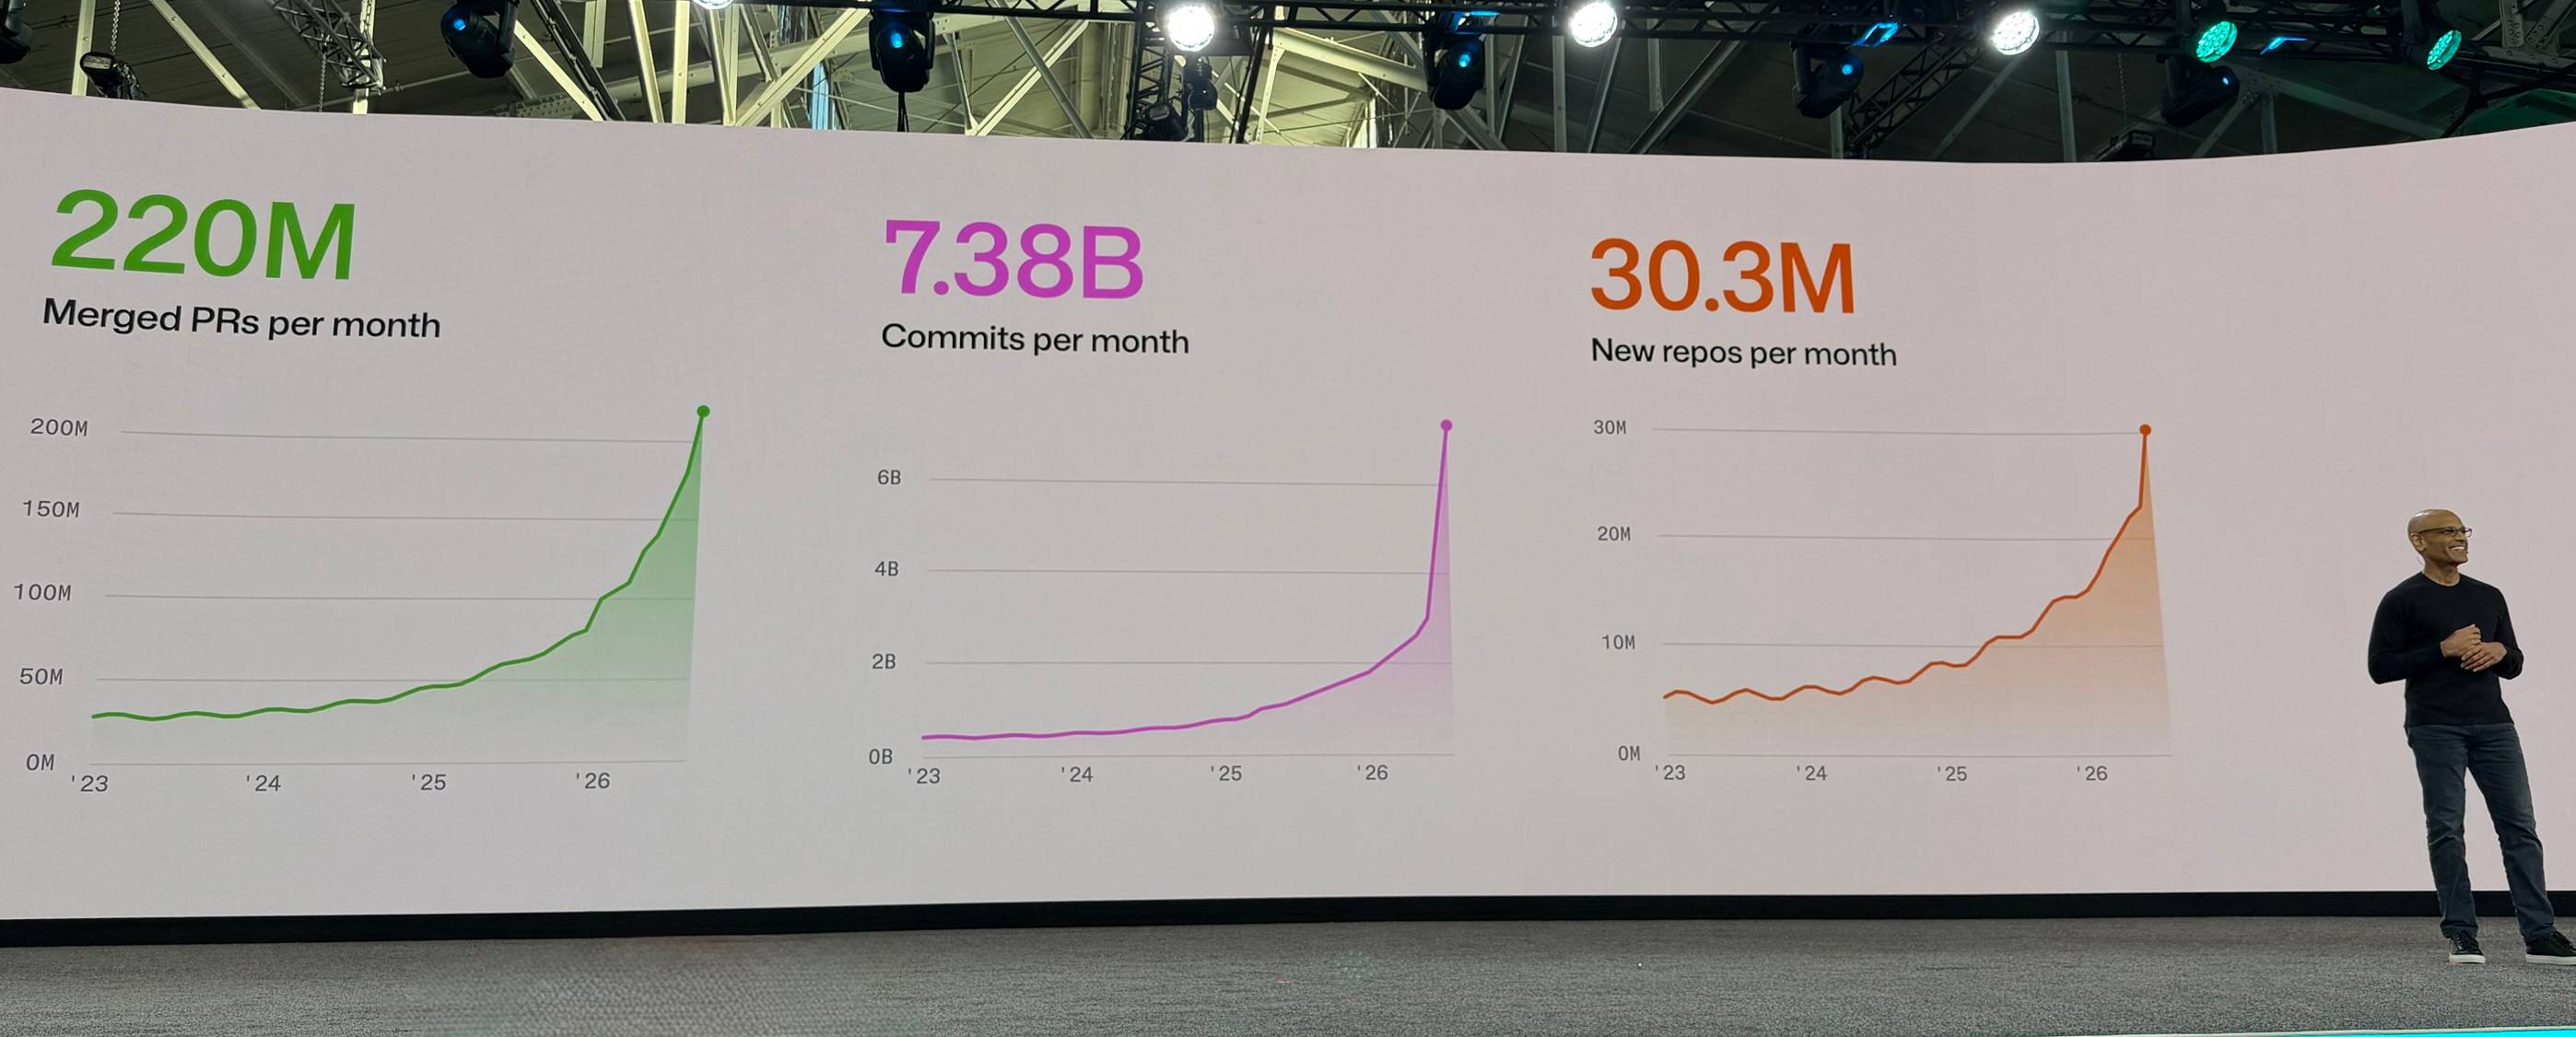
This is a pretty stark representation of the impact of agentic engineering on GitHub. In 2026, merged pull requests tripled in less than a year to 220 million per month. Commits more than tripled to 7.38 billion per month, with most of that increase in the second half of this year. New repository rate doubled this year, to 30.3 million per month.
The report includes new numbers by industry, and breaks out numbers for repositories that involve "interoperability or reverse engineering". The methodology section includes notes about how they did this:
Top countries by pushes to public repositories, adjusted by profile location. Pushes from each country were summed across the Octoverse year. To adjust for biases caused by VPN usage, LLM classification was used to extract the ISO 3166-1 alpha-2 code from the profiles of GitHub users who contributed pushes during this period [...]
Industry. Public repositories created 2022 to 2026 were sorted into NAICS sectors by a fine-tuned multilingual embedding model using name, description, topics, and README, from random samples per year. [...]
Interoperability. Counts public repositories created each year whose name, description, topics, or README mention interoperability or reverse engineering, or related terms, such as clean room implementation, drop-in replacement, or protocol re-implementation.
The October inflection point for vibe game development
I’ve written before about how November 2025 was an inflection point for coding agents—the point where Opus 4.5 and GPT-5.1 crossed a tipping point that meant their respective coding agents became reliable daily drivers for software engineers. I think we’ve reached a new inflection point in October 2026, and this time it’s for vibe coding computer games.
[... 3,254 words]
Comment My comment on The Web Is More Than Enough, by Paul Ford — Hacker News
OK, this comment convinced me to give that a shot.
Here's a thing I made in Three.js this morning - a Nudibranch themed Faberge Egg: https://static.simonwillison.net/static/2026/Hidden-Reef-Egg... (77KB)
I just asked Claude (Opus 5.5 Medium running in regular Claude Chat) to port that to Vanilla JS, in the same thread where it had built it, and got this: https://static.simonwillison.net/static/2026/Hidden-Reef-Egg... (98KB)
They aren't identical - you can see what Claude said about that in the transcript (I don't fully understand why it differed): https://claude.ai/share/e56d163e-2793-4677-aa11-191d5058b414
But yeah, it turns out Claude Opus 5.5 is perfectly capable of 3D modeling in Vanilla JS + WebGL without Three.js.
In eyeballing the code I find the Three.js slightly easier to understand myself, but I rarely look at the code for these 3D projects so that isn't a particularly big deal.
# 9th November 2026, 4:32 am / hacker-news, javascript, ai, generative-ai, llms, claude, three-js