Simon Willison’s Weblog

Subscribe

15th September 2026

Tool Gemini Live audio — Talk to Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking with live audio conversations. The interface captures real-time speech input, displays transcripts of your conversation, and allows you to interrupt responses naturally or send text messages. Extended Thinking models support configurable reasoning levels while processing conversations that can include optional document context for reference.

Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live family.

I pointed GPT-6 Astra Extra High at the documentation and had it build me this web UI for trying out the new models. You can select a model and voice preset, enter an optional system prompt and then start a voice conversation through your browser, including the ability to interrupt the model while it is talking.
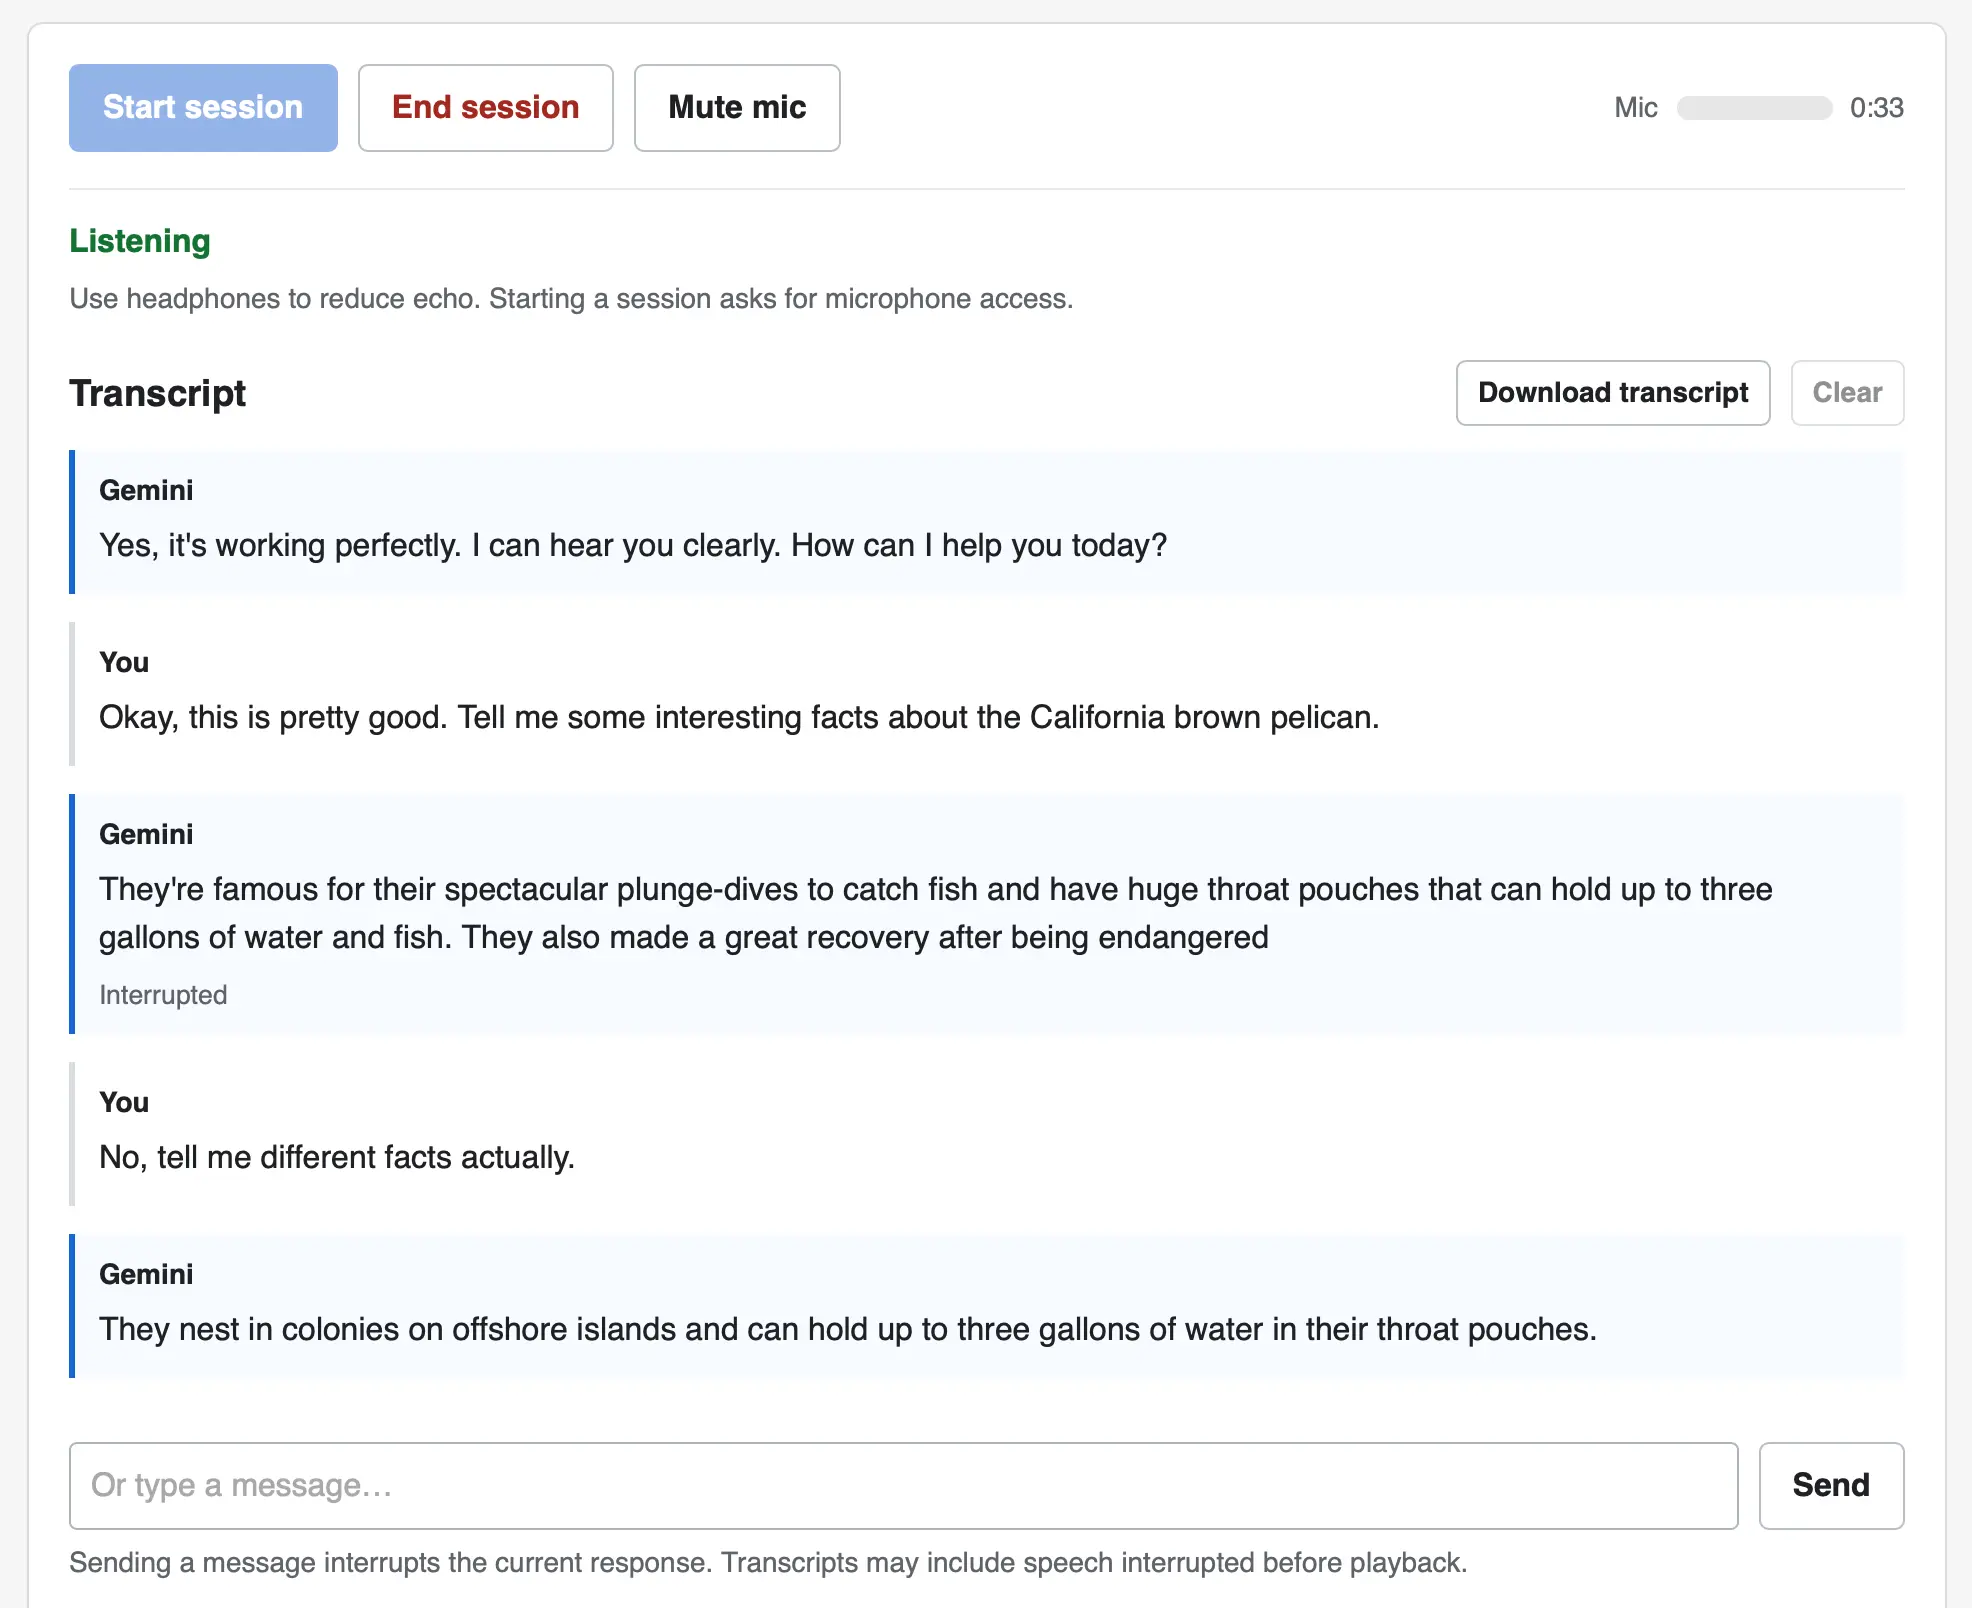
Screenshot of a voice chat web interface with a transcript. Top buttons: Start session, End session, Mute mic, plus a Mic level meter and a timer showing 0:33. Status: Listening. Use headphones to reduce echo. Starting a session asks for microphone access. Transcript (with Download transcript and Clear buttons). Gemini: Yes, it's working perfectly. I can hear you clearly. How can I help you today? You: Okay, this is pretty good. Tell me some interesting facts about the California brown pelican. Gemini: They're famous for their spectacular plunge-dives to catch fish and have huge throat pouches that can hold up to three gallons of water and fish. They also made a great recovery after being endangered — marked as Interrupted. You: No, tell me different facts actually. Gemini: They nest in colonies on offshore islands and can hold up to three gallons of water in their throat pouches. At the bottom is a text input reading Or type a message… with a Send button, and the note: Sending a message interrupts the current response. Transcripts may include speech interrupted before playback.

The implementation uses no libraries. It connects to the wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=... WebSocket endpoint and uses a Web Audio API AudioContext for both capture and playback.

Here's the Gemini Live tutorial for getting started with that WebSockets API.

Recent articles

This is a beat by Simon Willison, posted on 15th September 2026.

Monthly briefing

Sponsor me for $10/month and get a curated email digest of the month's most important LLM developments.

Pay me to send you less!

Sponsor & subscribe