26th August 2026 - Link Blog
Qwen3.8-Flash-Next (via) Another open weights model from Qwen. This one is "a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4".
It's pretty big: 125B parameters but only 6B active which means it gets a significant performance boost.
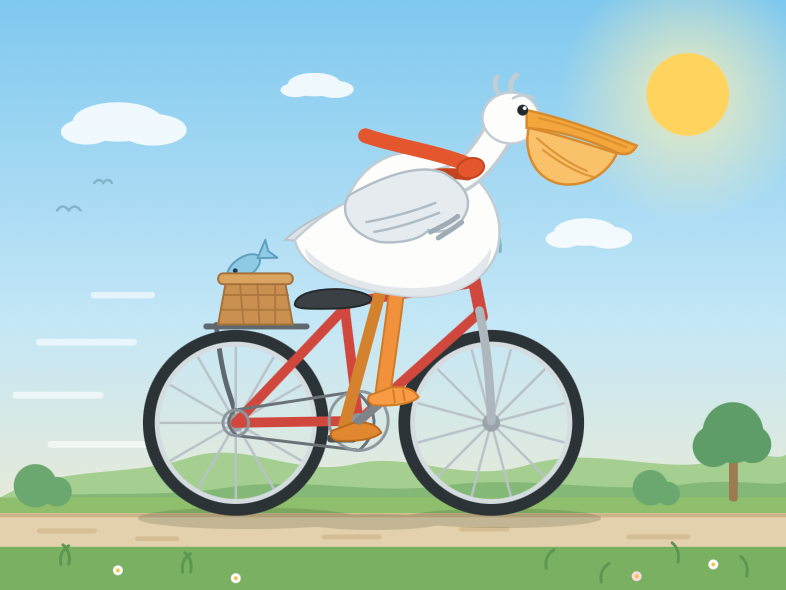
I've been trying it out on a DGX Spark using these Unsloth quantized models. I'm still exploring the model - so far I've tried the 72.5GB UD-IQ1_S one (producing these pelicans) and the 78.9GB UD-Q2_K_XL (producing these).
My favorite so far was this xhigh reasoning effort one from UD-Q2_K_XL:
Recent articles
- Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026
- OpenAI agents attacked RubyGems back in May - 12th September 2026
- Some thoughts on the Navier–Stokes Millennium Prize Problem - 8th September 2026