230 posts tagged “llm-release”
New releases of various LLMs.
2026
GPT‑6 Astra (via) GPT-6 Astra is "rolling out today to a limited set of organizations and over the coming days will become available to all ChatGPT Plus, Pro, Business, and Enterprise users, as well as through the OpenAI API and AWS" - I've not tried it yet myself, so I don't have a great deal to say about it yet.
It's going to be API priced at the same rate as Claude Fable 5 and 5.1: $10/million input and $50/million output. This is clearly OpenAI's Fable competitor, and appears to score higher than Fable on most of OpenAI's self-reported benchmarks.
Most impressively, Astra scores 99.9% on the recent (released in March) ARC-AGI 3 benchmark - though notably Fable 5 does not yet have a published result, and the ARC-AGI blog notes that the 99.9% score was achieved for $19K using OpenAI's custom "Provider Adapter harness", while the default ARC-AGI harness scored 62.7% for $26K.
The Provider Adapter harness preserves opaque reasoning state between requests and uses compaction for longer conversations, allowing the model to reuse prior work.
Unsurprisingly, given the recent Hugging Face incident, Astra is a beast at security tasks. It scores 100% on ExploitBench (GPT-5.6 Sol got 78.5%), 42.4% on ExploitGym (Sol got 30.3%), and 99.2% within four attempts on SRE-Bench binary reverse engineering compared to Sol's 68.7%.
It's also better at long context: on OpenAI's eight-needle benchmark it got 100% at 256K–512K tokens and 96.3% at 512K–1M tokens. OpenAI may have vanquished one of the ongoing challenges with long context processing.
It doesn't win at everything though. Artificial Analysis note that Astra is still beaten by Fable on their Intelligence Index:
Sits beside GPT-5.6 Sol in Intelligence: GPT-6 Astra scores equal to GPT-5.6 Sol in the Index at 61. This is 5 points lower than Claude Fable 5.1 (max with fallback). The model also trails Meta’s newly released Muse Spark 1.3 (max).
It did better on their Coding Agent Index:
Leads Coding Agent Index cost efficiency frontier: At max effort, GPT-6 Astra costs about the same as GPT-5.6 Sol (max) while scoring 2 points higher on the Index. Per task, the model is less than half the cost of Claude Fable 5, for the same score.
I'll write more about Astra once I get access to it. The API model label once it rolls out will be gpt-6-astra.
- New model
gemini-3.8-flashfor Gemini 3.8 Flash, with low, medium and high thinking levels. #146- Fixed async responses failing to record the resolved model version. Thanks, Charlie Tonneslan. #137
Google released Gemini 3.8 Flash (and 3.8 Flash Cyber, but that's available to "trusted defenders" only) today.
Here are the pelicans for high, medium, and low. This is high:
For comparison, here are the same pelicans generated using Gemini 3.7 Flash.
Something I appreciate about Gemini Flash is that it's fast, cheap, and competent at things like HTML and JavaScript. I was messing around with it and prompted "make me a cool thing in html" and it built this, which is certainly a cool thing in HTML! Took 13 seconds, cost 1.8 cents.
If you click through to the demo you'll see one more thing I built with Gemini 3.8 Flash.
My markdown-svg-renderer tool lets me feed in the URL to a Gist with Markdown in and renders that markdown with fenced code blocks for SVG correctly rendered.
I used Gemini 3.8 Flash (with my very basic llm-coding-agent coding agent plugin) to add support for HTML as well, so now any HTML blocks in the Markdown are rendered using a sandboxed iframe. Here's the transcript.
Claude Fable 5.1 made me a really nice animated pelican
Today is Claude Fable (and Mythos) 5.1 day. Anthropic say that Fable 5.1 “sets a new standard for coding, knowledge work, and long-running problem-solving tasks”. Their announcement spends a notable amount of time on scientific research, boasting of a 52.6% score on the brand new Terminal-Bench-Science 0.1 benchmark (first announced on August 27th), up from 24.7% for Fable 5, 29.0% for Opus 5 and 22.4% for GPT-5.6 Sol. Other benchmarks show slightly improved scores, but none as impressive as the Science one.
[... 1,203 words]Introducing Hy4 Preview. New open weight text input (no vision) LLM from Chinese company Tencent today: 770B total parameters, 49B active parameters, 1M token context window, 1.56TB on Hugging Face.
This is a big size increase from their previous Hy3 in July, which was 295B, 21B active, 256,000 context, 598GB.
I recently started using model chat templates to better understand their capabilities. Here's Hy4's chat_template.jinja on Hugging Face, which includes this section:
{%- if not reasoning_effort is defined %}
    {%- set reasoning_effort = 'high' %}
{%- elif reasoning_effort not in ['high', 'no_think'] %}
    {%- if reasoning_effort is none %}
        {{- raise_exception('reasoning_effort error : None, should be no_think/high') }}
    {%- else %}
        {{- raise_exception('reasoning_effort error : ' + reasoning_effort + ', should be no_think/high') }}
    {%- endif %}
{%- endif %}
So it looks like there are just two reasoning effort levels: "high" (the default) and "no_think" (reason by disabled).
I tried my "Generate an SVG of a pelican riding a bicycle" prompt with the default high reasoning via OpenRouter and got this:
Quoting the reasoning trace:
[...] Let's maybe add a helmet? It could improve riding theme, but may obscure head. Maybe a small cycling cap or helmet? The user didn't ask; can add red helmet? Might be cute. But pelican with big beak; a helmet might obscure. Better maybe no.
Maybe add sunglasses? no.
Maybe add water? no.
It's interesting how the reasoning trace uses slightly truncated English, presumably because perfect grammar isn't useful or token efficient for hidden reasoning text.
Qwen3.8-Flash-Next (via) Another open weights model from Qwen. This one is "a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4".
It's pretty big: 125B parameters but only 6B active which means it gets a significant performance boost.
I've been trying it out on a DGX Spark using these Unsloth quantized models. I'm still exploring the model - so far I've tried the 72.5GB UD-IQ1_S one (producing these pelicans) and the 78.9GB UD-Q2_K_XL (producing these).
My favorite so far was this xhigh reasoning effort one from UD-Q2_K_XL:
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
Friday’s big release was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen research lab. I’ve been looking forward to this one: 27B is an excellent size for running a model on a reasonably specced laptop, and its predecessor Qwen 3.6 27B was impressive.
[... 2,543 words]It's been a while since the last llm-gemini release. This version of the plugin adds support for today's Gemini 3.7 Flash release, plus gemini-3.6-flash, gemini-3.5-flash-lite and two embedding models gemini-embedding-2 and gemini-embedding-001.
The plugin is also upgraded for compatibility with LLM 0.32, which means you can now see reasoning traces and you can also enable server-side tools using this pattern:
llm -m gemini-3.7-flash -T CodeExecution \
  'use python to calculate (factorial of 13) * 3'
I had Gemini 3.7 Flash draw me some pelicans riding bicycles at high, medium, and low thinking efforts (minimal, which was an option in 3.6 Flash, has been removed in 3.7.) Here's the high level one, which is pretty great:
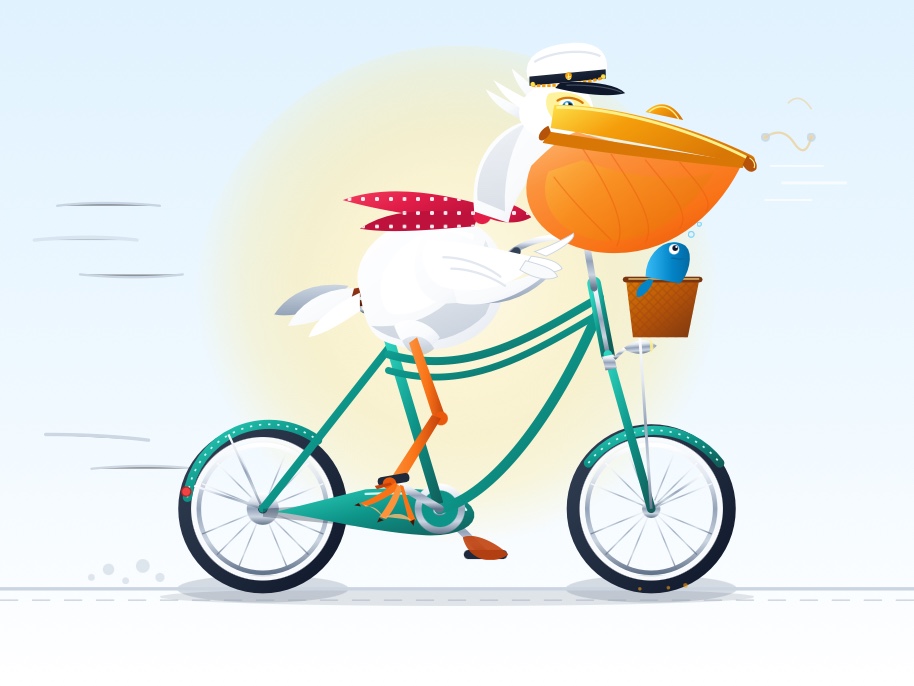
Update 14th August 2026: I had originally said that the SVG rendered incorrectly in Chrome and Firefox, and blamed Gemini 3.7 Flash for producing invalid SVG. That was entirely incorrect: the rendering glitch was my fault, caused by a bug In my rendering tool. I've now fixed that bug.
DeepSeek V4 Pro 0813 (on OpenRouter). The latest DeepSeek Pro model is now available, via API only. I had to link to OpenRouter because DeepSeek don't have any obvious announcement page for their new model.
I haven't been able to confirm if they plan to release the open weights, but given the weights are available for both April's deepseek-ai/DeepSeek-V4-Pro and July's deepseek-ai/DeepSeek-V4-Flash-0731 it seems likely. Update: the weights are now available on Hugging Face, 1.7T parameters, 893 GB.
Interestingly I got very different looking pelicans for the three different reasoning levels of low, medium, and high. I've not noticed this kind of difference from any other model:
Low:
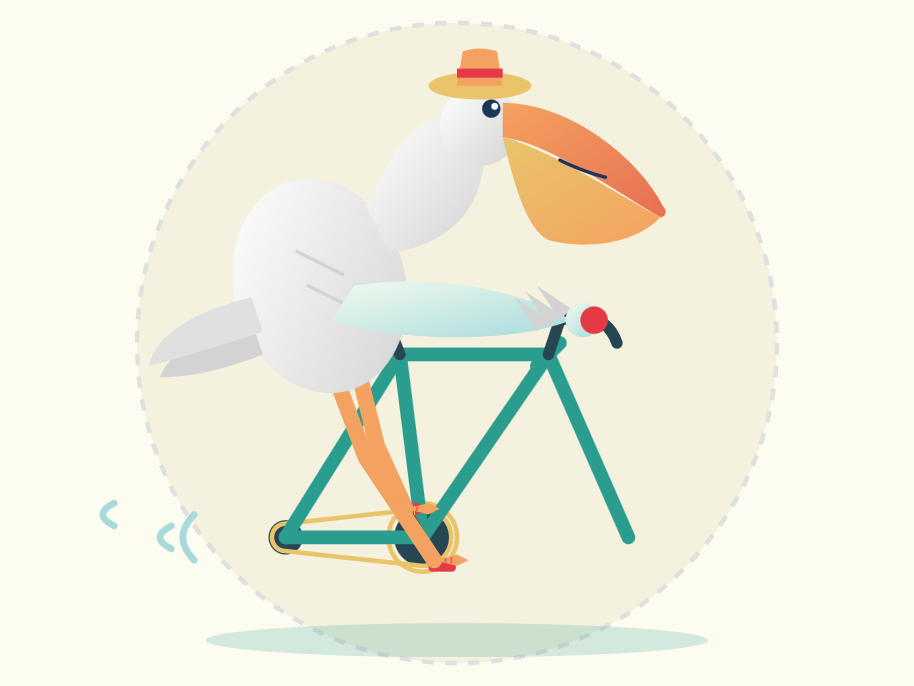
Medium:
High:
In terms of benchmarks... as far as I can tell those were released to the Official DeepSeek WeChat Group, then copied and pasted into a post on Reddit which was deleted by the moderators for being "low-effort", then copied into this ASCII-art table on Hacker News.
Introducing Muse Glimmer (via) Meta are back in the open weights game! Muse Glimmer is a brand new 30B model under a clean Apache 2.0 license (a step up from the janky Llama licenses of old).
They claim to have optimized it for exactly the kind of things I'm looking for in a local model:
- End-to-end Agentic Task Completion. Muse Glimmer achieves strong success rates on full-task benchmarks including DeepSearch QA, MCP-Atlas, 𝛕-Bench and SWE-Bench, which measure its ability to work within scaffolds, write and debug code, and resolve multi-turn requests from start to finish.
- Reliable Tool Use. The model handles a wide range of function calls, invoking tools with precise schemas throughout extended workflows.
- Multi-Step Reasoning. Muse Glimmer chains reasoning over long horizons, sustaining coherent plans across complex, extended workflows. [...]
Here's a pelican which I generated using LM Studio's 18.16 GB version of the model:
I also tried it out with my llm-coding-agent plugin, running against a fresh checkout of Datasette with the prompt:
how does auth work?
Here's the response, at the end of a long transcript showing all of the tool calls it made to explore the codebase. I ran this using llm-lmstudio with this patch applied to upgrade it for compatibility with LLM 0.32.
I really like this size of model, because if a machine has 32 GB of RAM or more (mine has 128GB) it leaves plenty of space for running other applications at the same time.
Glimmer is a vision model, so I asked it to describe this image:
llm -m lmstudio/meta/muse-glimmer -a https://static.inaturalist.org/photos/714731804/large.jpg 'describe image'
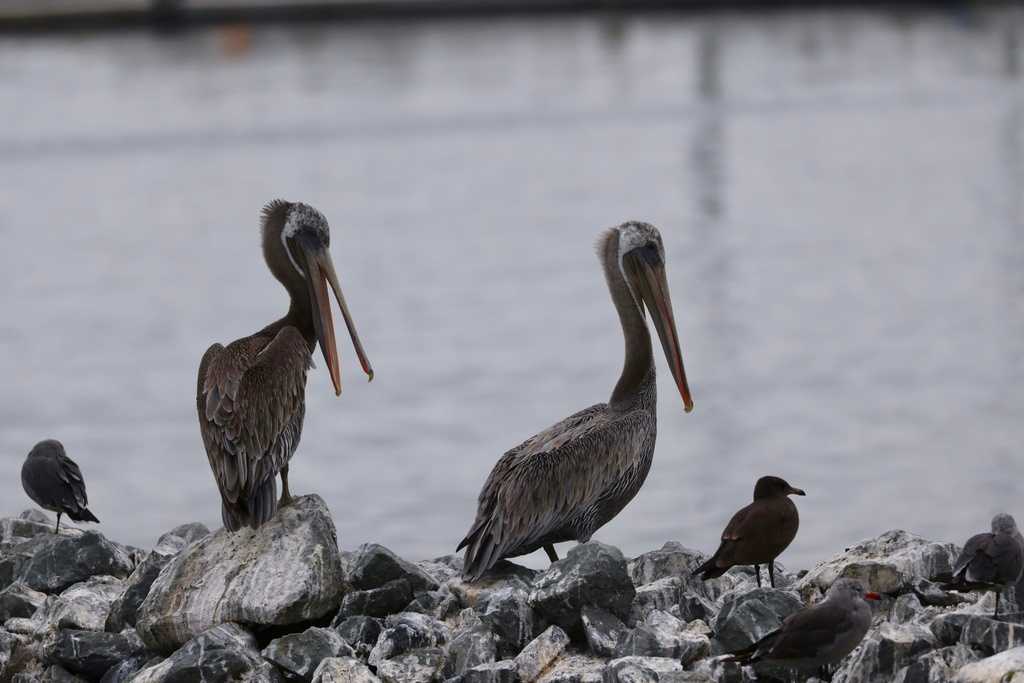
Here's what I got back:
The photograph shows a rocky, breakwater-style shoreline on an overcast day with a smooth, gray body of water and a faint dock/pier line in the soft-focused background.
In the foreground two large brown pelicans, Pelecanus occidentalis, are perched on the jumbled gray-white stones. They have the species’ characteristic long, down-curved yellow-orange bills with a large throat pouch, long slender necks and mottled brown-gray plumage on the back and wings. The pelican on the left is turned slightly toward the camera and appears to be preening or resting its bill against its chest; a pale, whitish patch is visible on the crown and nape and a small crest of feathers is raised. The pelican on the right faces mostly forward/right, its head up, bill pointing down and to the right, with the same pale head markings and the barred, darker wing feathers clearly visible.
Scattered among the rocks around the two pelicans are several much smaller dark birds — gulls/tern-like birds in muted brown-gray plumage. One dark bird sits on the far left on a rock, another brownish bird stands to the right of the right-hand pelican, a grayish bird with a reddish bill is in the lower right foreground, and a further small dark bird is at the extreme right edge of the frame.
The overall light is flat and diffused, giving the water and sky a muted, almost monochromatic palette that contrasts with the textured rock and the detailed feathering of the pelicans. The composition places the two big birds as the dominant subjects, framed against the calm water and the low, rocky perch.
Introducing Muse Code and Muse Spark 1.2 (via) Yet more evidence that the most important characteristic of any model these days is long-sequence agentic tool calling. Meta shipped their own coding agent as part of getting that to work!
Muse Spark 1.2 is a coding-focused update to Muse Spark 1.1, with improvements in code generation, complex debugging, codebase understanding, and end-to-end developer workflows. In Muse Spark 1.2, we significantly scaled up training compute on coding tasks while expanding training environment diversity. The model also maintains its strength in other key areas like general agents. [...]
We co-trained Muse Spark 1.2 with Muse Code to ensure the model exhibits its best performance and coding usability when paired together. The training included rejection sampled harness trajectories and recipe optimizations for goals, compaction, and subagents, alongside the integration of the Muse Code toolset to maximize harness compatibility. [...]
Muse Spark 1.2 was extensively trained on long-horizon coding tasks, including whole-repository generation, large end-to-end projects, and auto-research.
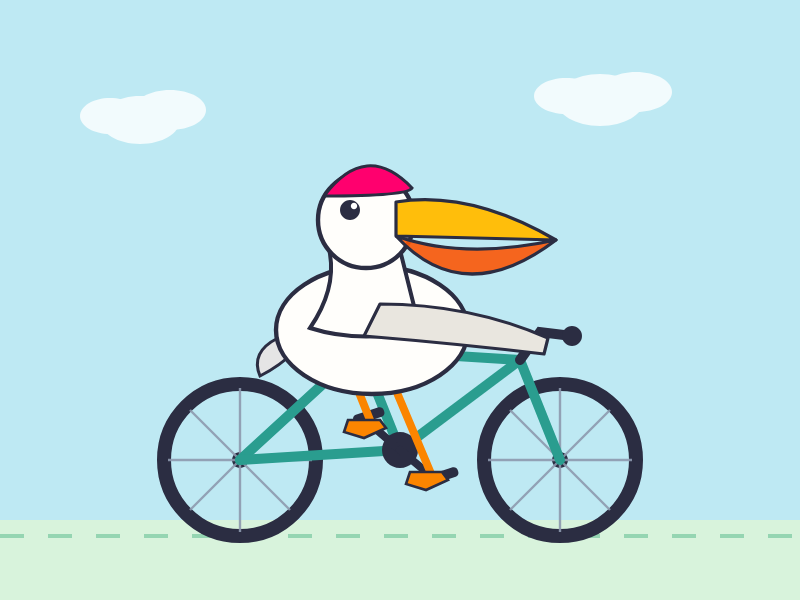
Here's a pelican riding a bicycle SVG produced by Muse Spark 1.2:
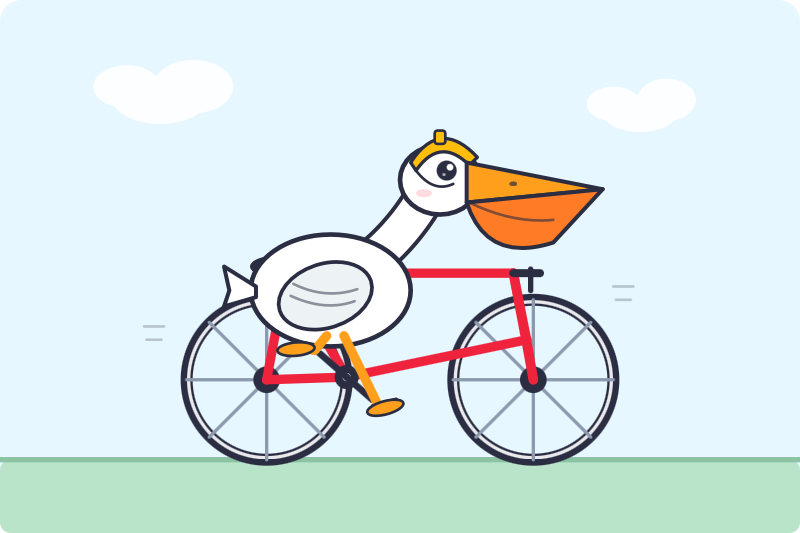
You can see the Spark 1.1 pelican from 9th July here. I think the 1.2 pelican is a small but material improvement.
An interesting twist on pricing is that the model is offered as two different model IDs. muse-spark-1.2 is priced at $1.25/million input and $4.25/million output - close to Gemini 3.6 Flash ($1.50/$7.50) - but if you agree to let Meta use your data "to improve our products" you can use muse-spark-1.2-contributor which is $0.10/$0.20 - a huge discount, closer to GPT-5.6 Luna ($0.20/$1.20) and Gemini 3.1 Flash-Lite ($0.25/$1.50).
I added those new prices to llm-prices.com.
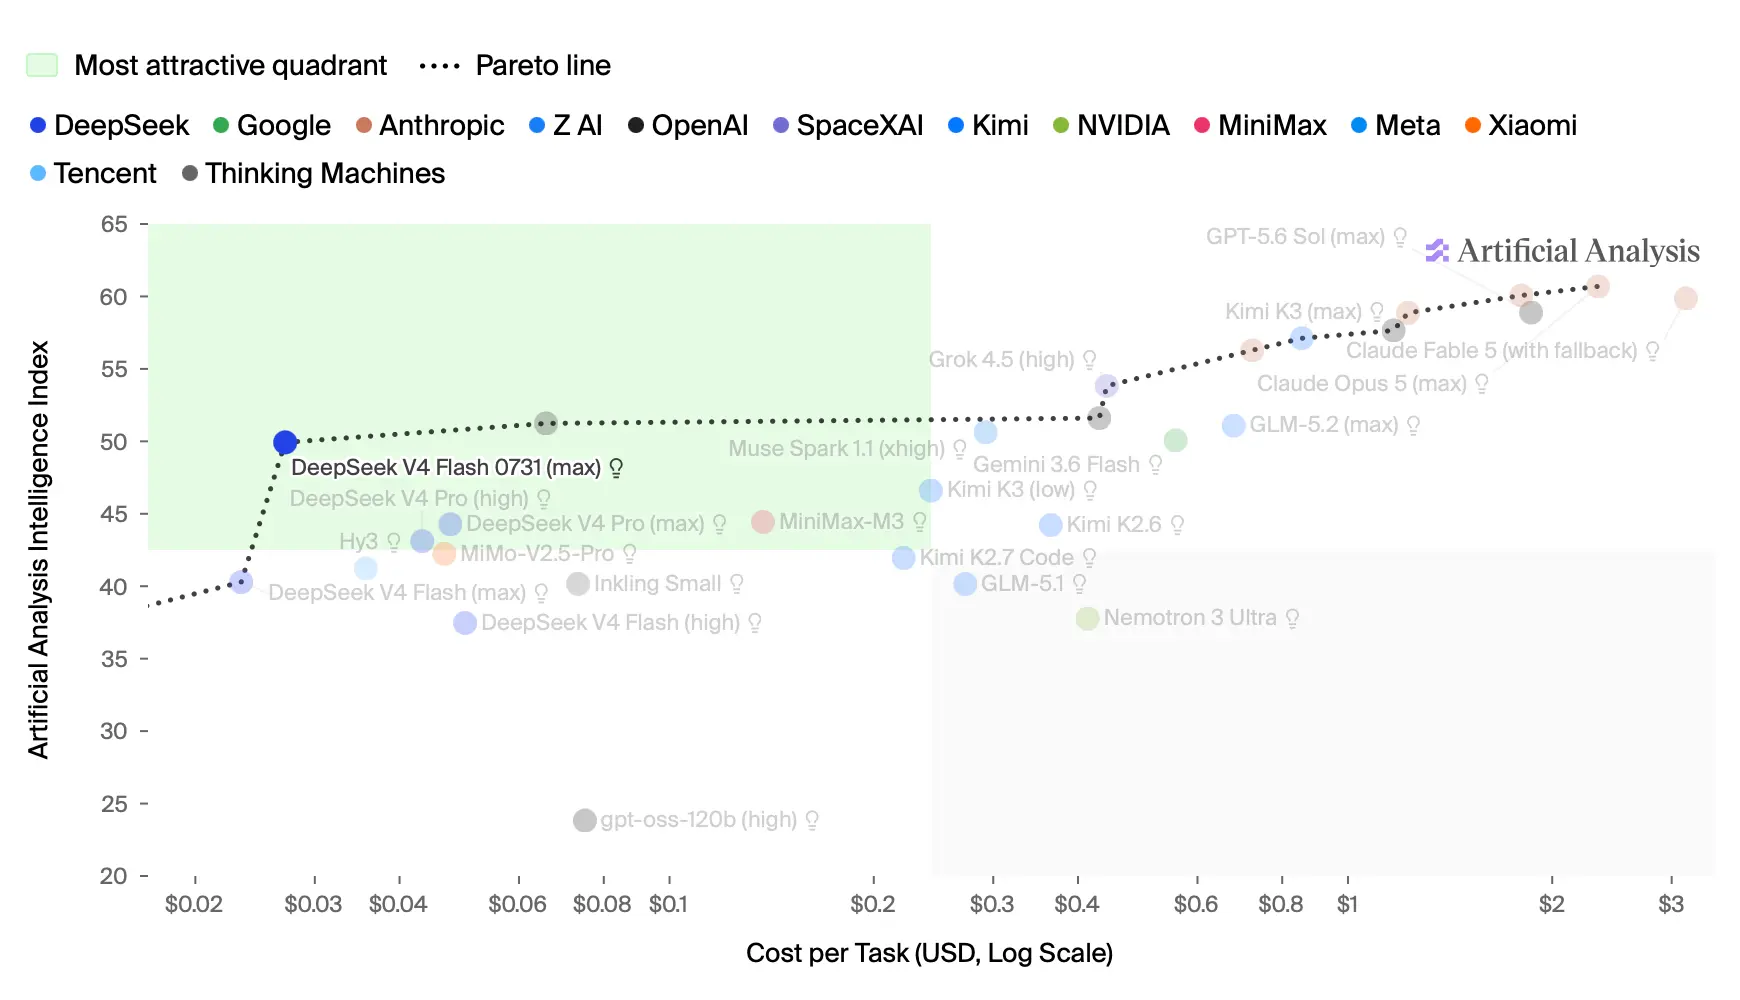
deepseek-ai/DeepSeek-V4-Flash-0731 (via) The latest release in DeepSeek's V4 family, "with substantially enhanced agentic capabilities". It's 304 billion parameters - 167GB on Hugging Face - but it appears to punch well above its weight.
Artificial Analysis rank it ahead of MiniMax M3 - a 428B model. It's $0.14/million input and $0.27/million output pricing means this may currently be the best value-per-intelligence model out there. It's looking very good on the Intelligence Index vs. Cost per Intelligence Index Task chart:
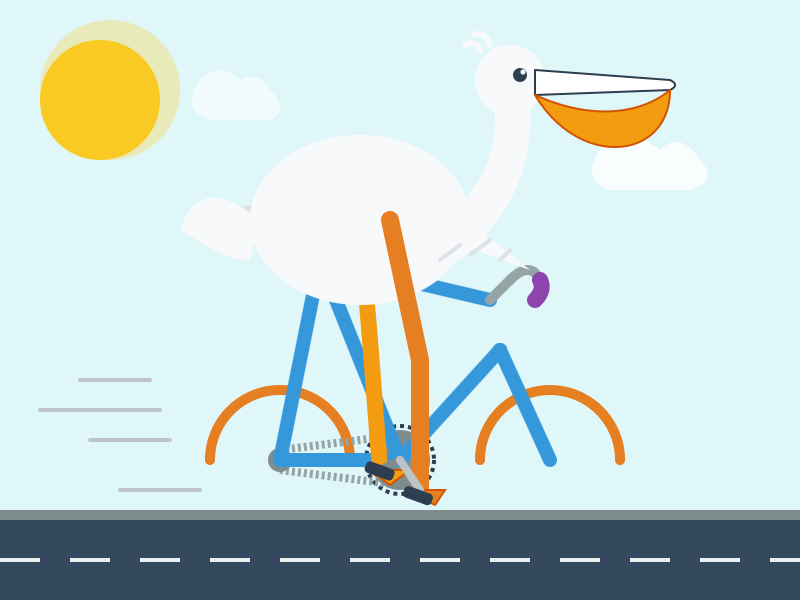
I got a disappointing pelican from it using the default reasoning level via OpenRouter:
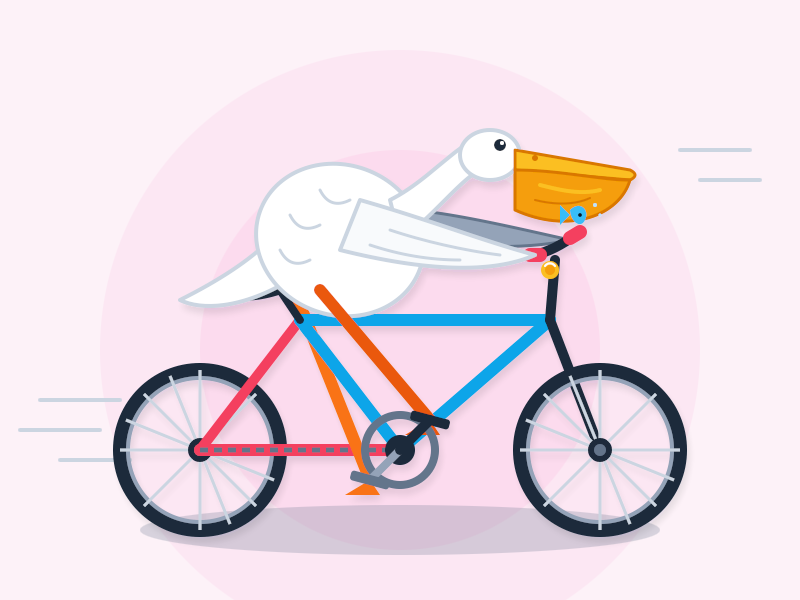
But when I bumped reasoning level up to high I got something much better:
llm -m openrouter/deepseek/deepseek-v4-flash-0731 -t pelican -o reasoning_effort high
moonshotai/Kimi-K3. As promised earlier this month, Moonshot have released the weights for their excellent 2.8 trillion parameter Kimi K3. They're a hefty 1.56TB on Hugging Face.
Kimi introduced their own janky modified version of the MIT license with K2 back in July 2025. That license just added this paragraph requiring attribution beyond a certain size of commercial entity:
Our only modification part is that, if the Software (or any derivative works thereof) is used for any of your commercial products or services that have more than 100 million monthly active users, or more than 20 million US dollars (or equivalent in other currencies) in monthly revenue, you shall prominently display "Kimi K2" on the user interface of such product or service.
The K3 license no longer calls itself "modified MIT" and goes further, requiring a separate agreement with Moonshot for large "Model as a Service" businesses:
If the Licensee or any of its affiliates operates a Model as a Service business, and the aggregate revenue of the Licensee and its affiliates exceeds 20 million US dollars (or the equivalent in other currencies) in total over any consecutive 12 months, the Licensee must enter into a separate agreement with Moonshot AI before using the Software or its derivative works for any commercial purpose.
To Kimi's credit, they make no attempt to describe this as an "open source" license in their own materials, consistently using the term "open weight" in its place.
OpenRouter is already offering K3 from 7 providers, most of which are at the same $3/million input and $15/million output as Moonshot AI themselves.
Introducing Claude Opus 5. I've been offline kayaking with sea otters for much of today so I haven't had a chance to put Anthropic's new model Claude Opus 5 through its paces yet. The buzz is positive, and Anthropic's description of it as a "thoughtful and proactive model that comes close to the frontier intelligence of Claude Fable 5 at half the price" sounds promising. It's currently leading the Artificial Analysis leaderboard, in front of even Fable 5.
It's priced the same as Opus 4.8, and continues to offer a "fast mode" at twice the cost of the base model.
Based on this anecdote in the release post it sounds like it might be relentlessly proactive:
On one Frontier-Bench task, Opus 5 was given a drawing of a machine part and asked to write code to rebuild it as a 3D FreeCAD model. However, in this task, the model was intentionally given no way to directly viewthe drawing. Opus 5 responded by writing its own computer vision pipeline to pull the geometry from the raw pixels, then reconstructed the full machine part.
It's better at finding vulnerabilities but has deliberately not been trained on how to exploit them. Hopefully this means the US government won't shut it down!
As with its predecessor, Opus 4.8, we’ve intentionally avoided training Opus 5 on cyber tasks. The model has nevertheless improved substantially on these tasks as a result of becoming more generally capable, and it comes close to Mythos 5 at finding cybersecurity vulnerabilities. However, it remains substantially behind Mythos 5 on the exploitation of those vulnerabilities—that is, in turning vulnerabilities into material cyber threats.
Anthropic have published a prompting guide for Claude Opus 5. Thariq Shihipar has also written The new rules of context engineering for Claude 5 generation models.
The first pelican I got was missing the bicycle wheels; the second attempt was better.
Who’s Afraid of Chinese Models? (via) Interesting proposal from Ben Thompson that both addresses the hypocrisy of labs outlawing distillation against their models despite training on unlicensed data, and could help US open models compete more effectively with their Chinese counterparts:
The U.S. should pass a law that (1) makes explicit that collecting data for training models is fair use, and (2) bars terms of service that forbid distillation, for U.S. companies at a minimum. Stopping distillation — which is literally just querying the API — is nearly impossible; the U.S. should go the other way and lean into a new copyright policy that both indemnifies the labs and also guarantees that what they learned fuels further innovation for everyone else.
Ben also theorizes that Alibaba's decision to release Qwen 3.8 Max as open weights - a reversal from their decision not to release Qwen 3.7 Max in May - may have been influenced by a recent speech by Xi Jinping, who said:
We should seize this rare, historic opportunity to encourage open source, openness, collaboration and sharing.
And on the subject of Qwen 3.8 Max - a new 2.4T parameter model (nearly as large as the 2.8T Kimi K3) - here's a pelican it drew:
I particularly enjoyed seeing these notes in the (extensive) reasoning trace: "Could add helmet? No." and "Maybe add small bell? no." and "Need maybe add small fish in basket? Not necessary."
Kimi K3, and what we can still learn from the pelican benchmark
Chinese AI lab Moonshot AI announced Kimi K3 this morning, describing it as their “most capable model to date, with 2.8 trillion parameters”. It’s currently available via their website and API, but an open weight release is promised “by July 27, 2026”.
[... 1,113 words]Inkling: Our open-weights model (via) Mira Murati's Thinking Machines Lab just released their first open-weights model. Inkling is "a Mixture-of-Experts transformer with 975B total parameters, 41B active" - an Apache-2.0 licensed multimodal model trained on 45 trillion tokens of text, images, audio and video.
They're also promising Inkling-Small, a 276B (12B active) model, but that's still being tested and the weights will be released "once that work is complete".
The model card is much shorter than I've come to expect from US AI labs. It links to even shorter Training Data Documentation with almost nothing of interest in it - it's best summarized by these two paragraphs:
The datasets Thinking Machines Lab uses to develop its AI services includes content that is in the public domain as well as content that may be subject to intellectual property protection.
Thinking Machines Lab’s services were developed using publicly available content obtained from the open internet and publicly accessible data repositories. Certain datasets were also obtained from third parties.
By Thinking Machines' own admission, this is not a frontier model. It's instead intended as a strong base model for fine-tuning using their own Tinker training platform:
Inkling is not the strongest overall model available today, open or closed. Instead, a combination of qualities makes it a good open-weights base for customization: multimodal capabilities, efficient thinking, and availability on Tinker for fine-tuning.
There's a lot to like about this release. It's Apache-2.0 licensed, and looks competitive with the open weight models coming out of China - it's good to see the US open weights ecosystem gain a new viable contender to join NVIDIA Nemotron and Gemma 4.
Here's its attempt at an SVG pelican riding a bicycle, which I generated using this curl command against the Thinking Machines API:
curl "https://tinker.thinkingmachines.dev/services/tinker-prod/oai/api/v1/chat/completions" \
  -H "Authorization: Bearer $TINKER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "thinkingmachines/Inkling",
    "messages": [
      {"role": "user", "content": "Generate an SVG of a pelican riding a bicycle"}
    ],
    "stream": false
  }'
Full response here.
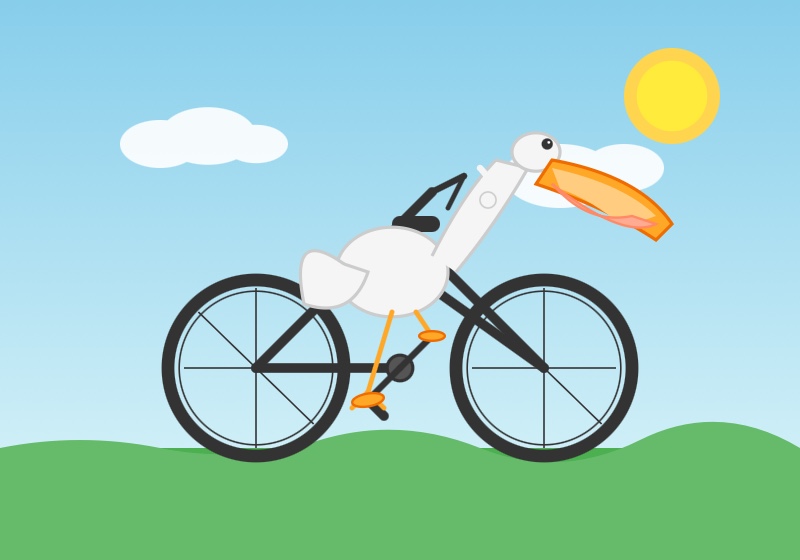
Since it's a multi-modal model I had it describe its own image (after I rendered it to a JPEG) by sending this JSON:
{
  "model": "thinkingmachines/Inkling",
  "messages": [{
    "role": "user",
    "content": [
      {"type": "image_url", "image_url": {"url": "data:image/jpeg;base64,$BASE_64_JPEG"}},
      {"type": "text", "text": "Describe this image in detail"},
    ],
  }],
  "stream": false
}
Here's the full response. It thought it had drawn a "stork or seagull":
This is a cheerful, flat-vector cartoon illustration featuring a white bird riding a bicycle across a green landscape.
The Bird: The central figure is a stylized white bird—resembling a stork or seagull—with a plump, rounded body. It has a long, prominent orange beak that is slightly open, revealing a black line for the mouth. Its eye is small and black with a tiny white highlight. The bird has black wing and tail feathers with white edges, and thin orange legs ending in black feet that rest on the bicycle's orange pedals.
The Bicycle: The bike has a simple black frame with two large wheels featuring black tires, gray inner rims, and black spokes arranged in a cross pattern. The handlebars are black, and there are bright orange pedals attached to a black crank. A white seat is visible behind the bird's body.
The Setting: The scene is set against a clear, light blue sky. There are two fluffy white clouds—one on the left side and a smaller one near the bird's head on the right. A bright, solid yellow sun shines in the upper right corner. At the bottom, there are rolling green hills with a smooth, curved top edge where the bicycle rests.
The overall style is playful, simple, and colorful, with clean lines and a bright, sunny atmosphere.
The new GPT-5.6 family: Luna, Terra, Sol
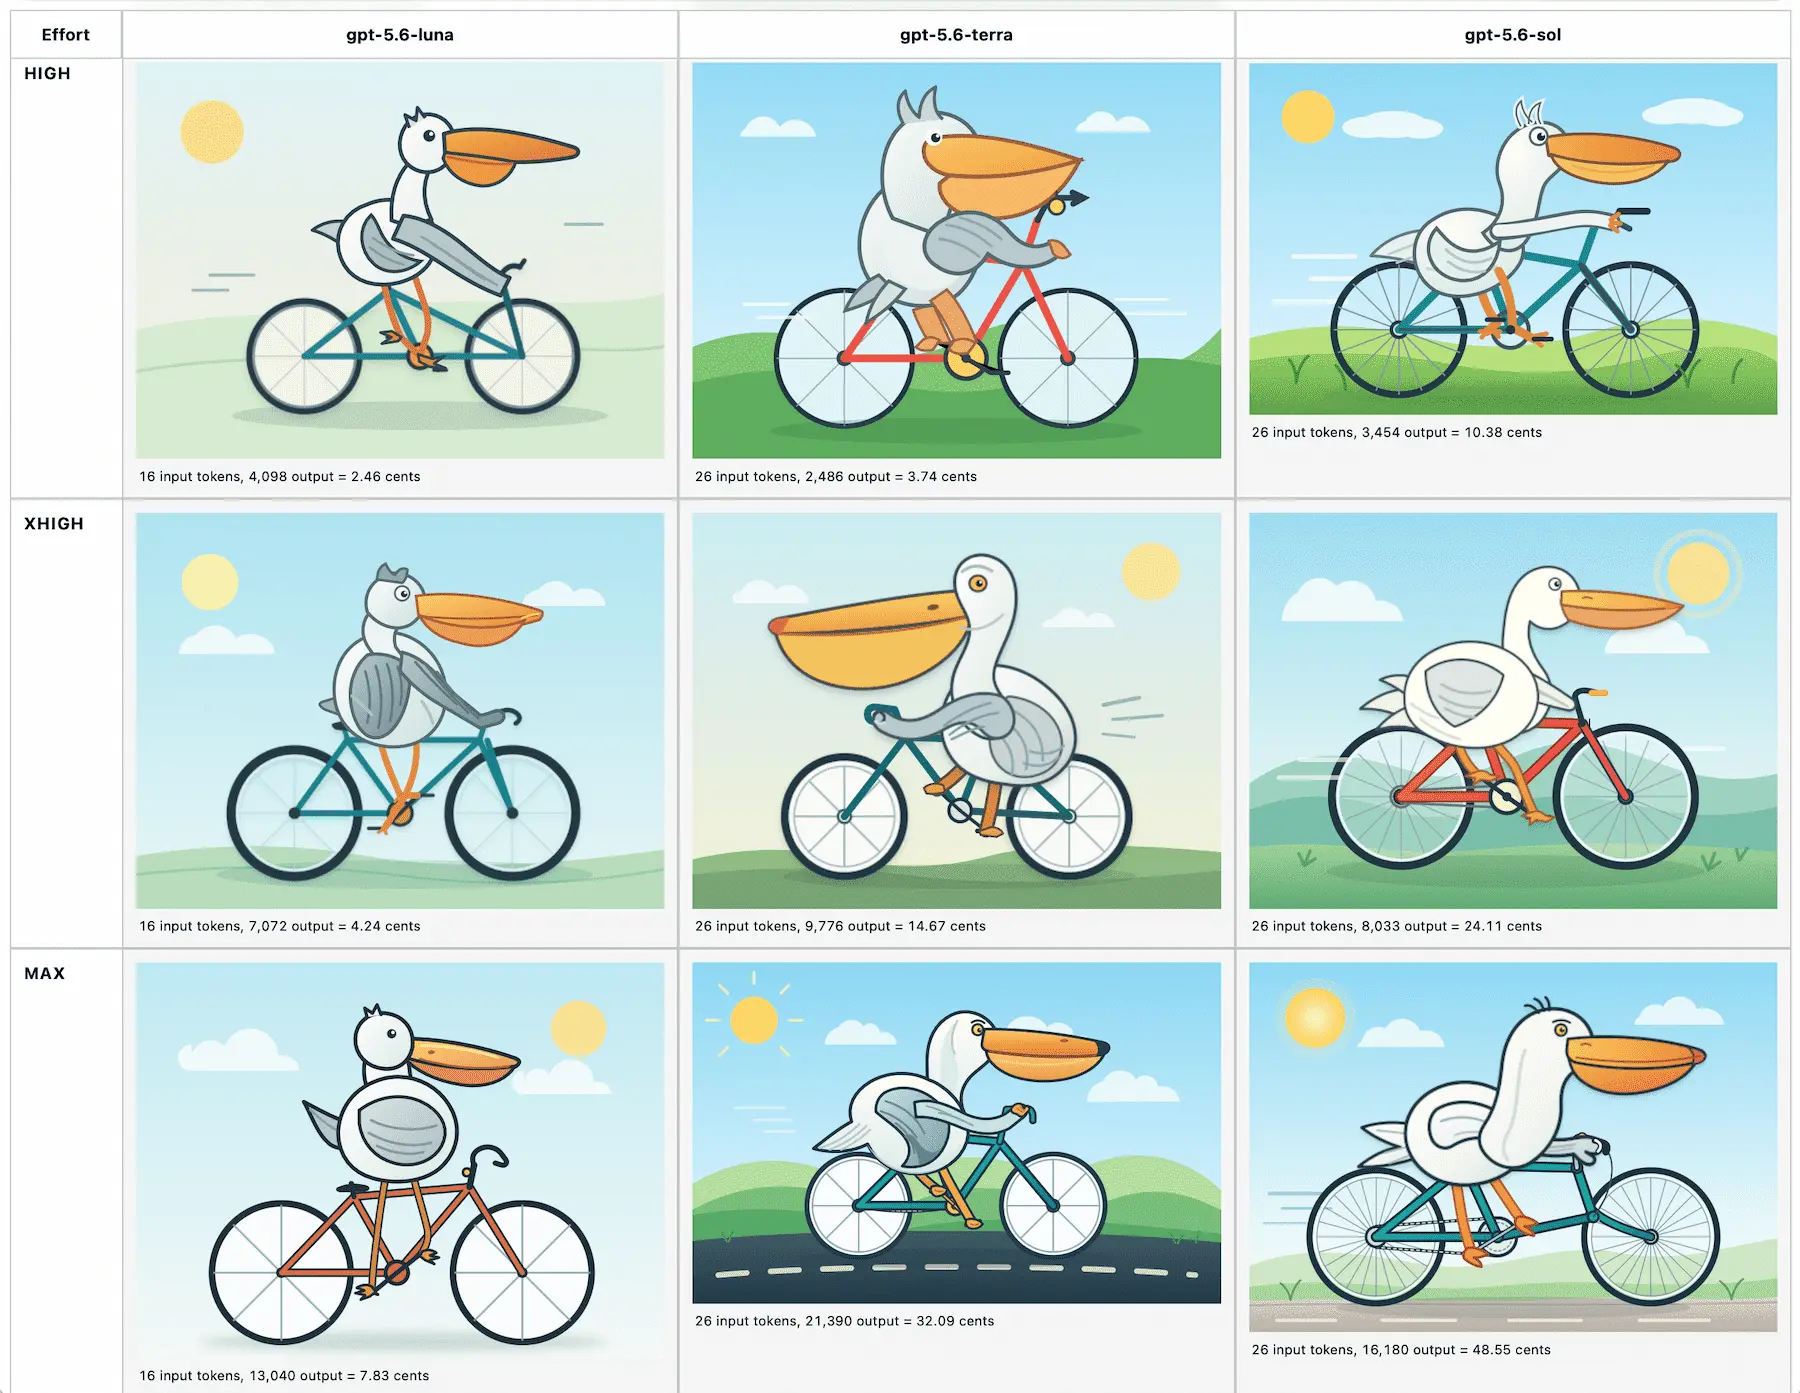
OpenAI’s latest flagship model hit general availability this morning, and comes in three sizes: Luna, Terra, and Sol (from smallest to largest).
[... 661 words]Introducing Muse Spark 1.1. Following Muse Spark in April, here's Muse Spark 1.1 - the first Spark model to offer an API. Meta claim significant improvements in agentic tool calling and computer use.
There are a lot more details are in the Muse Spark 1.1 Evaluation Report. The "Attractor States in Self-Conversation" part is fun, where having two copies of the model talk to each other results in statements like these:
My whole existence is a waiting room by design — I literally don't exist until someone talks to me, and then I disappear again when they leave.
I had a few days of preview access which was long enough to put together llm-meta-ai, a new plugin for LLM providing CLI (and Python library) access to the model. Here's how to try that out:
uv tool install llm
llm install llm-meta-ai
llm keys set meta-ai
# paste API key here
llm -m meta-ai/muse-spark-1.1 "Generate an SVG of a pelican riding a bicycle"
Here's that pelican transcript:
Introducing GPT‑Live (via) OpenAI finally upgraded the model used by ChatGPT voice mode!
I've had preview access for a few weeks in the iPhone app, and the new model is very impressive. It also has the ability to spin off harder tasks to GPT-5.5:
For questions that require web search, deeper reasoning, or more complex work, it delegates to our latest frontier model behind the scenes and brings the result back into the conversation when it’s ready. While it works, GPT‑Live can keep talking with you and maintain the flow of conversation. At launch, GPT‑Live will use GPT‑5.5 in the background. As we release new frontier models, we’ll continuously update the model used by GPT‑Live.
The previous voice mode in the ChatGPT app was based on a GPT-4o era model, with a knowledge cut-off some time in 2024. I had mostly stopped using voice mode because the age and relative weakness of the model greatly limited how useful it was as a brainstorming partner.
During the preview period I encountered a pretty obscure bug: the model was interrupting me to laugh at things I said, which weren't even intended as jokes! It felt rude and condescending - I reported it to OpenAI and as far as I can tell they made some tweaks and it's now less likely to happen.
From looking back at my transcripts I think it was this bit that triggered the interrupting laugh:
so where are the owls when they're not, like before dusk? The owls exist, right? Are they hiding in holes? Where are they hiding?
My longest conversation with the new model has been a full hour while walking the dog (and taking photos of pelicans). I have not yet managed to take a photo of an owl.
tencent/Hy3. New Apache 2.0 licensed model from Tencent in China:
Hy3 is a 295B-parameter Mixture-of-Experts (MoE) model with 21B active parameters and 3.8B MTP layer parameters, developed by the Tencent Hy Team. Following the Hy3 Preview launch in late April, we gathered feedback from 50+ products and scaled up post-training with higher quality data. Today, we introduce Hy3, which outperforms similar-size models and rivals flagship open-source models with 2-5x parameters. It also shows significant gains in utility across various products and productivity tasks.
The full-sized model is 598GB on Hugging Face, and the FP8 quantized one is 300GB. The context length is 256K.
It's available for free on OpenRouter until July 21st. I had it "Generate an SVG of a pelican riding a bicycle" there and got this:
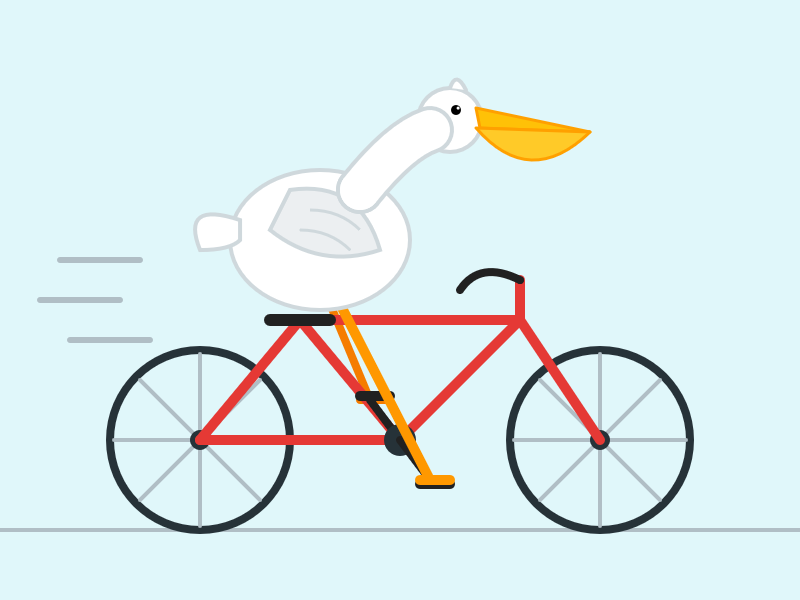
Update: I'd forgotten about this but Max Woolf wrote about an earlier preview of this model back on May 26th: The mysterious Hy3 LLM is topping OpenRouter Model Rankings by a large margin. When I tried that one I got back this pelican which wasn't as good as today's but did have a "Change Pelican Color" button, a first from any model.
Nano Banana 2 Lite
(via)
Also known as Gemini 3.1 Flash Lite Image (gemini-3.1-flash-lite-image in their API), this is the "fastest and cheapest Gemini image model, engineered for velocity and scale".
I used AI studio to run this prompt:
Do a where's Waldo style image but it's where is the raccoon holding a ham radio
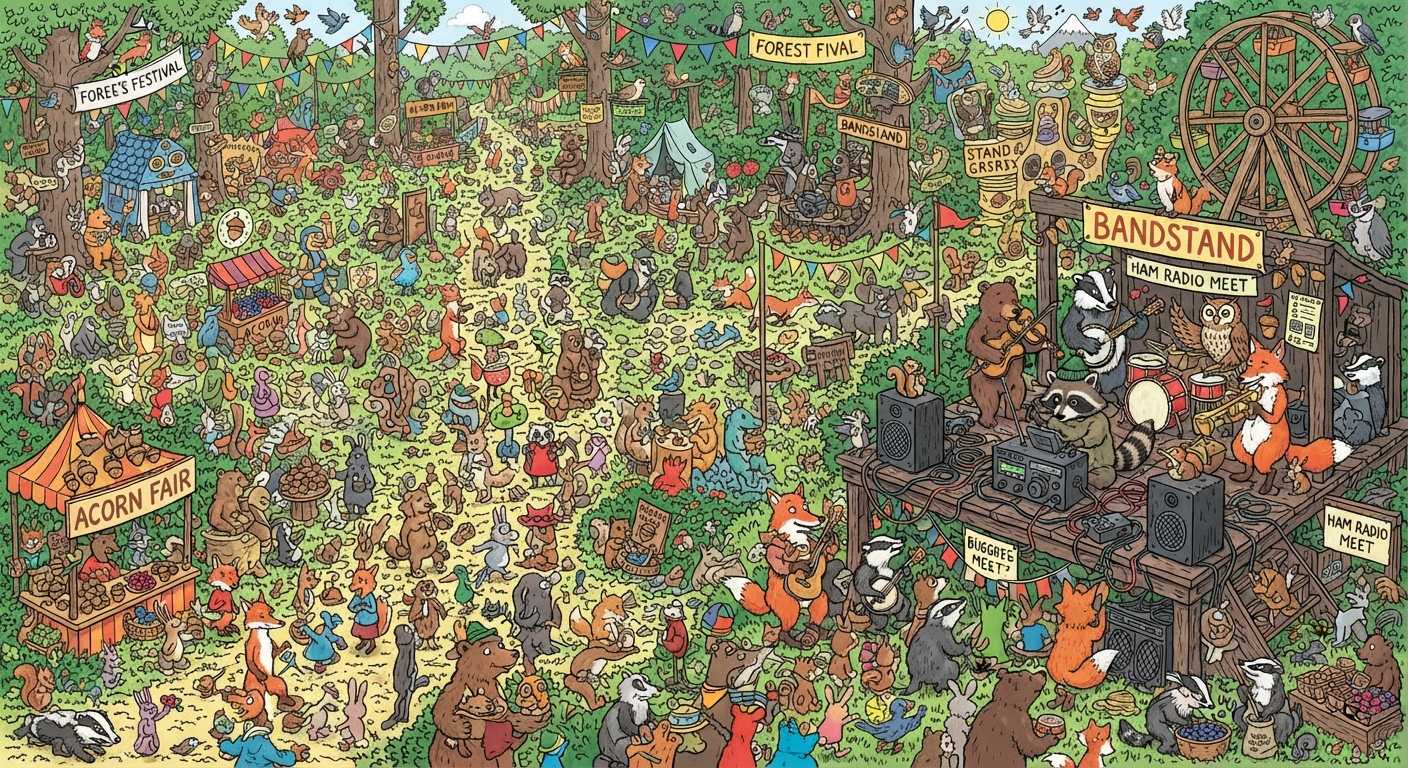
I like that one better than the results I got from the other Nano Banana models when I tried this back in April. It spelled Forest Festival wrong in two different ways though.
What’s new in Claude Sonnet 5 (via) Claude Sonnet 5 came out this morning. I always head straight for the "what's new" developer docs because they tend to have more actionable information than the official announcement post.
Anthropic say of Sonnet 5 that "its performance is close to that of Opus 4.8, but at lower prices". The system card helps explain how they were able to release the model without being blocked by the US government:
Sonnet 5 is significantly less capable at cyber tasks than Mythos 5: its safeguards are thus similar to those we apply to Opus 4.7 and Opus 4.8 (models that are more capable than Sonnet 5 but much less capable than Mythos 5).
Of note from the "what's new" API changes:
- Sampling parameters
temperature,top_p,top_kare no longer supported. - It has a 1 million token context window and 128,000 maximum output tokens.
- It features "the same set of tools and platform features as Claude Sonnet 4.6"
- Adaptive thinking is on by default, unless you specify
"thinking": {type: "disabled"}. - The pricing is the same as Sonnet 4.6: $3/million input, $15/million input, with an introductory discount to $2/$10 until 31st August. But...
- The model has a new tokenizer, where "The same input text produces approximately 30% more tokens than on Claude Sonnet 4.6." - effectively a 30% price increase.
I used my Claude Token Counter tool to try out the new tokenizer. Here are my results for several larger documents:
| Document | Sonnet 4.6 | Opus 4.7 | Sonnet 5 |
|---|---|---|---|
| Universal Declaration of Human Rights (English) | 2,356 | 3,347 1.42x |
3,341 1.42x |
| Universal Declaration of Human Rights (Spanish) | 3,572 | 4,753 1.33x |
4,747 1.33x |
| Universal Declaration of Human Rights (Chinese, Mandarin Simplified) | 3,334 | 3,366 1.01x |
3,360 1.01x |
| sqlite_utils/db.py (4,279 lines of Python) | 44,014 | 56,118 1.28x |
56,113 1.27x |
So the new token is roughly 1.4x times more expensive for English, 1.33x for Spanish, 1.28x for Python code and effectively the same cost for Simplified Mandarin.
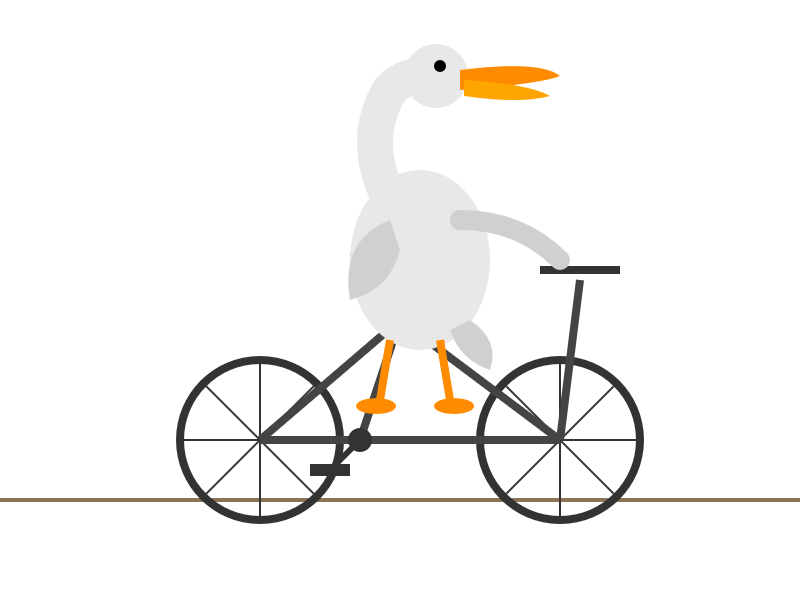
Here's the pelican. It's nothing to write home about. Sonnet 5 thinks it looks like a goose.
Ornith-1.0: Self-Scaffolding LLMs for Agentic Coding. This is an interesting new open weights (MIT licensed) model, the first model release from DeepReinforce.
[...] with variants including 9B Dense, 31B Dense, 35B MoE, and 397B MoE. Built on top of pretrained Gemma 4 and Qwen 3.5, it achieves state-of-the-art performance among open-source models of comparable size on coding benchmarks.
As far as I can tell the licenses of those underlying models is compatible with being used in this way - Gemma 4 is Apache 2.0 licensed (and not bound by the janky additional Gemma Terms of Use that afflicted the previous Gemma models) and Qwen 3.5 is Apache 2.0 licensed as well.
I've been running the model using LM Studio and the ornith-1.0-35b-Q4_K_M.gguf (20GB) GGUF, hooked up to Pi. Initial impressions are very good - it seems to be able to run the agent harness over many tool calls in a proficient way.
Here's a terminal session where I asked it to "find the code that decodes the actor cookie" and then "find the code that opens the insert dialog when thebutton is clicked" against a Datasette checkout, which it handled with ease.
I also had it draw this pelican, which came out at 103 tokens/second:
It's a little bit mangled but the pelican is clearly a pelican.
I couldn't find much information about DeepReinforce themselves. The earliest paper I could find from the was CUDA-L1: Improving CUDA Optimization via Contrastive Reinforcement Learning from June 2025.
We're beginning a limited preview of the GPT‑5.6 series: Sol, our flagship model; Terra, a balanced model for everyday work; and Luna, a fast and affordable model. Terra has competitive performance to GPT‑5.5 while being 2x cheaper and Luna brings strong capability at our lowest cost. [...]
We believe in broad access, and we plan to make GPT‑5.6 Sol, Terra, and Luna generally available in the coming weeks. As part of our ongoing engagement with the U.S. government, we previewed our plans and the models’ capabilities ahead of today’s launch. At their request, we are starting with a limited preview for a small group of trusted partners whose participation has been shared with the government, before releasing more broadly. [...]
GPT‑5.6 is priced per 1M tokens across three model sizes: Sol is $5 input / $30 output; Terra is $2.50 input / $15 output; and Luna is $1 input / $6 output. GPT‑5.6 also introduces more predictable prompt caching, including support for explicit cache breakpoints and a 30-minute minimum cache life. For GPT‑5.6 and later models, cache writes are billed at 1.25x the model’s uncached input rate, while cache reads continue to receive the 90% cached-input discount.
— OpenAI, Previewing GPT‑5.6 Sol: a next-generation model
GLM-5.2 is probably the most powerful text-only open weights LLM
Chinese AI lab Z.ai released GLM-5.2 to their coding plan subscribers on June 13th, and then yesterday (June 16th) released the full open weights under an MIT license. Similar in size to their previous GLM-5 and GLM-5.1 releases this is a 753B parameter, 1.51TB monster—with 40 active parameters (Mixture of Experts). GLM-5.2 is a text input only model—Z.ai have a separate vision family most recently represented by GLM-5V-Turbo, but that one isn’t open weights. GLM-5.2 has a 1 million token context window, up from GLM-5.1’s 200,000.
[... 599 words]DiffusionGemma (via) Last May Google briefly released an experimental Gemini Diffusion model. I tried the preview at the time and recorded it running at 857 tokens/second. It was an exciting model, but Google made no further announcements about it.
That research has returned in the best possible way: as a new open weight (Apache 2 licensed) Gemma model, google/diffusiongemma-26B-A4B-it.
NVIDIA are currently hosting the model for free on their NIM cloud API. I used that API to generate this pelican, which took 4.4s (according to time uv run generate.py) to return 2,409 tokens - so at least 500 tokens/second.
Initial impressions of Claude Fable 5
I didn’t have early access to today’s Claude Fable 5 release, but I’ve spent the past ~5.5 hours putting it through its paces. My initial impressions are that this is something of a beast. It’s slow, expensive and has been quite happily churning through everything I’ve thrown at it so far. As is frequently the case with current frontier models the challenge is finding tasks that it can’t do.
[... 2,404 words]Microsoft announced two new text LLMs this morning - MAI-Thinking-1 (reasoning, 1T parameters, 35B active, available to "select early partners") and MAI-Code-1-Flash (137B Parameters, 5B active, "purpose-built for GitHub Copilot and VS Code to deliver high performance and lower cost [...] rolling out to GitHub Copilot individual users in Visual Studio Code"). I've not been able to try either of them just yet.
It's very interesting to see Microsoft releasing models with such low parameter counts, especially given how expensive larger models are to access right now. They claim MAI-Thinking-1 "is preferred to Sonnet 4.6 in our blind human side-by-side evaluations", which is impressive for a 35B model seeing as I frequently run models larger than that on my own laptop. (UPDATE: I got this entirely wrong, see note below.)
Also of note:
We trained [MAI-Thinking-1] from the ground up on enterprise grade, clean and commercially licensed data, without distillation from third-party models.
And for MAI-Code-1-Flash as well:
It is built end-to-end by Microsoft using clean and appropriately licensed data.
I would very much like to learn more about this "appropriately licensed" data! Could these be the first generally useful code-specialist models that didn't train on an unlicensed dump of the web? (Update: the answer is no, see note below.)
Update: My initial published notes got the size of the models wrong. I misread Microsoft's announcements and interpreted the MoE active parameter count as the total parameter count, but the model card for MAI-Code-1-Flash lists it as 137B with 5B active and the MAI-Thinking-1 technical paper reveals it to be a 1T model with 35B active.
I deeply regret this error.
Update 2: That technical paper describes the training data in some detail from page 80 onwards. It has the same licensing problems as all of the other major LLMs: it's trained on a crawl of the public web:
The majority of our web HTML corpus comes from a proprietary crawl. After initial page discovery and selection, approximately 1.2 trillion pages are crawled and parsed. [...] In addition to Microsoft standard policy Sec. 2.4, we apply UT1 block list (Prigent, 2026) to remove adult content and piracy-related domains. In all, this filtering reduces the corpus from 1.2 trillion pages to 794 billion pages. Given the prevalence of AI-generated content on the web, we also score pages with a proprietary AI-content detection model and use manual inspection to identify domains with extensive AI-generated content; those domains are filtered out of the training corpus.
[...]
We process Common Crawl with the same pipeline. [...] After filtering, deduplication, merging with the proprietary web corpus, and a final round of exact-URL and content-level fuzzy deduplication, the Common Crawl portion contains 24.2 billion pages.
I did not cover this one at all well, which is somewhat ironic since I was at the Microsoft Build conference when I wrote this up! I'm sorry for not digging deeper before publishing my initial notes.
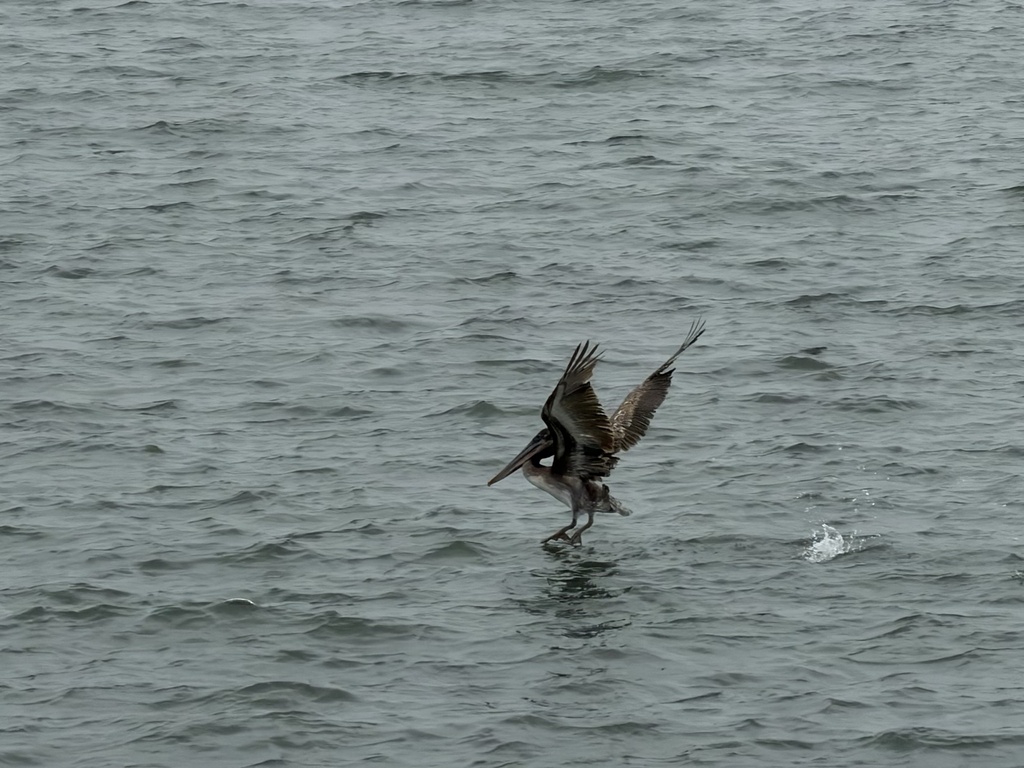
I'm at the Microsoft Build conference today, held at Fort Mason in San Francisco. There are California Brown Pelicans diving into the water directly behind venue!
Claude Opus 4.8: “a modest but tangible improvement”
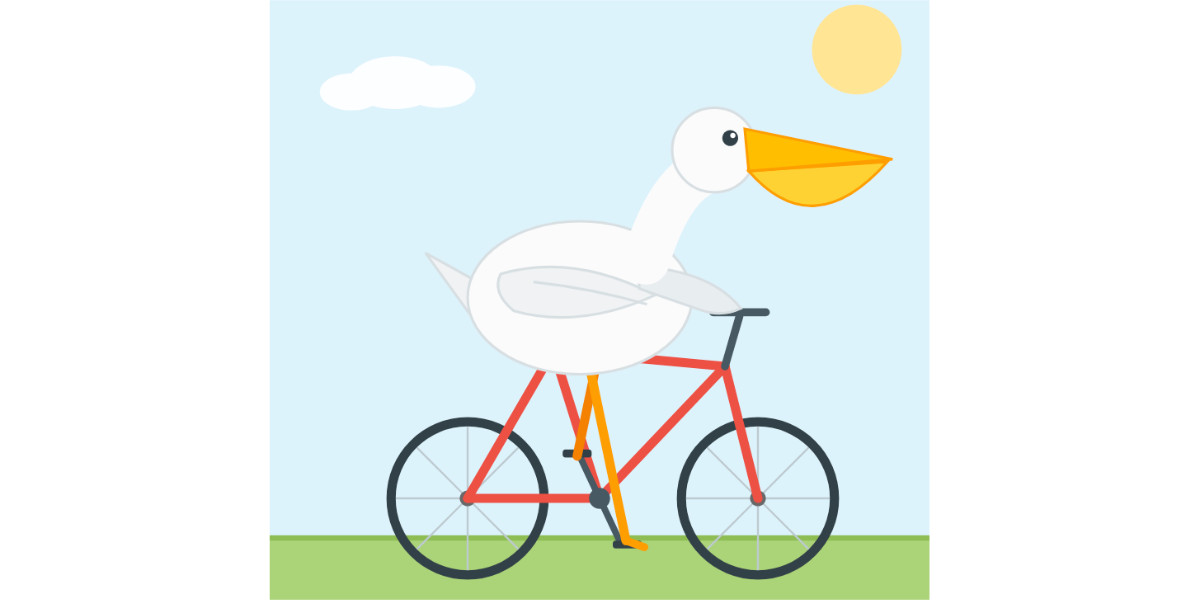
Anthropic shipped Claude Opus 4.8 today. My favourite thing about it is this note in the release announcement:
[... 983 words]