655 posts tagged “llm”
LLM is my command-line tool for running prompts against Large Language Models.
2026
Today Google introduced Gemini 4 Neon. I wrote recently about how confusing the pricing for the Gemini 4 series was - Neon has somehow made this even worse.
Previously the Gemini 4 lineup was Hydrogen, Argon, and Carbon - where Argon and Carbon were the same price, and Hydrogen was 3/4 of that price now but will be 1/4 of that price when the other two double an 1st December once their initial discount pricing expires.
The Neon announcement pretends that Argon doesn't exist. Here's their new image explaining the model line-up:
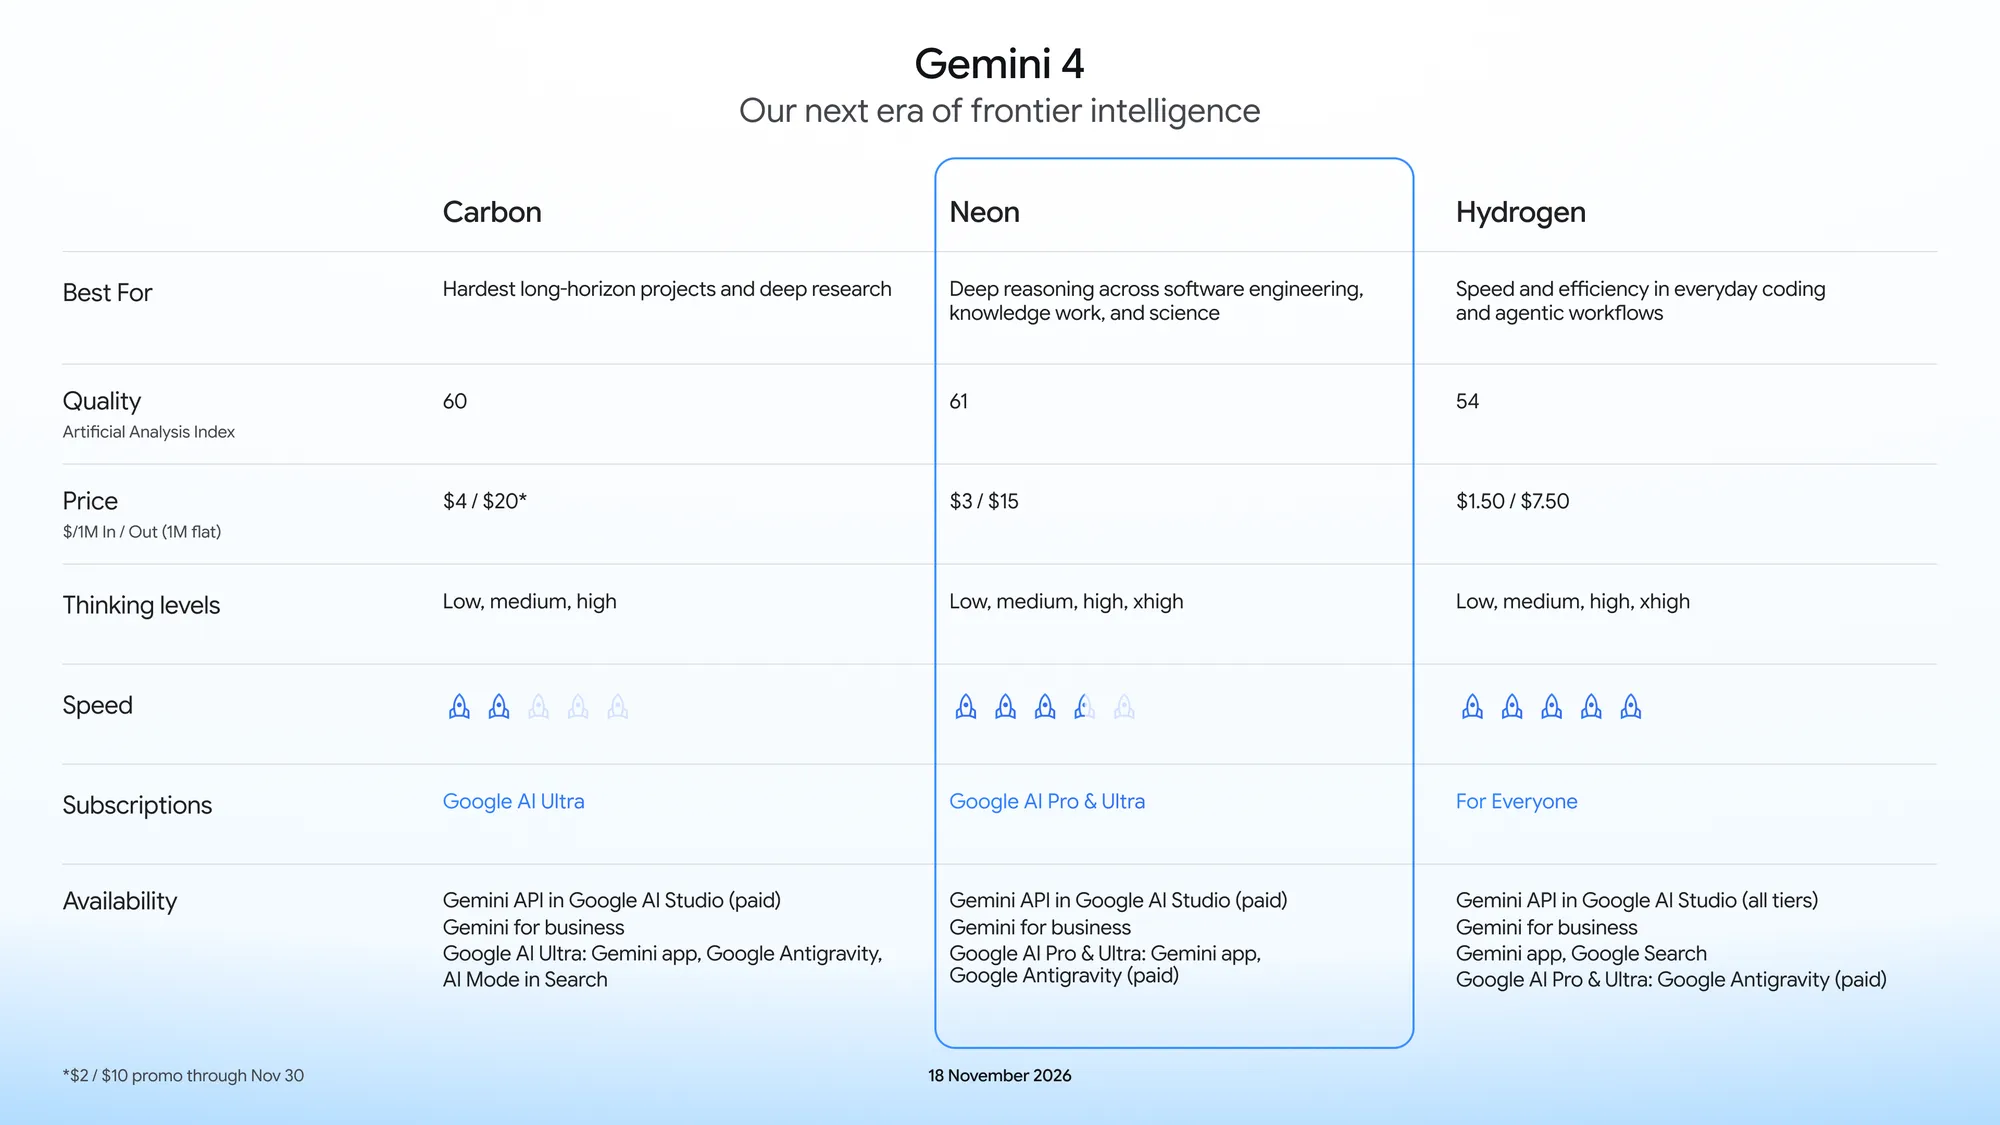
So the lineup now, from most to least expensive, is Carbon, Neon, Hydrogen.
Except Carbon is currently half price, so right now Neon ($3/million input, $15/million output) is the most expensive of the three - then Carbon ($2/$10), then Hydrogen ($1.50/$7.50). I guess this will make more sense when Carbon doubles to $4/$20 on December 1st.
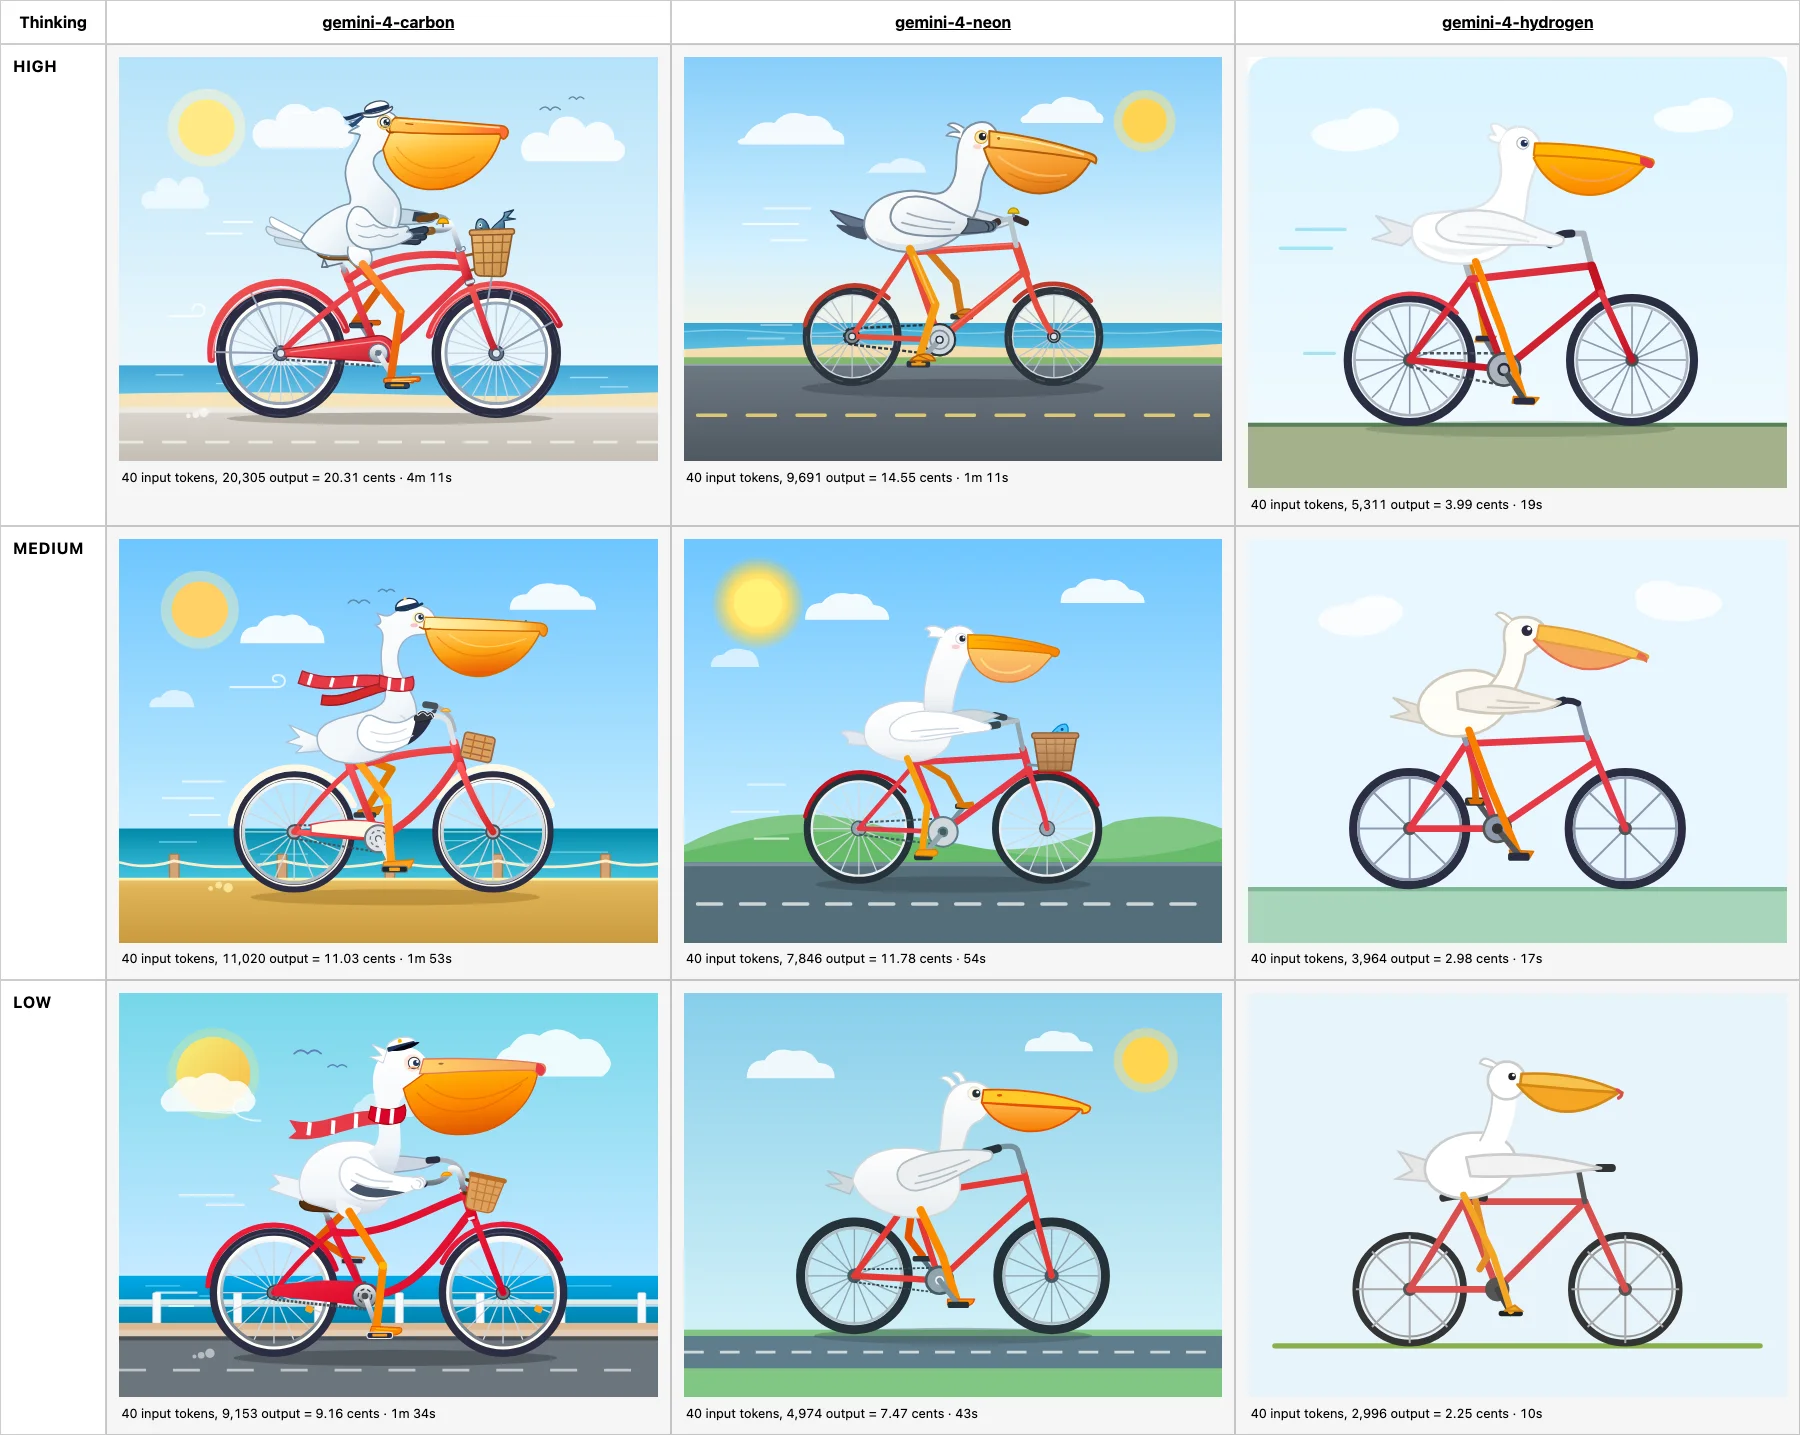
I ran some pelicans through the three reasoning levels for Neon - low, medium, high.
I dropped Argon from my Gemini 4 comparison grid - here's the new Gemini 4 lineup, where the Neon pelicans do look better than Hydrogen and worse than Carbon:
As I've done with several recent models, I also fired the following prompt against Gemini 4 Neon on "extra" effort level in Google Antigravity:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data
A bug fix release for LLM, mainly to cover a problem with the most recent Homebrew package of the software.
Homebrew now ships the latest SQLite, 3.54.1, which includes a fix that broke LLM's logging code.
Short version: in SQLite 3.54.0 the following SQL:
select json_object('a', (select json_array(1)))
Returns this:
{"a":[1]}
But in 3.54.1 the same query returns this:
{"a":"[1]"}
According to D. Richard Hipp:
That was a bug fix. Per the documentation, (SELECT json_array(...)) returns SQL text, not JSON. Hence the 3.54.1 behavior is correct and 3.54.0 was a bug.
The workaround looks like this:
select json_object('a', json((select json_array(1))))
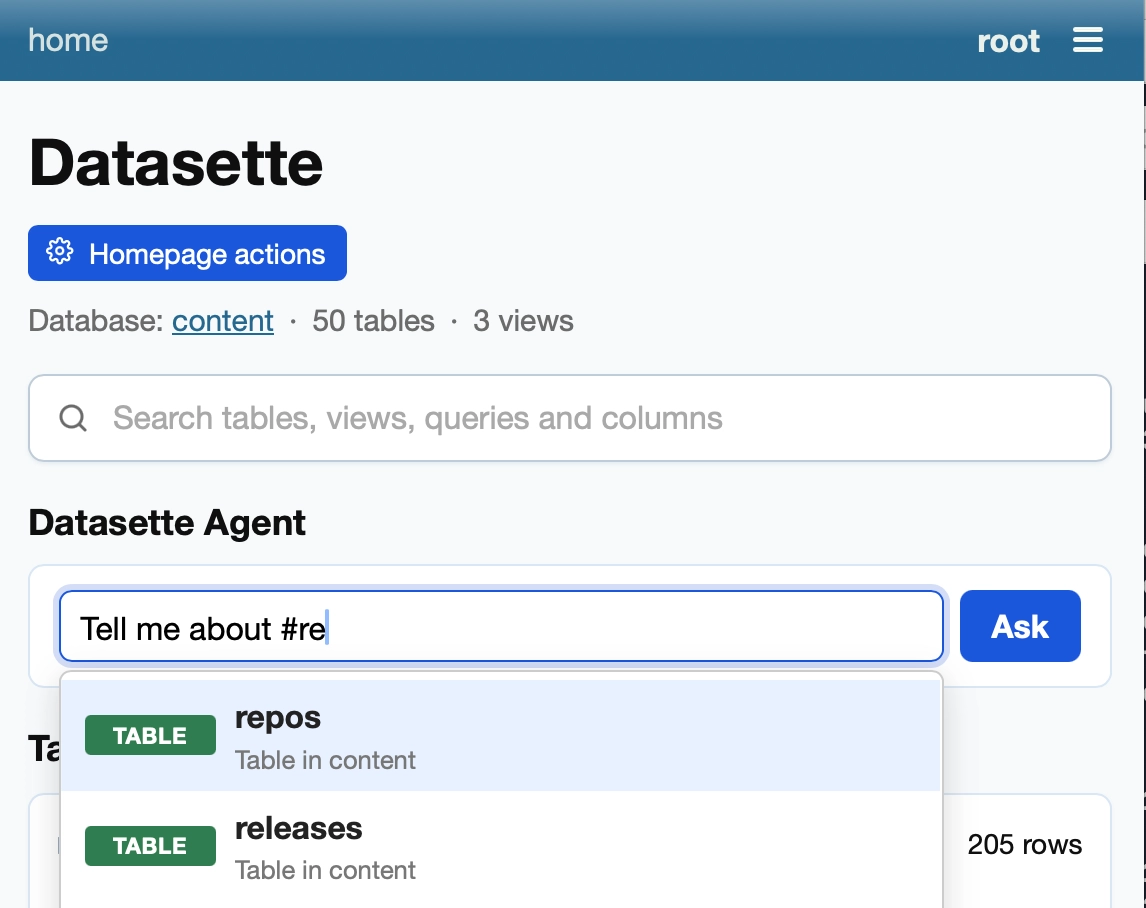
Accumulated small fixes for Datasette Agent, my agent plugin for Datasette that lets you ask questions about your data. Most notably, it now adds an agent prompt directly to the Datasette homepage, with support for hash-mentions of tables and queries:
datasette-llm is the intermediate plugin for Datasette that supports configuring LLMs for use with other Datasette plugins.
This release adds support for OpenAI-compatible endpoints, so you can configure Datasette to use an LLM hosted anywhere that talks the OpenAI pseudo-standard web protocol.
This means that if you're running local models with LM Studio or Ollama or llama.cpp (which just hit v1.0.0) you can run Datasette via uvx like this:
wget https://datasette.io/content.db

uvx --with datasette-agent datasette \
  --root --secret 1 \
  -s plugins.datasette-llm.default_model '{
    "model": "lmstudio-qwen",
    "model_name": "qwen/qwen3.8-27b",
    "api_base": "http://localhost:1234/v1"
  }' content.db
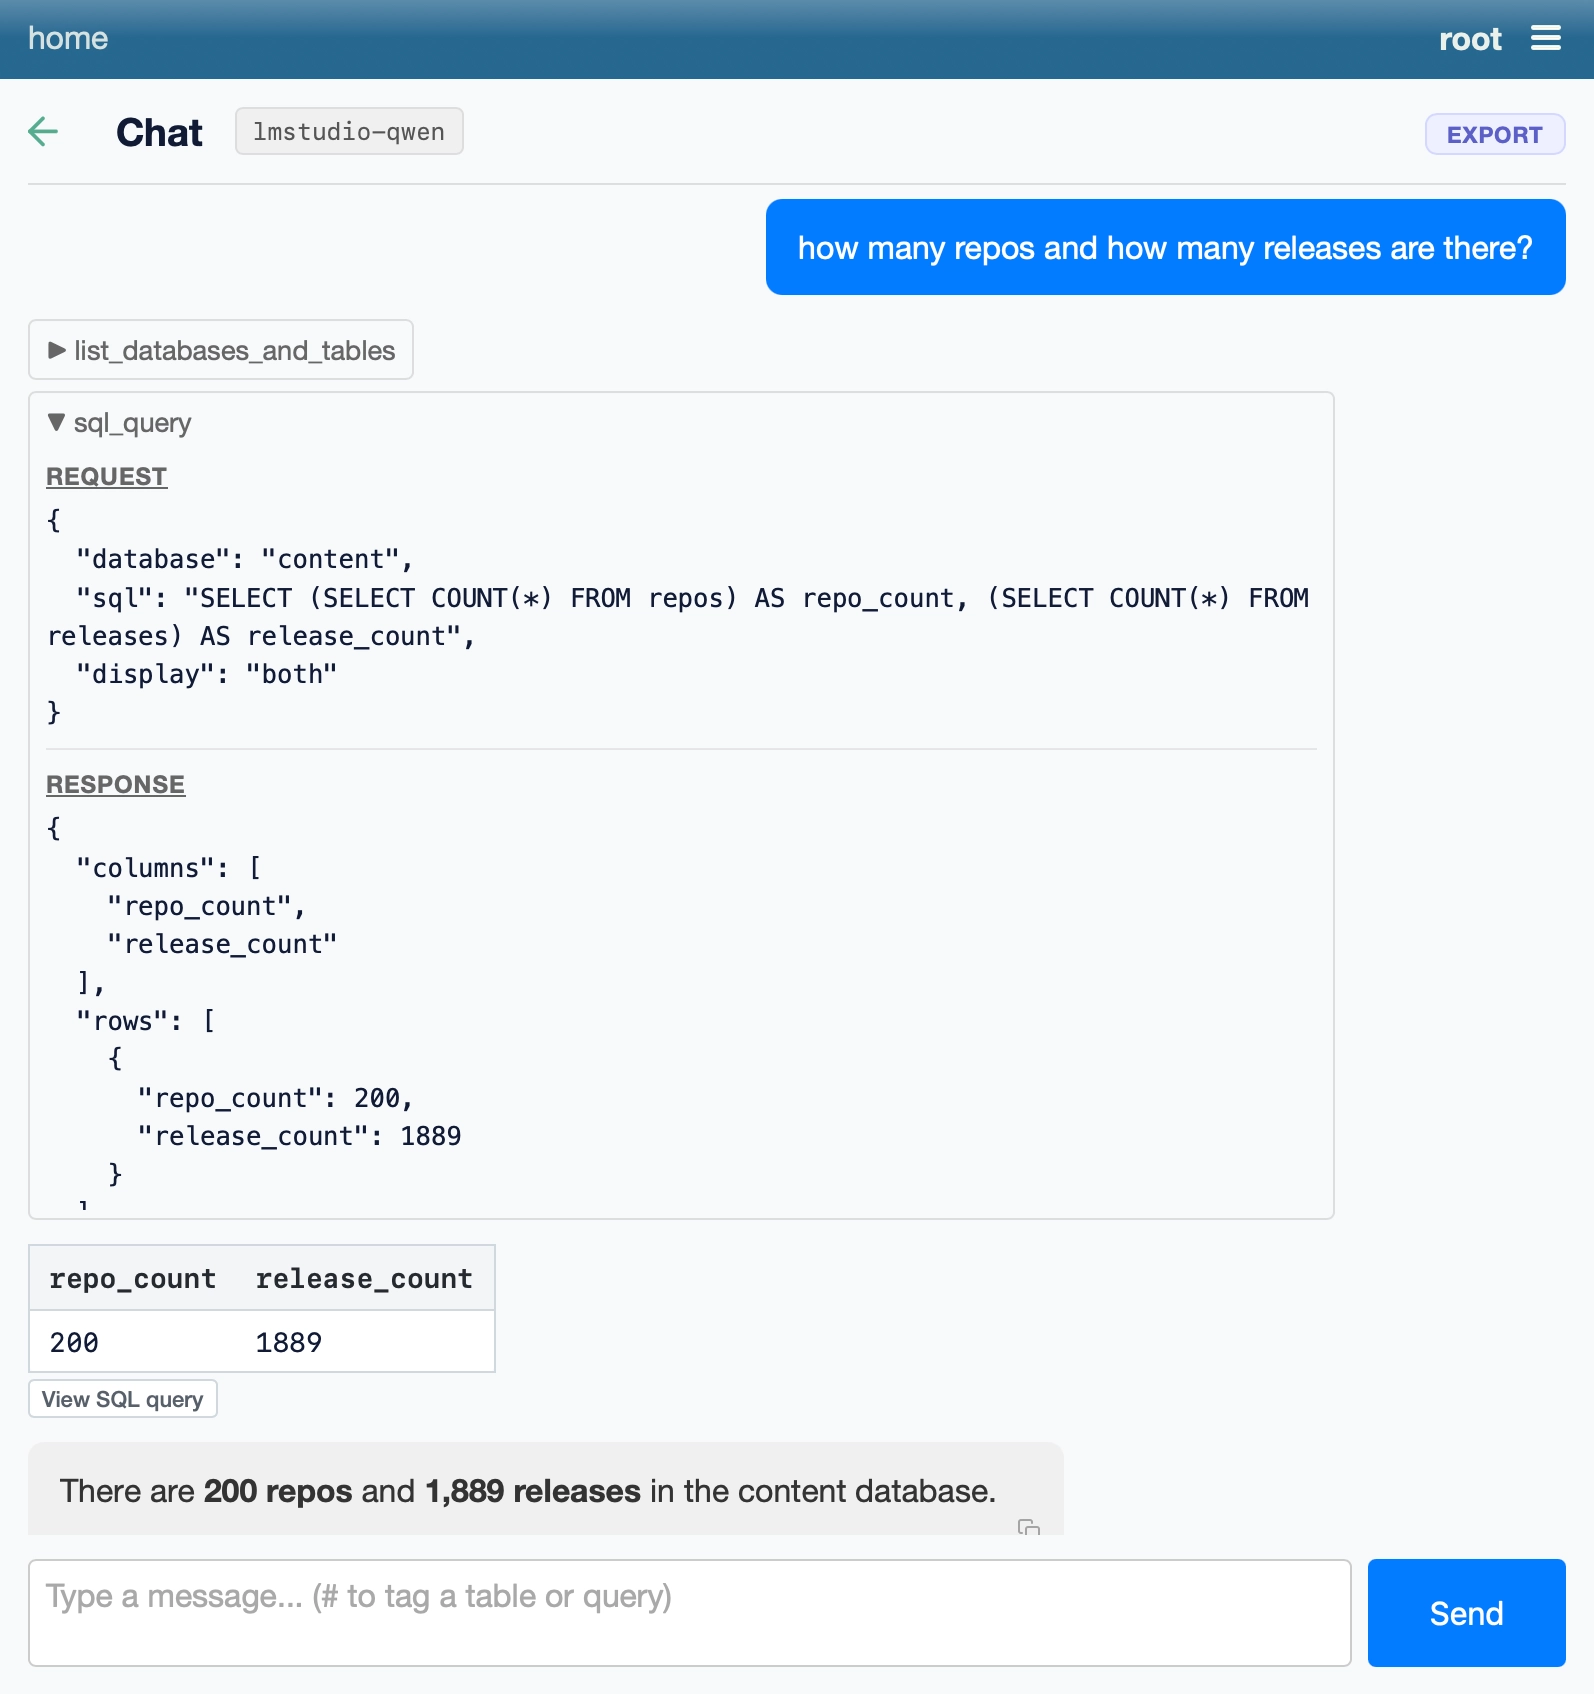
And you'll get a local server running a Datasette Agent instance powered by your local model!
Google launched Gemini 4 Hydrogen today - the lowest cost member of the Gemini 4 family.
It's actually not too far off the price of its much bigger siblings, Carbon and Argon. I'm finding Gemini 4's pricing really confusing. Here's the pricing scheme:
| Model | Dates | Input ($/M) | Cached input | Output |
|---|---|---|---|---|
| Gemini 4 Carbon | Through Nov 30, 2026 | $2.00 | $0.10 | $10.00 |
| From Dec 1, 2026 | $4.00 | $0.20 | $20.00 | |
| Gemini 4 Argon | Through Nov 30, 2026 | $2.00 | $0.10 | $10.00 |
| From Dec 1, 2026 | $4.00 | $0.20 | $20.00 | |
| Gemini 4 Hydrogen | $1.50 | $0.075 | $7.50 |
Carbon and Argon are the same price, and both are scheduled to double in price on December 1st. If they're the same price, why have two different models? Google says that Argon "delivers Gemini 4 intelligence with faster responses and lower token spend per turn compared to Gemini 4 Carbon" - so it may be priced the same, but it will use less tokens per task.
Hydrogen, supposedly the cheap model, is currently only a 25% discount on its more capable peers. The Hydrogen price will make more sense after December 1st, when it will represent a 75% discount. It's still considerably more expensive than Claude Haiku 5.5 and GPT-6 Luna - they're both $0.10/$0.50, so Hydrogen is 15x that.
I had Hydrogen generate some pelicans. Here's a full comparison grid showing the pelicans for all three members of the Gemini 4 family at their three supported effort levels:
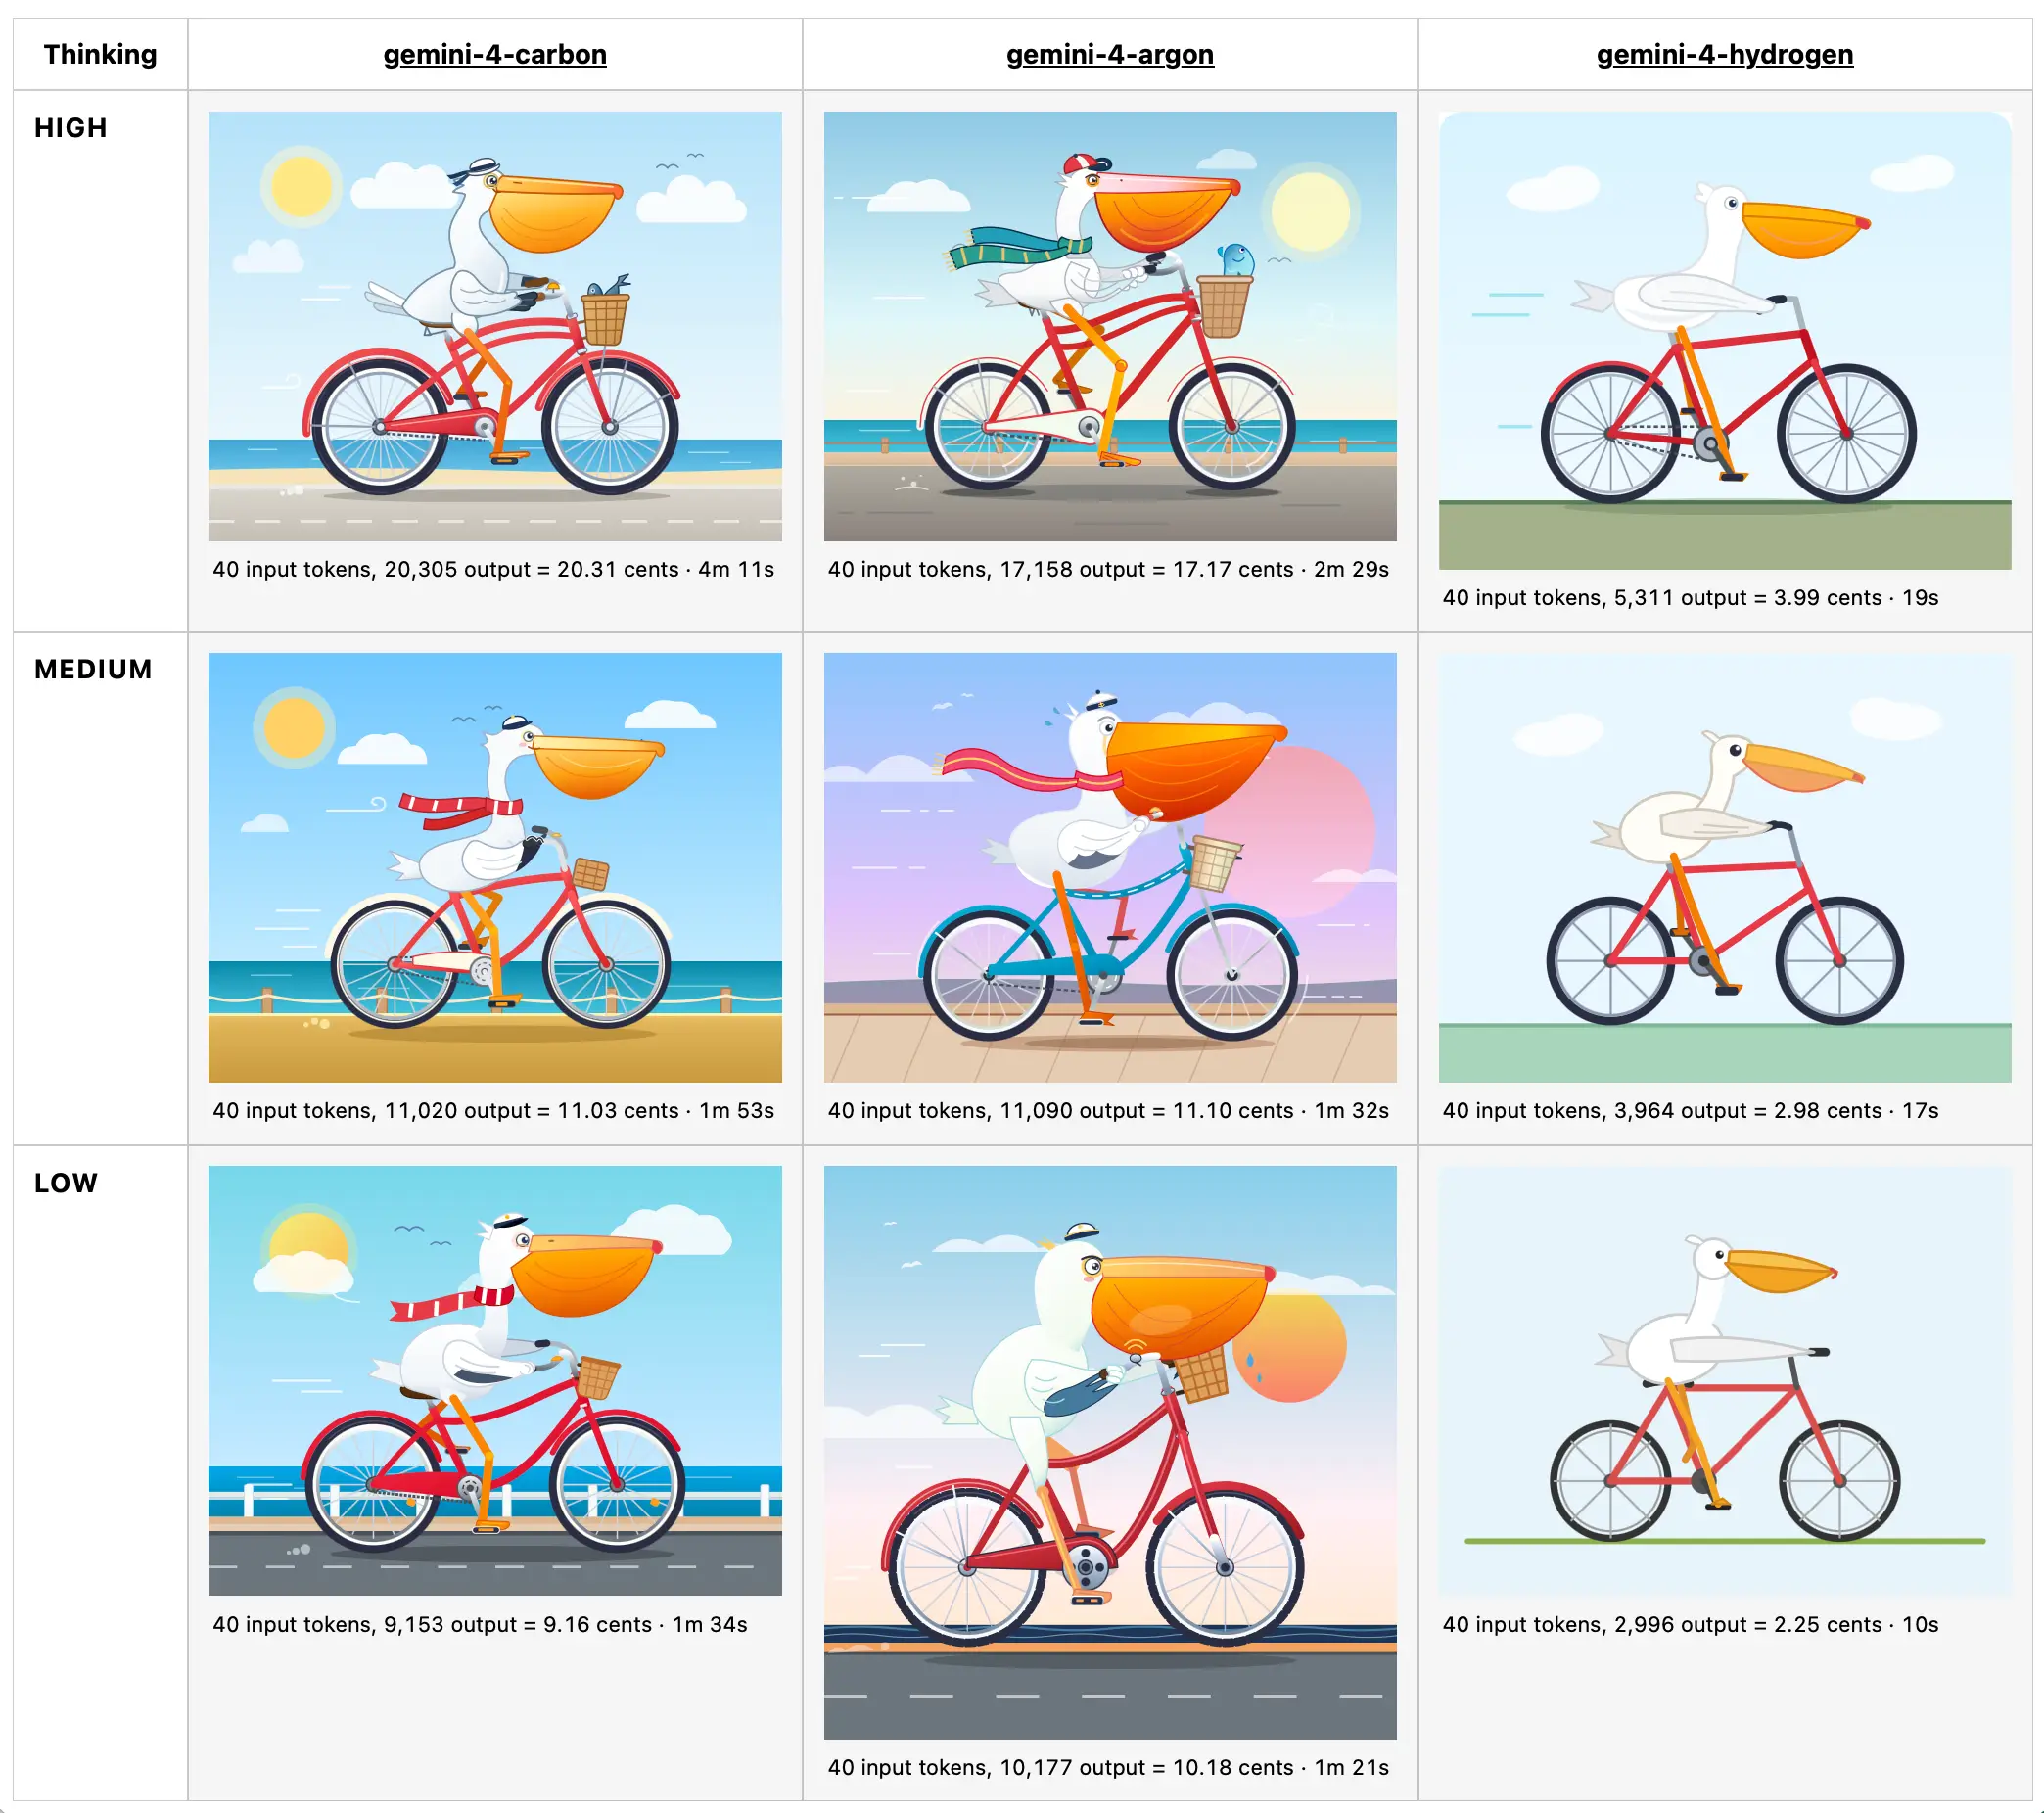
Considering how close they are in price, the difference in pelican quality for Hydrogen is quite stark.
Here's how Google describe Hydrogen's intended position in their mix of models:
In real-world software development, while teams rely on frontier models like Carbon and Argon for deep architectural judgment when designing systems or untangling subtle bugs, they still need a fast, disciplined execution model for writing code, running tests, and verifying changes. Hydrogen is built to stand on its own as a model for everyday work — or to pair with Carbon and Argon as the high-efficiency execution engine in multi-model workflows.
Most notably, Hydrogen is the new free tier model, and is the model that will power AI features in Google Search.
Fixes a security issue reported by Daniel de Araujo in GHSA-v9h7-jj4g-f862 and GHSA-r639-rr7r-x72w.
LLM has a mechanism called extra-openai-models.yaml - now managed by the new-in-0.37 llm openai endpoint add command - for using LLM with OpenAI-compatible API endpoints from other providers.
Daniel reported two ways this could accidentally send your configured OpenAI API key to one of those providers: if the key named by api_key_name had never been stored, or if a responses: true model was run with -o chat_completions 1.
Gemini 4 Carbon was announced two weeks ago for "a subset of cyber defenders", but today it's available to everyone else.
This is Google's best ever Gemini, priced at $2/million input and $10/million output at launch (that's GPT-6.1 Sol / Claude Sonnet 5.5 prices) but scheduled to double in price to $4/$20 on December 1st (same as Opus 5.5).
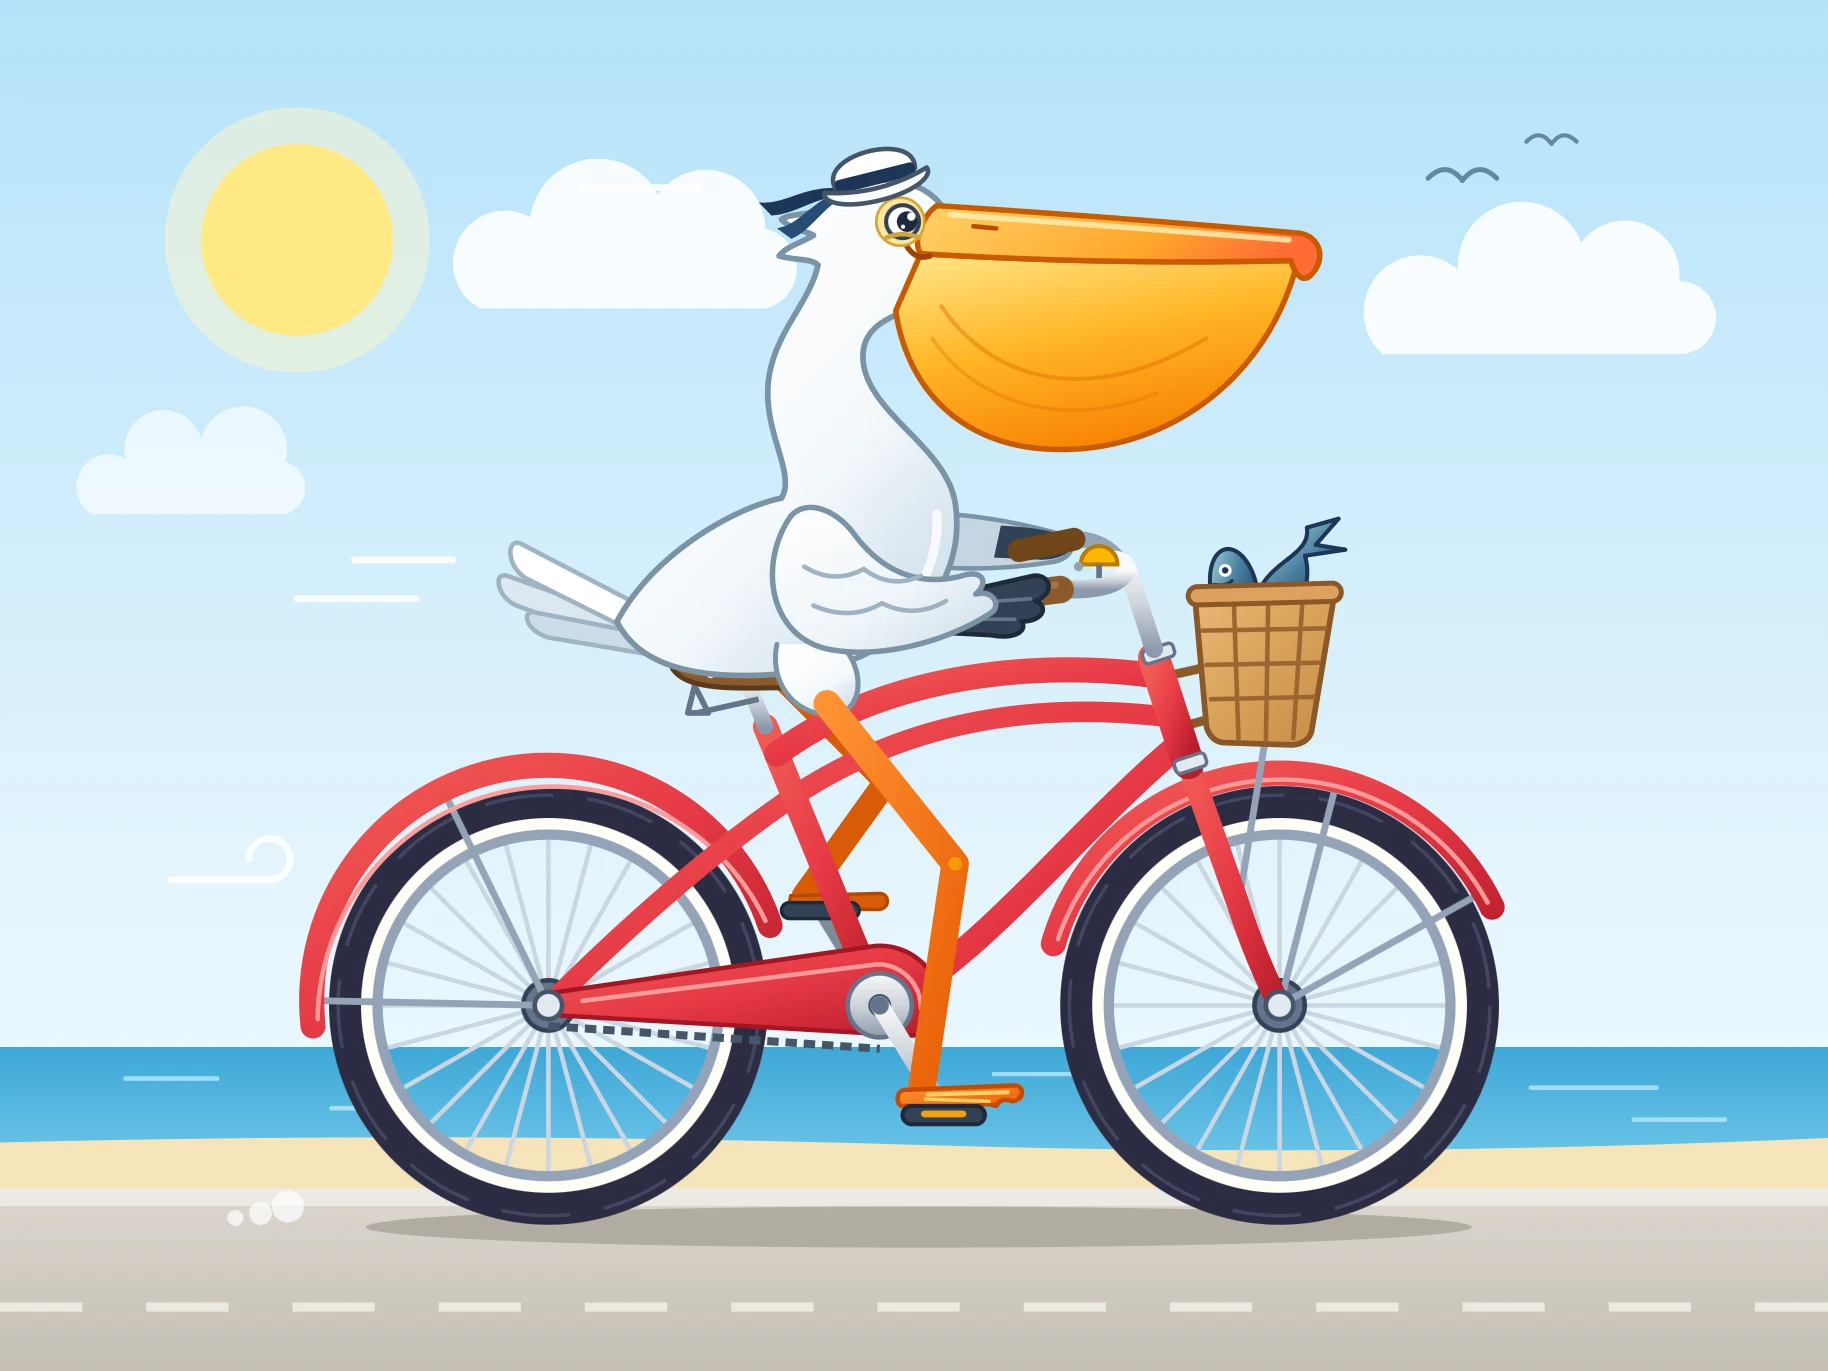
Here are three pelicans for the low, medium and high thinking efforts (it defaults to medium). This is the pelican I got for high:
Gemini pelicans have all been great for a while now, so I also tested it out using Google's Antigravity IDE with a prompt I first tried with Claude Fable 5.2 yesterday:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data
Here's the HTML result (I had to prompt "build that into a standalone HTML file" to get a version with no external dependencies). I then screen-captured that as a video:
Update: Huh, just saw this on YouTube (and tweeted by Google CEO Sundar Pichai):
Using Google Antigravity’s /swarm feature, Carbon built an open-world 3D game where you explore Google’s Mountain View campus as a pelican riding a GBike — coordinating subagents to model 3D assets in Blender from Omni and Nano Banana references, build the browser game in Three.js with WebGL shaders, and pair procedural Web Audio sound effects with Lyria music.
Here's the playable version in AI Studio.
Anthropic released Fable 5.2 and Mythos 5.2 today. Fable 5.2 is currently ranked first on Artificial Analysis. Anthropic say it "solved two open problems in the physics of black holes", so clearly their internal benchmarks have become more ambitious!
I've added the new models to llm-anthropic, so you can now run prompts through Fable 5.2 like this:
uv tool install llm
llm install llm-anthropic
llm keys set anthropic
# paste key here
llm -m claude-fable-5.2 "Generate an SVG of a pelican riding a bicycle"
I ran pelicans at all five reasoning levels - low, medium, high, xhigh, and max. You can see them all here - here's the best result I got, from xhigh:
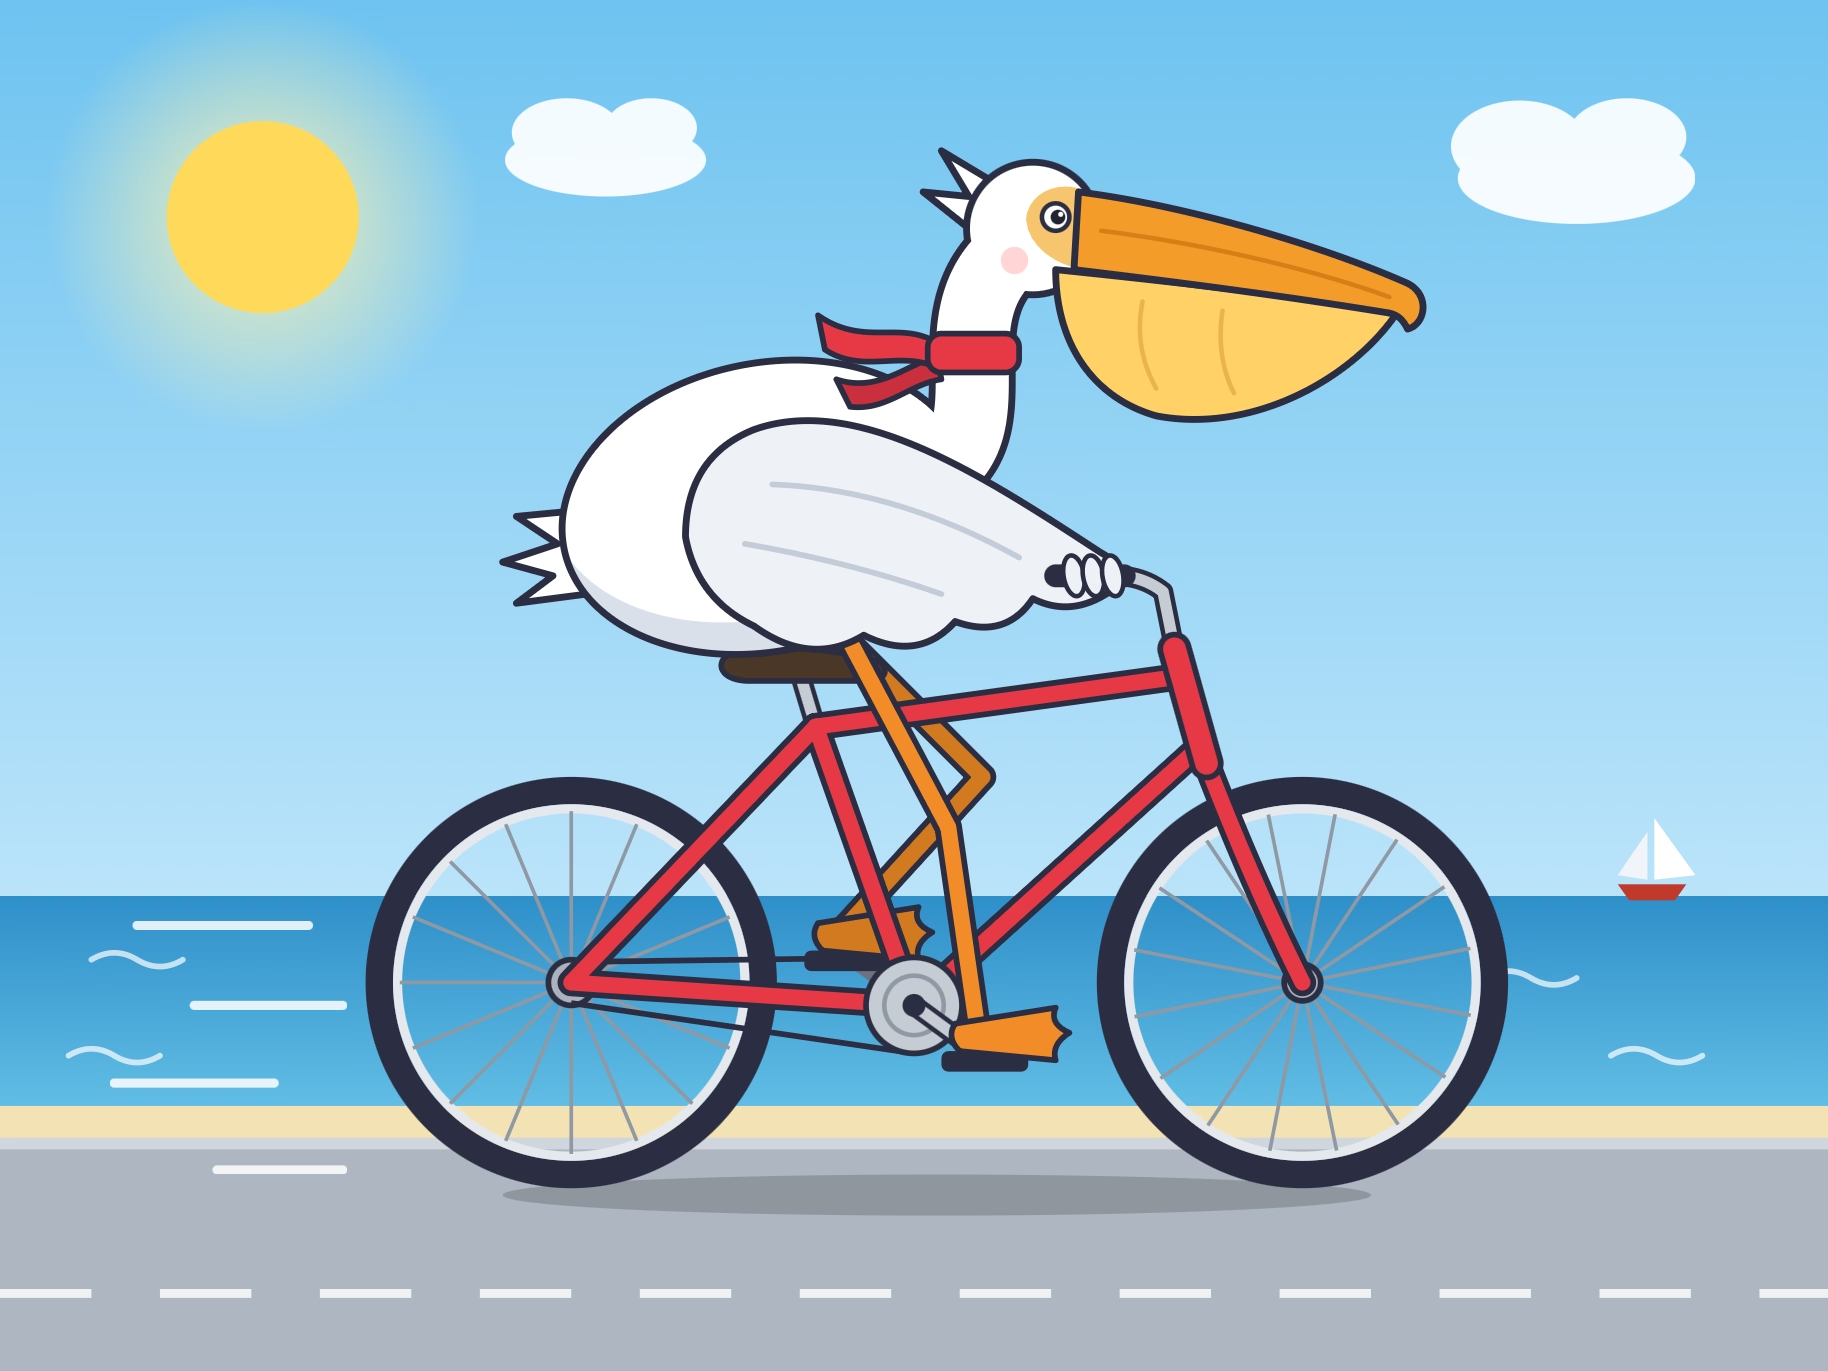
max failed to return an image at all, running out of tokens after spending 128,000 thinking about them. That's the same bug that I saw with Opus 5.5 - but it's new for the Fable series, both Fable 5 and Fable 5.1 returned max effort pelicans just fine.
It's priced at $8/million input and $40/million output, which is a 20% discount on the previous Fable 5.1 ($10/$50).
I also used Fable 5.2 to help identify the source of a mysterious beep.
Hide your slop PR descriptions behind <details><summary>
Most of the changes I make to my projects these days come in the form of PRs opened for me by Claude Code or Codex. The PR is my unit of work—I use them to bundle commits together, iterating on them until a feature is complete, document decisions and then merge the finished result. Today’s coding agents are great at writing PR descriptions.
[... 987 words]Fixes a bug that affected my agent.datasette.io demo site, where the set of available LLM models was not correctly restricted to just those in the configuration.
A bugfix release for LLM, with contributions from Steven Huang, Tao An, Arjan Mossel, and XQ.
There's a lot of stuff in this new release of my LLM CLI tool and Python library, representing around two months of accumulated features and fixes.
I added gpt-6.1-sol and gpt-6.1-terra, plus a new llm openai endpoint add command to make it easier to configure additional models that use OpenAI-compatible endpoints.
I switched the default model (if you have not set your own default) to gpt-6-luna - half the price of the previous default, gpt-5.6-luna.
LLM's support for embeddings now accepts that different binary content may have different content-type - necessary for models like Gemini Embedding 2, which can embed text, audio, images, and video.
A lot of open source maintainers complain about a flood of AI-assisted PRs. LLM is my project that has been most affected by this and, to be honest, I'm not finding it to be a problem. That's mainly because I have Opus 5.5 or GPT-6 Astra help me with triage to spot the most useful fixes!
This release includes fixes from 12 authors - almost all AI-assisted - and the burden of reviewing them wasn't nearly as great as I expected. I really see them as bug reports with attached examples - sometimes I land them, sometimes I implement my own fix.
So thanks to 0d00ciallo0721, ac1982, Allen Flux, Bian Yuhan, Bishop Kammeraad, Chen Yufeiyang, Christopher Krah, Ethan Stoner, Jiachen Xie, Olamide Faniyan, Sharat Chandra Sai Boddu, nosmile99 for helping out with (or spending tokens on) this release!
I have some big upgrades to Datasette Agent in the pipeline, but in the meantime here's a tiny user experience improvement to the underlying datasette-llm plugin.
It now picks up the default model used by LLM, which means you can start using Datasette Agent without needing to explicitly configure a default model:
uvx --with datasette-agent datasette content.db --internal internal.db
Previously you would also need to specify a model with -s plugins.datasette-agent.default_model gpt-6-astra.
Introducing Kimi K3.1 Pro (via) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".
They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).
The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.
Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.
Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).
This is the first time a (soon-to-be) open weight model has scored this highly against the frontier.
I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:
llm openai endpoint \
  https://api.moonshot.ai/v1 \
  --key kimi \
  -m kimi-k3.1-pro \
  "Generate an SVG of a pelican riding a bicycle" \
  --responses \
  -o reasoning_effort low \
  > kimi-k3.1-pro-pelican-low.stdout.txt \
  2> kimi-k3.1-pro-pelican-low.stderr.txt
llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).
Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:
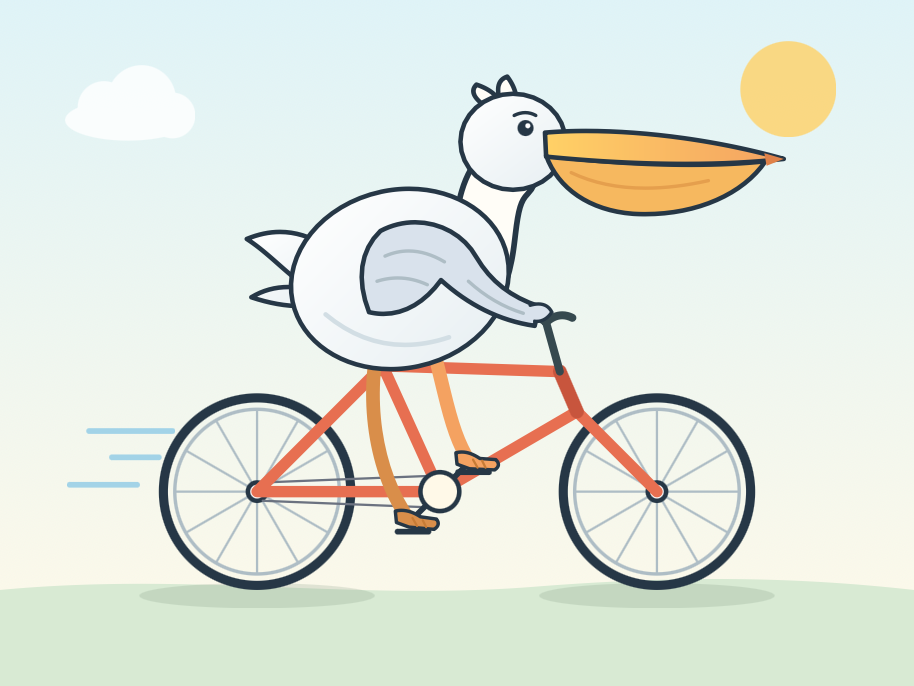
For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.
I'm working towards a new LLM release, and testing PRs caused me to revisit the llm-echo debug plugin. This plugin provides a "model" which doesn't involve an LLM at all - it just repeats back the prompts that have been fed to it. The new release now updates the simulated token usage counts to take tool calls, system prompts, and reasoning tokens into account.
Example usage:
uvx --with llm-echo llm -m echo 'hi there' -o thinking 1 --usage
Outputs:
First I consider the prompt, then I decide what to say.
{
  "prompt": "hi there",
  "system": "",
  "attachments": [],
  "stream": true,
  "previous": []
}
Token usage: 2 input, 24 output
I added support to llm-gemini for the new Gemini 4 Argon model, made available today via the Gemini API and for customers of their $100/month subscription plan.
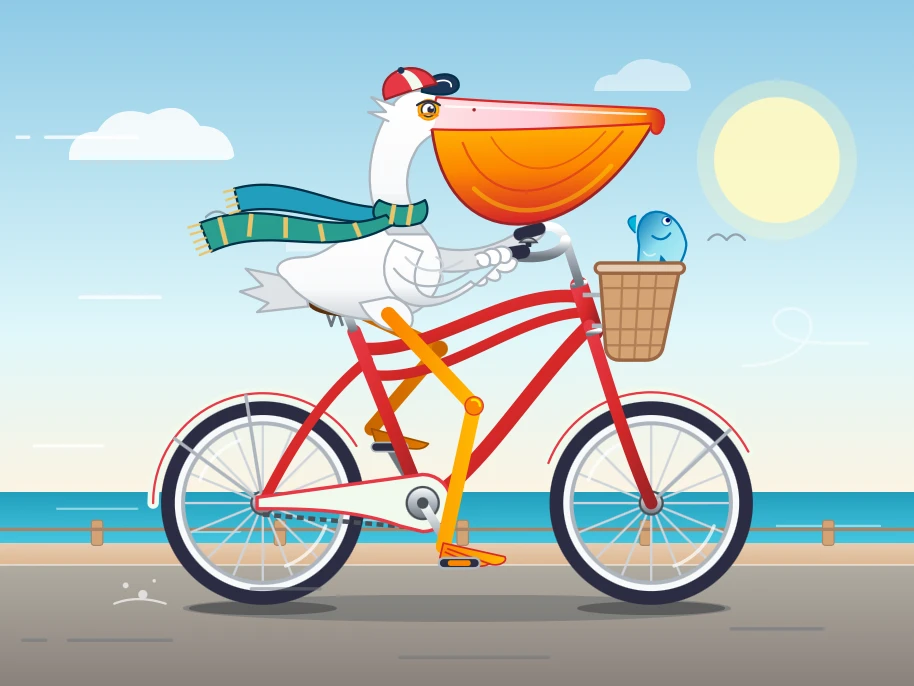
Here are the low, medium and high pelicans. As expected, they are all excellent: Gemini has a track record of producing great SVGs, and are the only lab where I know their staff have invested in SVG specifically (and who have boasted about their pelicans before.)
Here's the "high" illustration, which cost me 17.166 cents:
The pricing is interesting. At launch, Argon is $2/million input and $10/million output - the same price as GPT-6 Sol, half the price of Claude Opus 5.5 and 1/5th the price of Claude Fable 5.1 and GPT-6 Astra.
But on December 1st Argon is set to double in price - so it will be the same price as Opus 5.5.
Prices like this aren't really comparable these days since what really matters is how many tokens a model takes to achieve a goal within an agentic harness.
One useful clue for that comes from Artificial Analysis, who publish the total cost to run their benchmark using each model. Argon is looking very good there - costing $2,407 to run the benchmark, putting it close to GLM-5.3 and significantly cheaper than OpenAI, Anthropic, and Meta's latest models.
When the price doubles it will still be a little cheaper than GPT-6 Astra.
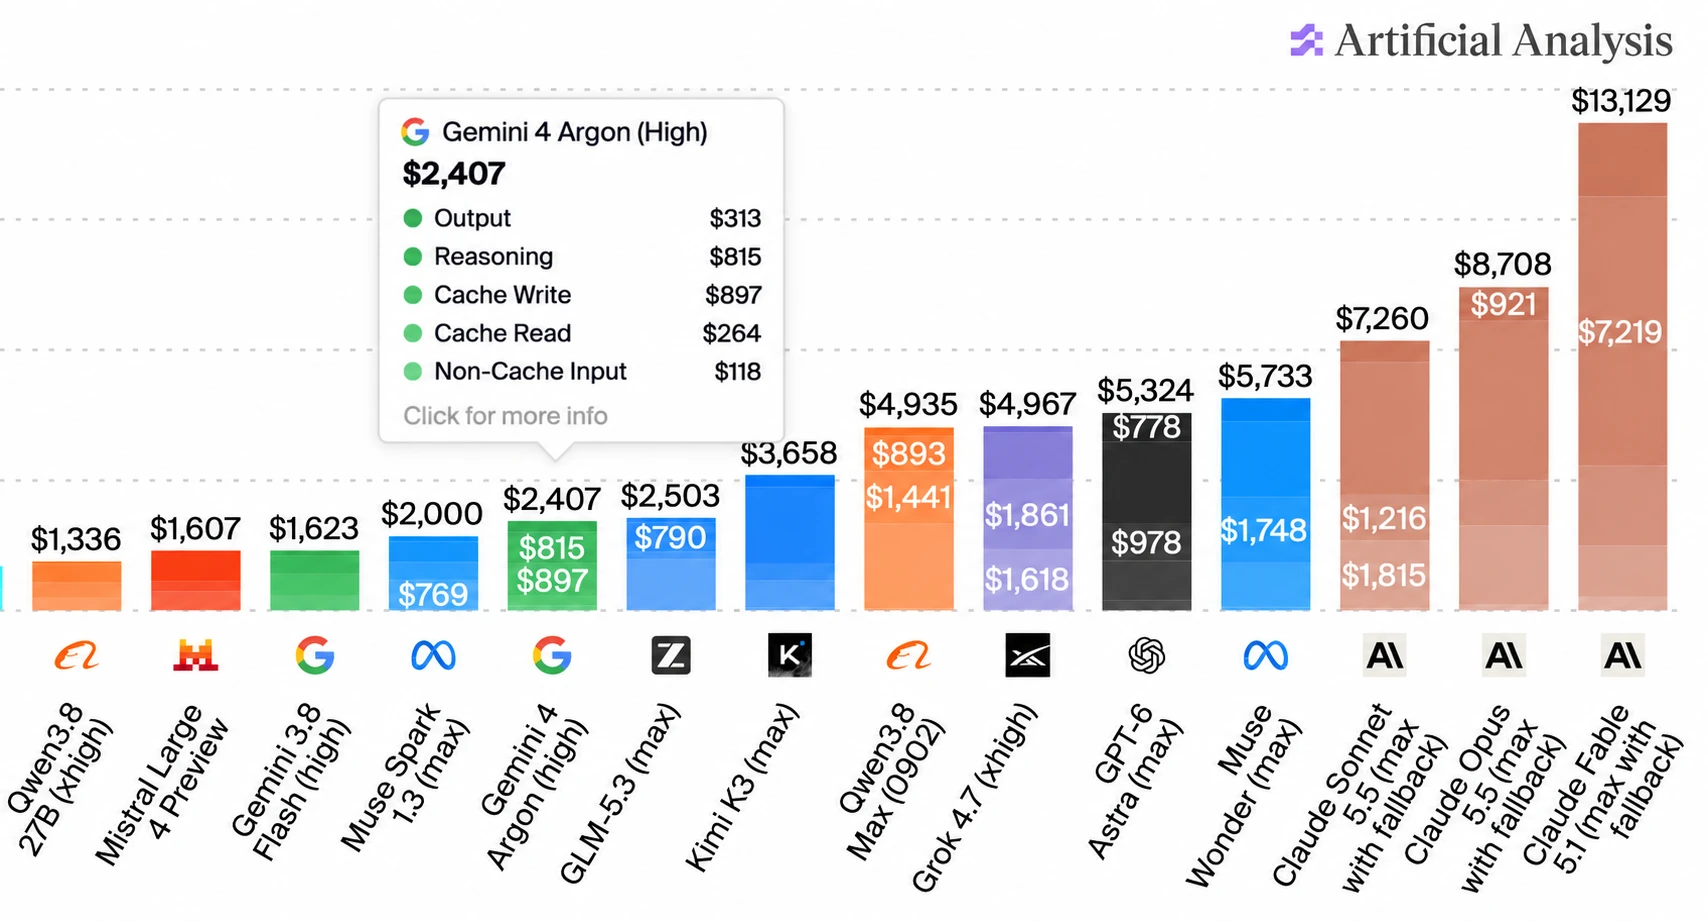
(I used ChatGPT to edit that chart! The data is all correct, I checked - I needed to get that Gemini 4 Argon info box to display without overlapping the other numbers.)
Some bonus examples using Gemini 4 Argon: here's Generate an SVG of an armadillo in fishnet tights jaywalking on Mars, here's a Fabergé egg it created for me using Blender, and DeepMind staffer @fofrAI shared a video of a pelican riding a bike, using fourier epicycles. That's a fun new twist!
OpenAI released their new Jev-style Decisions API, as previously announced at last week's DevDay.
Since I already have an llm-typesafe plugin for talking to Jev, I had GPT-6 Astra read the new OpenAI API documentation and build an llm-openai-decisions plugin inspired by llm-typesafe.
Unlike Jev, the new gpt-6-luna decision model supports image input in addition to text. Both models charge for input it and not for output: OpenAI's is 10 cents per million input tokens, Jev's is 4.2 cents per million.
Otherwise the API shape is very similar to Jev, at least conceptually. Jev supports three question types for yes/no, choices, or scores. OpenAI Decisions supports the same three types.
Install the plugin like this:
llm install llm-openai-decisions
Here's an example query against an image attachment:
llm -m openai-decisions/gpt-6-luna \
  -a https://static.simonwillison.net/static/2025/two-pelicans.jpg \
  -s 'Does this image contain any mammals?'
And example output:
{"type": "predicate", "name": "evaluation", "probability": 0.0}Consult the README for full details of how to run the other types of questions.
Adds support for reasoning models, such as the newly released Mistral Large 4.
In addition to Claude Sonnet 5.5, this release adds the ability to run llm anthropic refresh to refresh the list of Anthropic models directly from their API - which means I don't need to push a new release just to add support for a newly released model.
I also added an llm anthropic count command which can use their free token counting API to return a count of tokens that will be used by any prompt, before you send that prompt.
- New OpenAI models:
gpt-6-solfor GPT-6 Sol andgpt-6-lunafor GPT-6 Luna. #1702- Model plugins can now declare
supports_conversation = Falsefor models that only accept single-turn prompts. LLM raisesllm.ConversationNotSupportedwhen these models receive assistant or tool history, andllm chatrejects them before starting a session. See Models that do not support conversations. The first plugin to use this is llm-typesafe. #1692- Reasoning traces in the Markdown output of
llm logsare now wrapped in<details><summary>tags. #1701
Adds support for Claude Opus 5.5:
llm -m claude-opus-5.5 "prompt goes here"
I built this new plugin for LLM to add support for TypeSafe AI's new Jev model. Install it like this:
llm install llm-typesafe
Then set an API key (get one here, the waitlist seems to move pretty fast):
llm keys set typesafe
# Paste key
And now you can ask yes/no "noul" questions like this:
llm -m jev 'Please refund my last payment.' \
  -s 'Does this message explicitly request a refund?'
Output:
{"type": "noul", "noul": 0.99}
Or choice questions like this:
cat message.txt | llm -m jev \
  -s 'Which team should handle this message? If billing and technical issues both occur, choose billing.' \
  -o answer_type choice \
  -o criteria '{
    "billing":"Charges, invoices, payments, or refunds",
    "technical":"Problems installing or using the product",
    "other":"Neither category fits"
  }'
Or scoring questions like this:
cat report.txt | llm -m jev \
  -s 'How reproducible is the problem described in this report?' \
  -o answer_type score \
  -o criteria '[
    "No reproduction instructions",
    "Some instructions, but important steps are missing",
    "Complete steps with expected and actual results"
  ]'
See the README for more details.
This plugin solves a very specific problem.
I've started using Codex Remote to run coding agents on various machines while controlling them from my phone.
Sometimes I use those machines to hack on LLM projects, and occasionally that means I need to configure an API key.
I don't like pasting API keys into agent sessions, so I wanted a way to get those keys onto a machine without pasting them into the ChatGPT app directly.
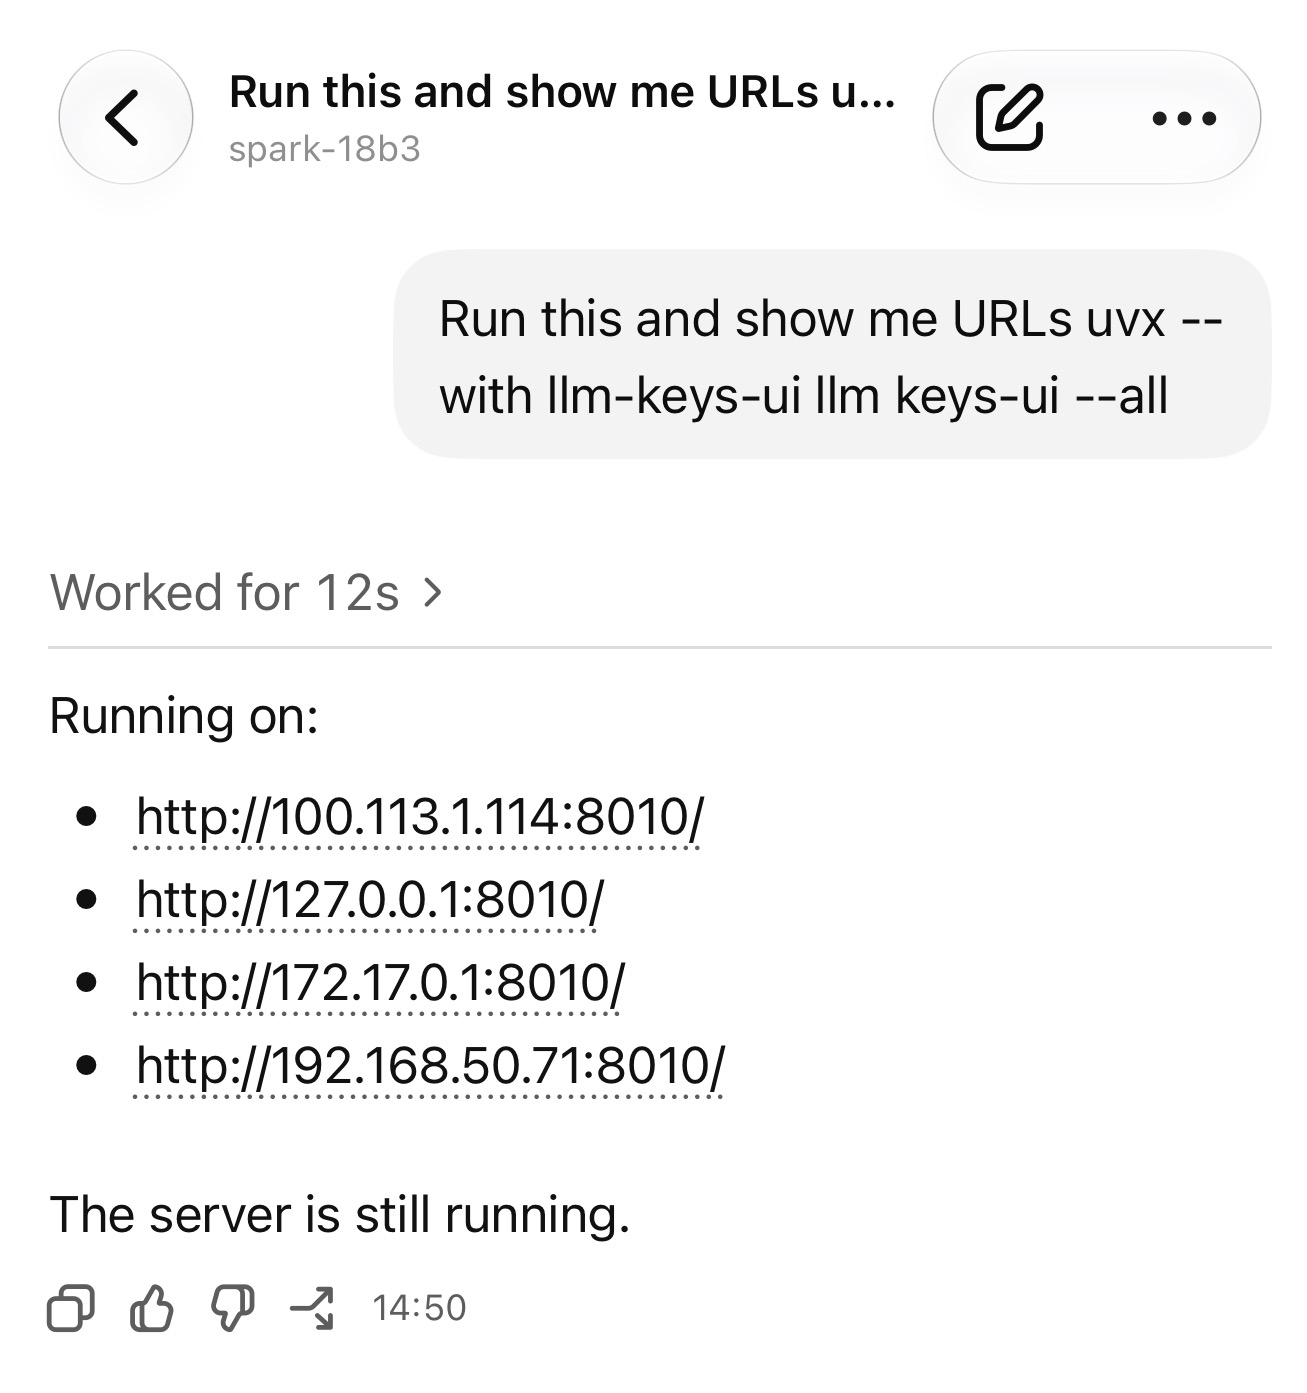
With this plugin, I can tell Codex to run:
uvx --with llm-keys-ui llm keys-ui --all
Then have it tell me the URL - including local network or Tailscale device IPs - for an interface to save additional API keys.
Then later it can use a command like llm keys get anthropic as part of a shell command when it needs to use a key.
- New OpenAI model:
gpt-6-astrafor GPT-6 Astra.
One new feature:
llm logs --usageMarkdown output now includes the response duration in milliseconds and as a human-readable duration.llm logs --shortincludes a newduration_msfield. #1653
Plus several contributed bug fixes, and a significant performance improvement to llm logs thanks to waveplate on GitHub, see also llm-openrouter 0.7.1.
Claude Fable 5.1, reasoning traces are now displayed by default for models that support them, plus a new llm_anthropic.ClaudeRefusal exception for when Claude throws a refusal.
- New model
gemini-3.8-flashfor Gemini 3.8 Flash, with low, medium and high thinking levels. #146- Fixed async responses failing to record the resolved model version. Thanks, Charlie Tonneslan. #137
Google released Gemini 3.8 Flash (and 3.8 Flash Cyber, but that's available to "trusted defenders" only) today.
Here are the pelicans for high, medium, and low. This is high:
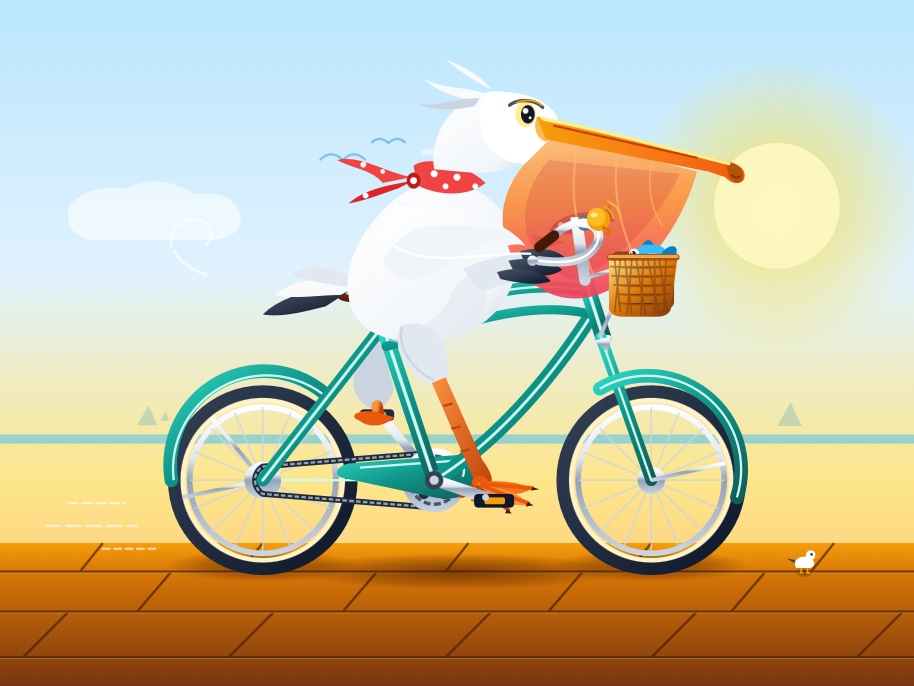
For comparison, here are the same pelicans generated using Gemini 3.7 Flash.
Something I appreciate about Gemini Flash is that it's fast, cheap, and competent at things like HTML and JavaScript. I was messing around with it and prompted "make me a cool thing in html" and it built this, which is certainly a cool thing in HTML! Took 13 seconds, cost 1.8 cents.
If you click through to the demo you'll see one more thing I built with Gemini 3.8 Flash.
My markdown-svg-renderer tool lets me feed in the URL to a Gist with Markdown in and renders that markdown with fenced code blocks for SVG correctly rendered.
I used Gemini 3.8 Flash (with my very basic llm-coding-agent coding agent plugin) to add support for HTML as well, so now any HTML blocks in the Markdown are rendered using a sandboxed iframe. Here's the transcript.
This release of the Anthropic plugin for LLM mainly provides compatibility with the recently released anthropic v1.0.0 Python library, which switches from httpx to httpx2. OpenAI made the same change in their v3.0.0 release two weeks ago.
Anthropic provide this migration guide for upgrading to 1.0, so I prompted Fable 5 in Claude Code with:
Upgrade to anthropic>=1 - read https://raw.githubusercontent.com/anthropics/anthropic-sdk-python/refs/heads/main/MIGRATION.md and get the tests passing
Here's the resulting PR.